Introduction
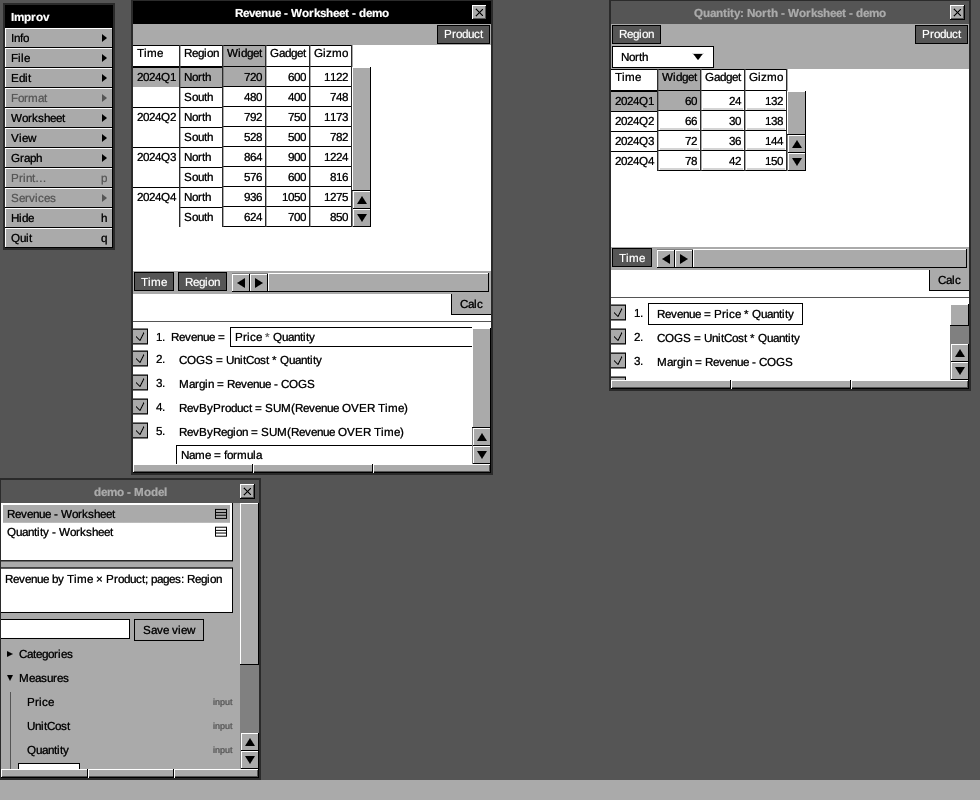
Improv is a cross-platform multidimensional spreadsheet written in Rust, in the line of Lotus Improv and Quantrix. It separates three things a traditional grid tangles together:
- Structure: the named dimensions of a model (categories and their items).
- Logic: formulas over dimensions, not cell addresses.
- Data: the raw input values.
You model in named categories, items and measures instead of A1
cell coordinates:
Revenue = Price * Quantity
Total   = SUM(Revenue OVER Time)
Derived values flow through a differential-dataflow graph, so recalculation is always incremental: an edit propagates only to the cells it actually affects.
One model, many ways in
The same model opens in a NeXTSTEP-style desktop GUI, a terminal UI,
a scriptable CLI, a streaming pipe, a JSON HTTP server, and
inside Postgres, where pg_improv keeps results current as your tables
change and LANGUAGE improv turns a formula into a SQL function. A model is
a single store file, or lives in a Postgres database. Ways to Use
Improv says which to reach for and when.
Status
Version 0.10.0 builds and passes its tests on Linux, macOS and Windows; the
Postgres extension supports Postgres 15 to 18. External functions in Python, R,
Julia or Pure run under a bubblewrap sandbox on Linux; WebAssembly functions
run in-process with fuel and memory limits. On other systems they are
refused unless the operator sets IMPROV_EXTFN_ALLOW_UNSANDBOXED=1. The
GUI has no Save As, Open or Print yet, and the Postgres connection has no
TLS (use a loopback port or an SSH tunnel). See the
changelog
for what changed in each release.
Reading order
- Ways to Use Improv: pick a front end.
- The Improv Model: categories, items, measures, coordinates.
- Getting Started: build a model from the CLI.
- The Formula Language: dimension-aware formulas and aggregation.
- The Desktop GUI and Improv in Postgres.
- Architecture & Design and Storage & Persistence: how it works inside.
Ways to Use Improv
Improv is one modeling engine with several front ends. They all work on the same model: categories, items, measures, formulas, input cells and saved views. A model built in one opens in every other. Pick the one that fits the job, and switch when the job changes.
| You want to… | Use | Where the model lives |
|---|---|---|
| explore a model, pivot it, edit numbers, add formulas with a mouse | the desktop GUI | a store file, or Postgres |
| do the same over SSH or in a terminal | the TUI | a store file, or Postgres |
| script a model, build it in CI, diff it, load data in bulk | the CLI | a store file, or Postgres |
| push a live feed through a model and get the changed results out | streaming | a store file, or Postgres |
| model data that already lives in Postgres, and read results with SQL | pg_improv | Postgres tables plus the improv catalog |
| write a SQL function as a formula | LANGUAGE improv | the function body |
| run a formula or a model over data in DuckDB, from SQL | the DuckDB extension | nowhere: computed per query |
| serve a model to other programs over HTTP | the server | a store file, or Postgres |
The model, wherever it lives
A store file (model.db) is a single SQLite file holding the model as
Mentat datoms: one file to copy, mail or check in. Every
front end takes its path.
A Postgres model is named by a URL instead of a path:
postgres://user@host/database?model=plan
Pass that URL to the CLI, TUI, GUI or server and they work on the model
stored in that database's improv schema. When the pg_improv extension is
installed, input measures can be bound to columns of your own tables:
the GUI then edits those rows, and SQL sees every result. See
Improv in Postgres.
Two writers never silently overwrite each other. If someone else saved after
you loaded, your save is refused with a conflict; choose File ▸ Revert to
Saved (GUI) or press R (TUI) to pick up their changes, then redo yours.
The desktop GUI (improv-gui)
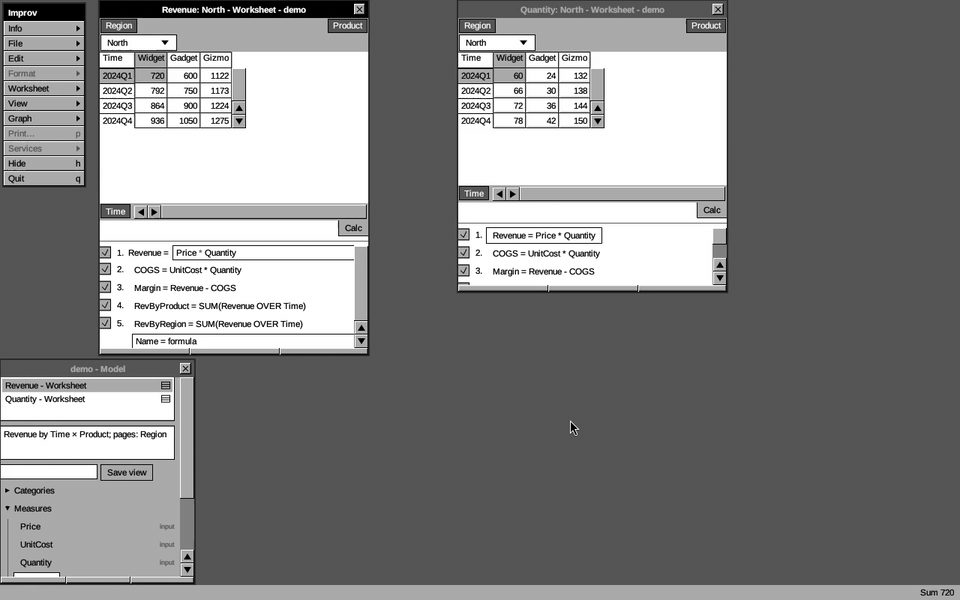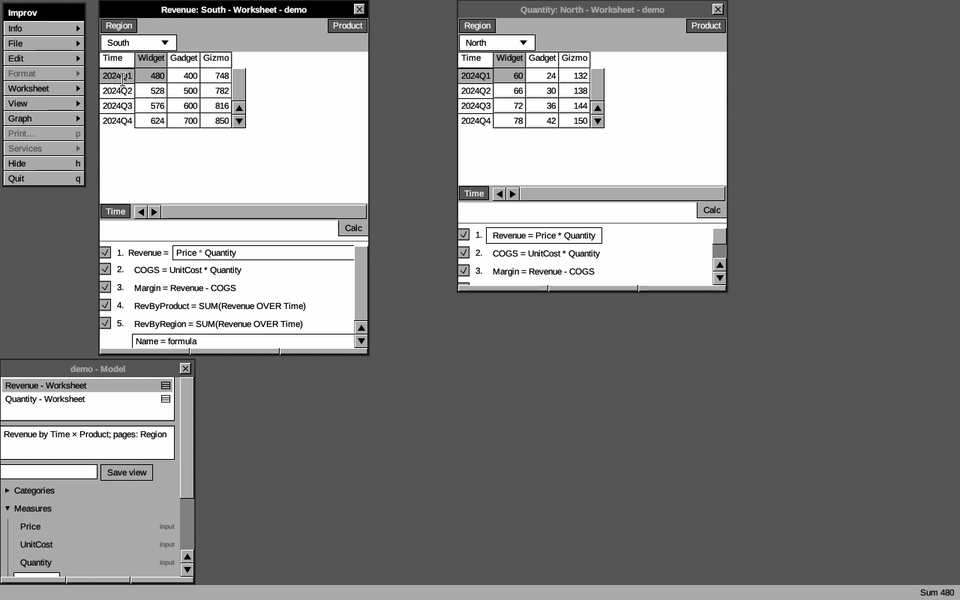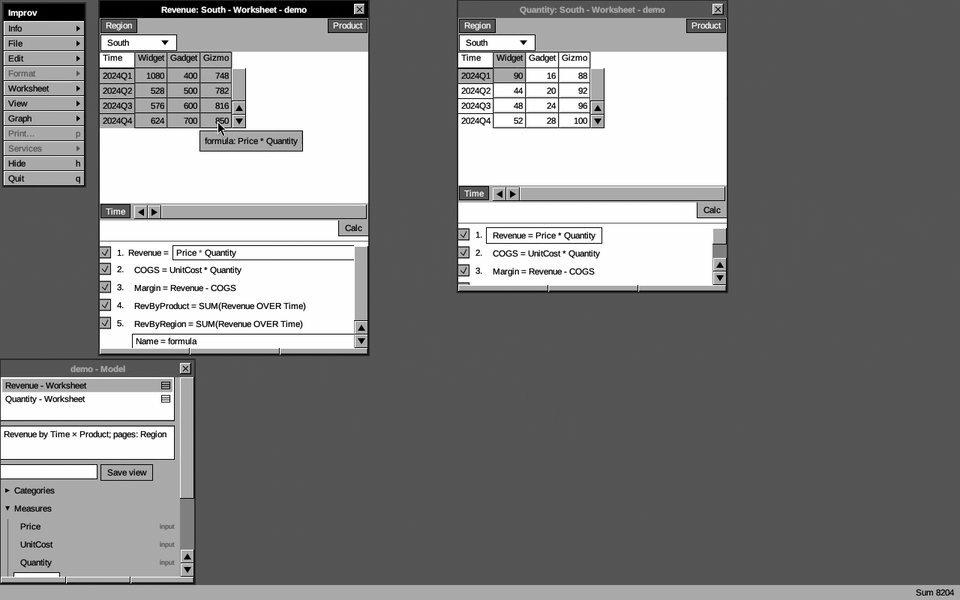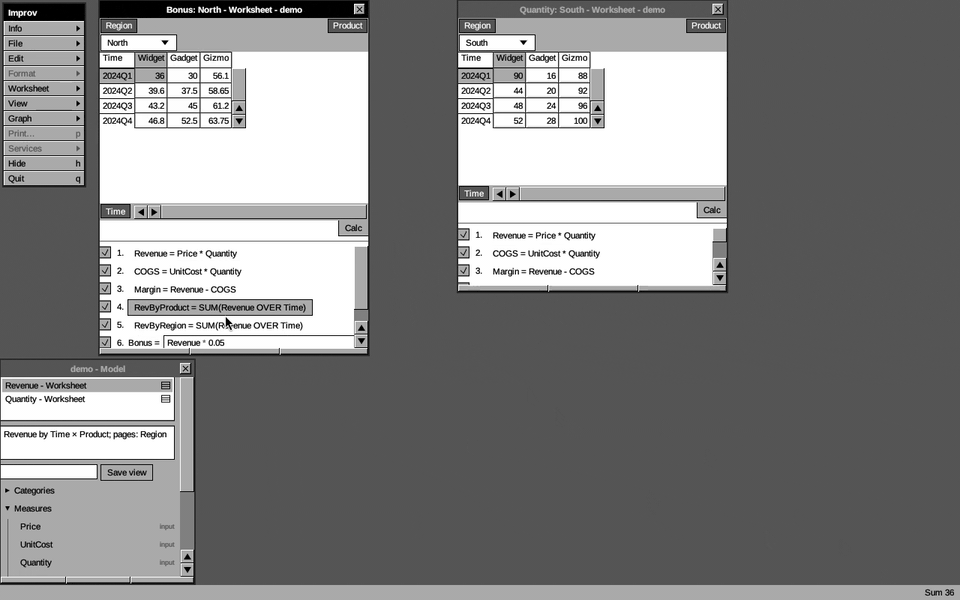
Use it for: building and exploring a model by hand. You see several views at once, pivot by dragging, chart, and watch derived cells recompute as you type.
improv-gui sample.db
improv-gui 'postgres://me@127.0.0.1/sales?sslmode=disable&model=plan'
- Pivot: drag a category tile between a worksheet's strips. Page tiles go top-left, column tiles top-right, row tiles in the bottom strip.
- Edit: double-click a cell. Derived cells are read-only; hover one to see its formula.
- Add a formula: type
Margin = Revenue - COGSon the last line of the formula list. - More views: Worksheet ▸ Add Matrix opens another worksheet on the same model; Save View keeps the arrangement.
Every change is saved as you make it. The Desktop GUI walks through each window.
The terminal UI (improv-tui)
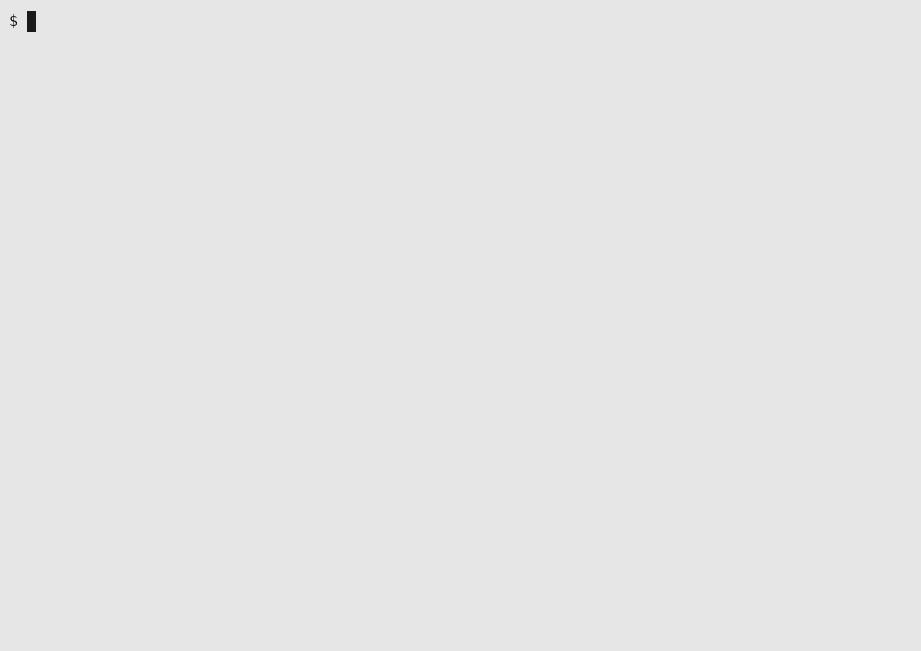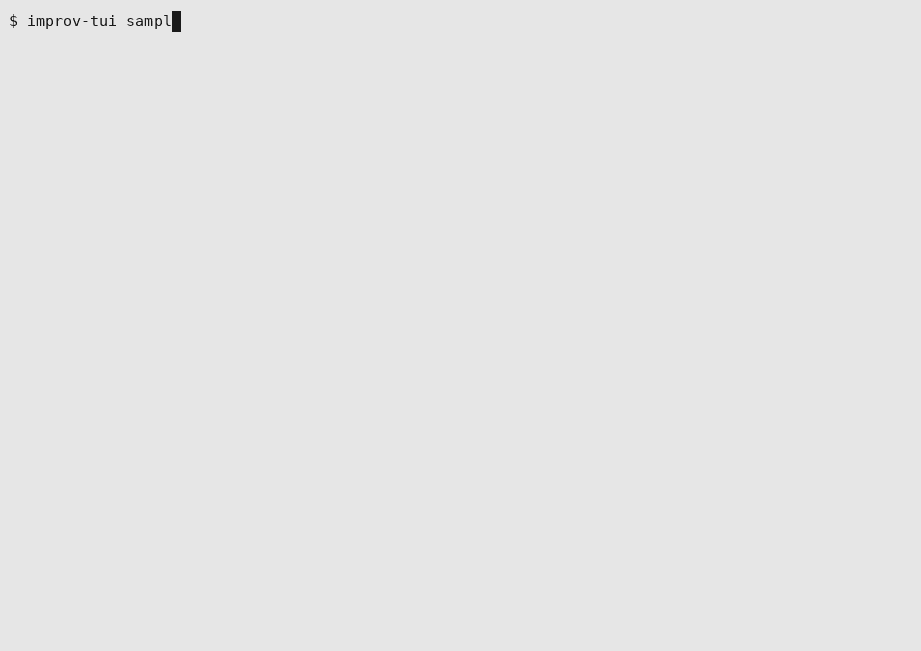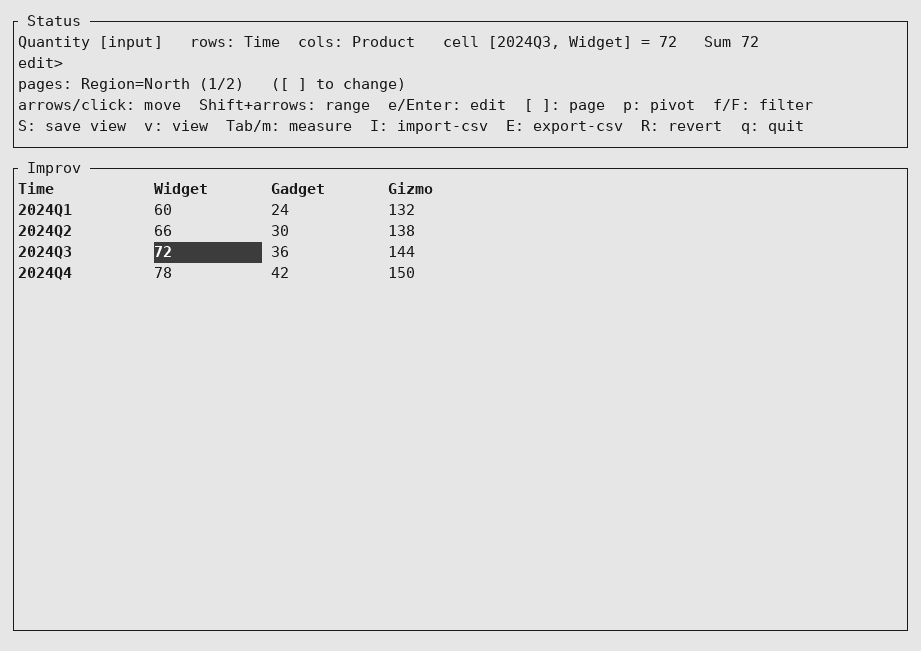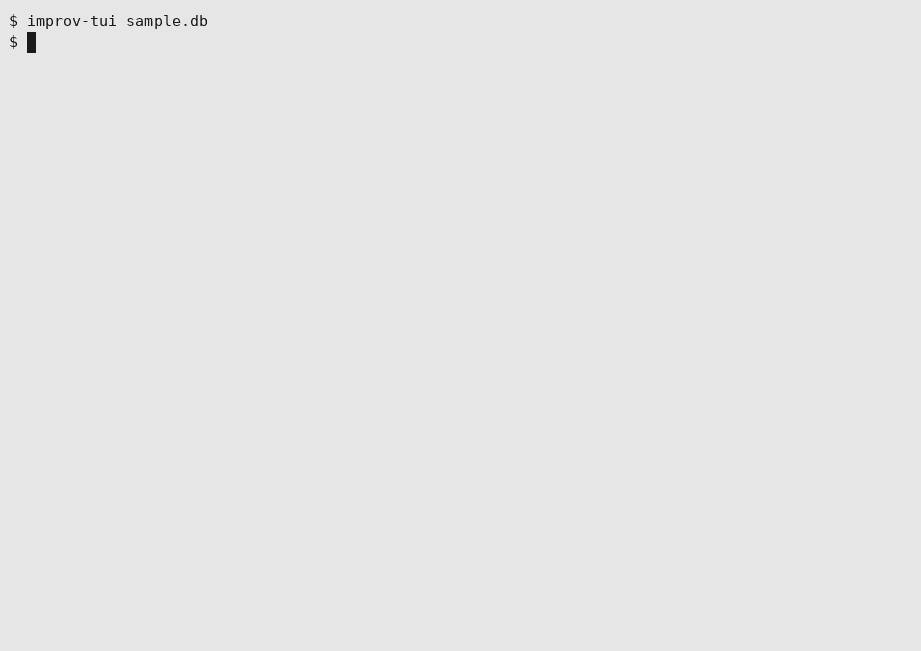
Use it for: the same pivot-and-edit loop without a display, over SSH, or in a tmux pane next to your logs.
improv-tui sample.db
| Key | Does |
|---|---|
| arrows, click | move |
e / Enter | edit the input cell (derived cells recompute live), or a derived measure's formula; a parse error is marked under the bad token, with a hint |
Tab / m | next measure |
p | pivot |
[ ] | page |
| Shift+arrows | select a range; its sum shows in the status line |
f / F | hide a row item / clear filters |
S / v | save the layout as a view / cycle views |
I / E | import / export CSV |
R | revert to the saved model |
| Tab (in a formula) | complete a function, measure or category name; again to cycle |
? / F1 | search the functions; Enter inserts NAME( into the edit |
q | quit and save |
The CLI (improv)
Use it for: anything you want to repeat. Build a model from a script, load a CSV or SQL query into a measure, evaluate a formula in CI, export results, or check a model into git as the script that builds it.
improv init m.db
improv add-category m.db 1 Time;    improv add-item m.db 10 1 Q1
improv add-category m.db 2 Product; improv add-item m.db 20 2 Widget
improv add-measure m.db 100 Price    number input Product
improv add-measure m.db 101 Quantity number input Time Product
improv set m.db 100 10  --at Product=Widget
improv set m.db 101 100 --at Time=Q1,Product=Widget
improv define m.db 102 "Revenue = Price * Quantity"
improv eval m.db 102
It also imports and exports CSV and SQLite (import-csv, import-sql,
refresh-sql, export-csv, export-sql), runs Python functions in a
sandbox (register-ext, CALL(...)), and keeps external measures fresh on a
schedule (serve-refresh). Getting Started is a
tutorial; man improv lists every command.
Streaming (improv stream)
Use it for: a live feed. Something produces new numbers, and you want the derived results that change, as they change, without recomputing the model.
tail -F prices.log | improv stream m.db Revenue Margin | your-consumer
Each input line is <measure> <value> [Cat=Item,...]. Improv applies it to
a live incremental engine and prints only the target cells it changed:
$ printf 'Price 15 Product=Widget\nQuantity 8 Time=Q1,Product=Widget\n' \
    | improv stream m.db Revenue
Revenue Time=Q1, Product=Widget = 1500
Revenue Time=Q1, Product=Widget = 120
(Price 15 × the stored Quantity 100, then 15 × the new 8.)
A bad line is reported on stderr and skipped. At end of input the final state is saved to the model.
In Postgres (pg_improv)
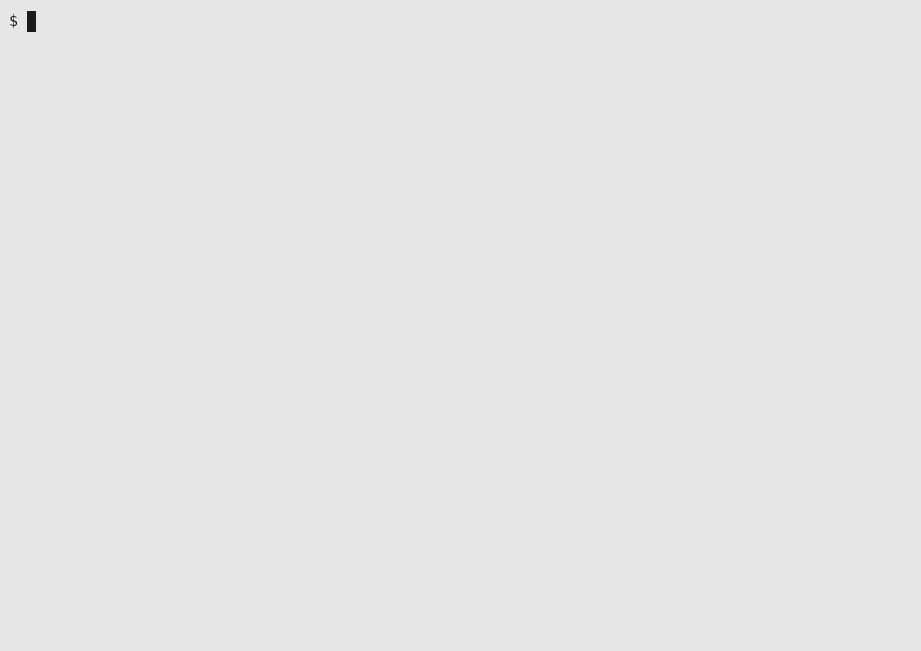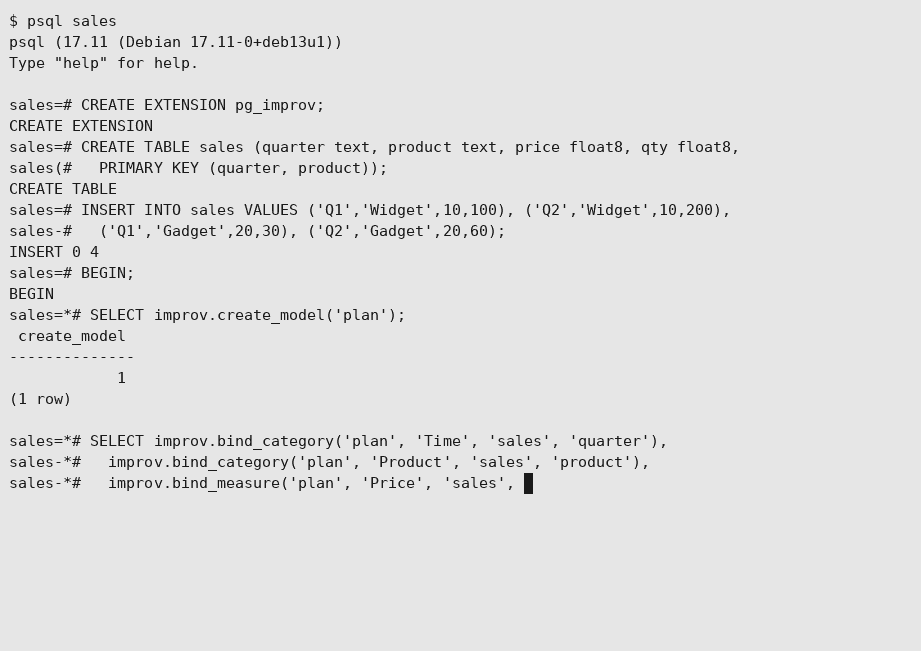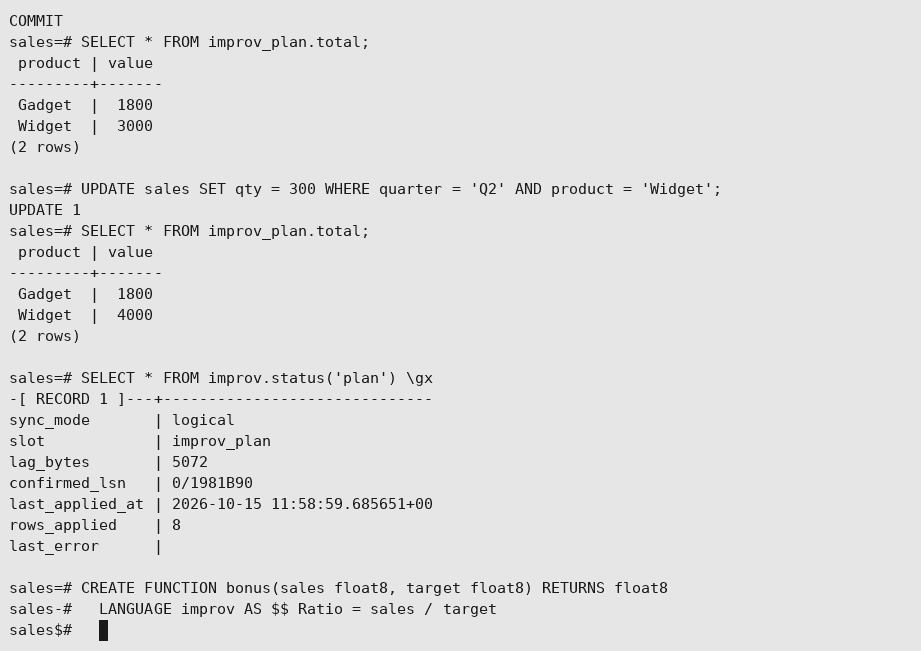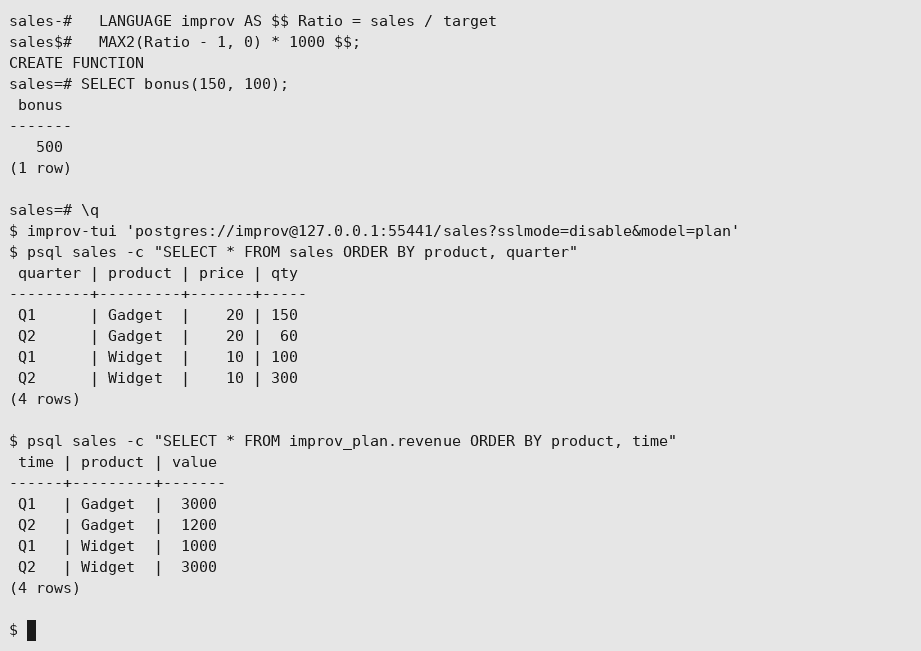
Use it for: data that already lives in Postgres. Bind your table's columns to categories and measures, define formulas, and read results from ordinary tables, with no export step and no second copy.
CREATE EXTENSION pg_improv;
SELECT improv.create_model('plan');
SELECT improv.bind_category('plan', 'Time',    'sales', 'quarter');
SELECT improv.bind_category('plan', 'Product', 'sales', 'product');
SELECT improv.bind_measure ('plan', 'Price',    'sales', 'price');
SELECT improv.bind_measure ('plan', 'Quantity', 'sales', 'qty');
SELECT improv.define('plan', 'Revenue = Price * Quantity');
SELECT * FROM improv_plan.revenue;     -- kept current as sales changes
Choose how results follow your writes:
logical(default): a background worker applies committed changes incrementally, so writers pay nothing. At 100k cells a one-row change is visible about 50 ms after commit.trigger: results update inside the writer's own transaction.improv.recalc(): results update when you call it, in your snapshot.
Open the same model in the GUI or TUI with its postgres://…?model=plan
URL: editing a cell there updates the row in sales.
Improv in Postgres covers setup, value types, aggregated
bindings and durability, and A Family's Finances
is a complete worked example.
In DuckDB (the improv extension)
Use it for: analytics over data DuckDB already reads (tables, Parquet, CSV): a formula as a column, or a model over a table, inside one query. Nothing is stored; each query reads its source and computes.
LOAD improv;
SELECT improv_calc('ROUND(PMT(rate/12, n, -pv), 2)',
                   json_object('rate', rate, 'n', n, 'pv', pv)) FROM loans;
SELECT * FROM improv('sales', '
  category Time = year
  category Product = product
  input Price = price
  input Quantity = qty sum
  Revenue = Price * Quantity
  Share = Revenue / SUM(Revenue OVER Product)');
improv(...) returns one row per computed cell (measure, a column per
category, value, value_text), so the result joins and pivots like any
table. improv_functions() lists the built-in functions.
Improv in DuckDB has the details.
SQL functions (LANGUAGE improv)
Use it for: a calculation you want in plain SQL, written as a formula. No model is needed.
CREATE FUNCTION bonus(sales float8, target float8) RETURNS float8
  LANGUAGE improv IMMUTABLE AS $$
    Ratio = sales / target
    MAX2(Ratio - 1, 0) * 1000
  $$;
SELECT rep, bonus(sales, target) FROM quota;
Arguments are the inputs, by name; each Name = expr line is an
intermediate; the last line is the result. A call costs about 0.14–0.24 µs
(this two-line bonus is the 0.24), about what PL/pgSQL costs.
The HTTP server (improv-server)
Use it for: letting another program read a model, ask what-if questions, or write input cells over HTTP.
With the model m.db from the CLI example, after the
streaming example set Price to 15:
IMPROV_API_TOKEN=secret improv-server m.db 127.0.0.1:3000 &
curl -H 'Authorization: Bearer secret' -X POST localhost:3000/measures/102/eval \
  -H 'content-type: application/json' \
  -d '{"edits":[{"measure":101,"coord":[[1,10],[2,20]],"value":90}]}'
# [{"coord":[["Product","Widget"],["Time","Q1"]],"value":1350.0}]
An edit names its measure and coordinate by id ([[category, item], …]);
the answer comes back by name. /eval computes through the live engine and
writes nothing unless you ask it to ("persist": true). The HTTP Server lists the routes,
tokens and limits.
Choosing quickly
- One person, a model to think with: GUI, or the TUI over SSH.
- A model that is code: a CLI script in git, then open it in the GUI.
- A feed of numbers:
improv stream. - Data in Postgres, results for SQL users:
pg_improv,logicalmode. Usetriggerif a writer must read its own results in the same transaction. - A formula as a SQL function:
LANGUAGE improv. - Data in DuckDB, Parquet or CSV, answers in one query: the DuckDB
extension (
improv_calc,improv(source, model)). - Another service needs answers:
improv-server.
The Improv Model
Improv models a problem as a multidimensional cube rather than a flat grid.
The vocabulary is small and maps directly onto the types in
improv_core_model.
Categories
A category is a dimension of the model — for example Time, Product, or
Region. Each category has a stable numeric id (CategoryId) and a
human-readable name.
Items
An item is one member of a category: 2025 and 2026 are items of Time;
Widget A and Widget B are items of Product. Each item has an id
(ItemId), the id of the category it belongs to, and a name.
Measures
A measure is a named variable indexed by a subset of the categories — its
tensor dimensions. Price might be defined over [Product], while Quantity
and Revenue are defined over [Time, Product].
A measure is one of two kinds:
- Input — raw data you enter.
- Derived — computed from a formula.
Every measure declares a value type: Number, Boolean, Text, DateTime,
or Enum. The engine computes with all of them: dates are written as
#2025-01-31# literals in formulas, come from date/timestamp columns in
Postgres, and display as RFC 3339; an Enum computes as its number. The
GUI edits DateTime cells; the TUI and the CLI's add-measure and set
take number, boolean or text (CSV and SQL imports bring in numbers).
Coordinates
A coordinate names one cell of a measure's tensor by mapping categories to
items — for example {Time=2025, Product=Widget A}. Internally a coordinate is
an ordered map (BTreeMap<CategoryId, ItemId>), so it is
insertion-order-independent: {Time=2025, Product=WidgetA} and
{Product=WidgetA, Time=2025} are the same coordinate. That ordering is what
lets the engine derive a stable dataflow key (see
Architecture).
Input data lives in the model as a map from (measure, coordinate) to a value.
Only input measures have entries; derived measures are computed by the engine.
Structure, logic, and data
The payoff of naming everything is that the three concerns move independently:
- Rename freely. Names are cosmetic; formulas bind to ids, not names, so renaming a category or measure never breaks a formula.
- Add items without touching formulas. Adding
2027toTimeextends every measure defined overTimeautomatically — a formula likeRevenue = Price * Quantityneeds no edit. - Edit logic in one place. A formula is defined once per measure, over dimensions, instead of being copied down a column of cells.
The canonical example
Throughout these docs the running example is a Time × Product revenue model:
Revenue[Time, Product] = Price[Product] * Quantity[Time, Product]
Price is defined over Product only, so it is broadcast over Time:
every year reuses the same per-product price. With
| Product | Price |
|---|---|
| Widget A | 10 |
| Widget B | 20 |
and
| Time | Product | Quantity |
|---|---|---|
| 2025 | Widget A | 100 |
| 2025 | Widget B | 50 |
| 2026 | Widget A | 120 |
| 2026 | Widget B | 80 |
the engine computes:
| Time | Product | Revenue |
|---|---|---|
| 2025 | Widget A | 1000 |
| 2025 | Widget B | 1000 |
| 2026 | Widget A | 1200 |
| 2026 | Widget B | 1600 |
These are the values the engine's test suite checks against.
Getting Started
Build
Improv is a Cargo workspace. From the repository root:
cargo build --workspace
cargo test  --workspace
The improv CLI binary is produced by the improv_cli crate. You can run it
either through Cargo:
cargo run -p improv_cli -- <command> [args]
or directly once built:
./target/debug/improv <command> [args]
The examples below use the built binary.
The CLI
The CLI is a headless front-end over the model store. Every subcommand opens
a store (a single SQLite file, a Postgres model named by a
postgres://…?model= URL, or an in-memory database if you pass ""),
mutates the loaded model, and saves it back.
Run improv help for the full command list. The commands, exactly as accepted
by the binary, are:
| Command | Arguments |
|---|---|
init | <db> |
add-category | <db> <id> <name> |
add-item | <db> <id> <category-id> <name> |
add-measure | <db> <id> <name> <number|boolean|text> input [Category ...] |
add-derived | <db> <id> <name> <formula> |
define | <db> <id> "<Name> = <formula>" or "<Name> = CALL(fn, Arg, ...)" |
set | <db> <measure-id> <value> [--at Cat=Item,Cat=Item ...] |
scenario | <db> <scenario> <measure-id> <value> [--at Cat=Item,...] |
list | <db> |
show | <db> <measure-id> |
eval | <db> <measure-id> [--scenario <name>] |
save-view | <db> <view-id> <name> <measure> [--rows Cat,Cat] [--cols Cat,...] |
export | <db> (JSON) |
stream | <db> <target-measure> ... (edits on stdin, changed cells on stdout) |
import-csv, export-csv | see man improv |
import-sql, refresh-sql, export-sql | see man improv |
register-ext, refresh-ext, refresh-all, serve-refresh | external functions; see man improv |
help | (also --help, -h) |
--version | (also -V) |
Notes:
- Ids (
<id>,<category-id>,<measure-id>) are plain numbers. add-measureadds an input measure; the trailinginputkeyword is required, and any further arguments are category names declaring the measure's dimensions (e.g.... input Time Product). The type (number,boolean,text) declares howsetparses the value.add-derivedadds a formula measure from Improv formula text (e.g."Price * Quantity"or"SUM(Revenue OVER Time)"); its categories are inferred from the measures it references. Compute it witheval.set --atmaps category names to item names. Pairs may be comma-joined (--at Time=2025,Product=WidgetA), space-separated (--at Time=2025 Product=WidgetA), or given as repeated--atflags; they are merged, and a category may appear only once. Omit--atfor a scalar (zero-dimensional) cell.setparses the value according to the measure's declared type: anumbermeasure wants a float, abooleanmeasure wantstrue/false, atextmeasure takes the string verbatim.
Quick start
Build the Time × Product revenue model from the
model chapter, one command at a time:
DB=model.db

improv init          "$DB"
improv add-category  "$DB" 1 Time
improv add-category  "$DB" 2 Product
improv add-item      "$DB" 10 1 2025
improv add-item      "$DB" 11 1 2026
improv add-item      "$DB" 20 2 WidgetA
improv add-item      "$DB" 21 2 WidgetB
improv add-measure   "$DB" 100 Price    number input Product
improv add-measure   "$DB" 101 Quantity number input Time Product
improv set           "$DB" 100 10 --at Product=WidgetA
improv set           "$DB" 100 20 --at Product=WidgetB
improv set           "$DB" 101 100 --at Time=2025,Product=WidgetA
improv set           "$DB" 101 50  --at Time=2025,Product=WidgetB
improv set           "$DB" 101 120 --at Time=2026,Product=WidgetA
improv set           "$DB" 101 80  --at Time=2026,Product=WidgetB
Inspect the model:
improv list "$DB"
categories:
  1 Time
  2 Product
items:
  10 2025 (category 1)
  11 2026 (category 1)
  20 WidgetA (category 2)
  21 WidgetB (category 2)
measures:
  100 Price [input] Number
  101 Quantity [input] Number
views:
inputs:
  100::{Product=WidgetA} = 10
  100::{Product=WidgetB} = 20
  101::{Time=2025,Product=WidgetA} = 100
  101::{Time=2025,Product=WidgetB} = 50
  101::{Time=2026,Product=WidgetA} = 120
  101::{Time=2026,Product=WidgetB} = 80
Save a named view (the GUI opens it from the model browser). --rows and
--cols stack category names; leftover categories become pages:
improv save-view "$DB" 1 "Quantity by year" Quantity --rows Time --cols Product
Look at a single measure and its cells:
improv show "$DB" 100
measure 100 Price [input] Number
  cells:
    100::{Product=WidgetA} = 10
    100::{Product=WidgetB} = 20
Dump the whole model as JSON (useful for scripting or diffing):
improv export "$DB"
Define a derived measure and compute it
Define Revenue from a textual formula, then evaluate it through the engine:
improv add-derived "$DB" 102 Revenue "Price * Quantity"
improv eval        "$DB" 102
eval 102 'Revenue' (4 cells):
  Revenue[Time=2025, Product=WidgetA] = 1000
  Revenue[Time=2025, Product=WidgetB] = 1000
  Revenue[Time=2026, Product=WidgetA] = 1200
  Revenue[Time=2026, Product=WidgetB] = 1600
Derived measures can build on other derived measures. Roll Revenue up over
Time with an aggregation:
improv add-derived "$DB" 103 RevByProduct "SUM(Revenue OVER Time)"
improv eval        "$DB" 103
eval 103 'RevByProduct' (2 cells):
  RevByProduct[Product=WidgetA] = 2200
  RevByProduct[Product=WidgetB] = 2600
Beyond the CLI
Open the same file interactively: improv-tui model.db in a terminal, or
improv-gui model.db on the desktop, where the saved view shows up in the
model browser. Feed it new numbers with improv stream model.db Revenue.
Ways to Use Improv compares the front ends, and man improv
lists every CLI command, including CSV and SQL import and export and
sandboxed Python functions.
Running Improv
This page is the operator's quick reference: build, run each front end, run the tests, check coverage, and the security knobs. The getting-started guide walks through modeling itself.
Build
# Nix (recommended): toolchain + GUI runtime libs + dev tools
nix develop
cargo build --workspace --release

# Or plain Debian/Ubuntu (what the EC2 dev box used):
sudo apt-get install -y build-essential pkg-config libssl-dev libsqlite3-dev \
  libxkbcommon-x11-0 libgl1 libegl1 libgl1-mesa-dri python3 bubblewrap
curl -sSf https://sh.rustup.rs | sh -s -- -y --default-toolchain 1.97.0   # MSRV; any newer stable works
cargo build --workspace --release
The binaries land in target/release/: improv (CLI), improv-tui,
improv-gui and improv-server.
A model to play with
IMPROV=target/release/improv bash docs/demo/sample-model.sh sample.db   # Time × Product × Region
target/release/improv list sample.db
Or build one by hand:
I=target/release/improv
$I init m.db
$I add-category m.db 1 Time;    $I add-item m.db 10 1 Q1; $I add-item m.db 11 1 Q2
$I add-category m.db 2 Product; $I add-item m.db 20 2 Widget
$I add-measure m.db 100 Price number input Time Product
$I add-measure m.db 101 Quantity number input Time Product
$I add-derived m.db 102 Revenue "Price * Quantity"
$I set m.db 100 10 --at Time=Q1 Product=Widget   # or --at Time=Q1,Product=Widget
$I set m.db 101 5  --at Time=Q1 --at Product=Widget
$I eval m.db 102
$I save-view m.db 1 "Revenue by quarter" 102 --rows Time --cols Product
Run each front end
| Front end | Command | Notes |
|---|---|---|
| CLI | improv --help | Scriptable; see man docs/man/improv.1. |
| TUI | improv-tui m.db | Arrows move, e/Enter edit a cell (or a derived measure's formula), Shift+arrows select a range (Sum in the status line), p pivot, [ ] page, f/F filter, Tab measure, R revert to saved, ?/F1 function help, Tab completes names in a formula, q quit (autosaves). |
| GUI | improv-gui m.db | NeXTSTEP-style workspace: application menu top-left, worksheet windows, model browser. Double-click or Enter edits a cell; right-click a tile to move or filter it; type Name = formula on the formula list's last line. Run inside nix develop on NixOS so the GL/X11 libraries are found. |
| Streaming | producer | improv stream m.db Revenue | Edits in on stdin, changed cells out on stdout; saved at end of input. |
| Server | IMPROV_API_TOKEN=secret improv-server m.db | JSON API on 127.0.0.1:3000; see The HTTP Server. |
| Postgres | CREATE EXTENSION pg_improv | Models over your tables; see Improv in Postgres. |
Ways to Use Improv explains when to pick which.
Example server calls:
curl -s -H 'Authorization: Bearer secret' localhost:3000/measures
curl -s -H 'Authorization: Bearer secret' -X POST localhost:3000/measures/102/eval \
  -H 'content-type: application/json' -d '{"edits":[]}'
Open a Postgres-hosted model
Every front end also accepts a Postgres URL naming a model instead of a file:
improv list      'postgres://me:pw@127.0.0.1/sales?model=plan'
improv-tui       'postgres://me:pw@127.0.0.1/sales?model=plan'
improv-gui       'postgres://me:pw@127.0.0.1/sales?model=plan'
improv-server    'postgres://me:pw@127.0.0.1/sales?model=plan'
?model= is required; the other parameters go to libpq as usual. The model
lives in the improv.* catalog (created on first open when the pg_improv
extension isn't installed). Input measures bound to a table
(improv.binding) are read from it, and their edited cells are written back
to that table with UPDATE/INSERT (values only, no DDL). Unbound cells go
to improv.cell. As with a file store, a save fails with "reload and retry"
when another writer changed the model after you loaded it. There is no TLS
in this build, so a non-loopback host needs an explicit sslmode=disable
(use an SSH tunnel to a loopback port instead).
Security defaults (and how to relax them)
Everything stored in a model is treated as untrusted: a shared model can carry code or SQL.
| Behavior | Default | Override |
|---|---|---|
External functions run sandboxed (bubblewrap: read-only /usr, no $HOME, no network, cleared env, rlimits) | always, regardless of the model's pure flag | IMPROV_EXTFN_TRUSTED=1 (host decides, never the model) |
| No bubblewrap installed | refuse to run external functions | IMPROV_EXTFN_ALLOW_UNSANDBOXED=1 (rlimits only) |
| Server's refresh scheduler | off | IMPROV_SCHEDULER=1 plus IMPROV_EXTFN_ALLOW=<file> listing sha256(name\0body) digests |
| Server with no token on a non-loopback address | refuses to start | IMPROV_ALLOW_OPEN=1 |
| Read-only API tokens | none | IMPROV_API_TOKENS_RO=a,b |
| Server limits | 1 MiB body, 30 s request, 64 in flight, 10 s header read, 10k edits per /eval | IMPROV_HEADER_TIMEOUT_MS |
| SQL refresh queries | single SELECT/WITH only, run read-only; DuckDB external access off | none |
| Postgres transport | loopback/socket only (no TLS built in) | sslmode=disable in the connection string to accept cleartext to a remote host |
CSV export of text starting = + - @ \t \r | prefixed with ' (formula-injection safe) | ExportSpec { neutralize_formulas: false } (API) |
| Two processes saving one store | the second save is refused with "reload and retry" (no clobbering) | none |
Tests
cargo test --workspace                          # ~750 tests, ~1 min
cargo test --workspace --release -- --ignored   # stress: 5M cells verified; the 10M case needs ~7 GB
Live Postgres tests run when IMPROV_TEST_PG is set, e.g.
IMPROV_TEST_PG="host=127.0.0.1 user=improv password=improv dbname=improv_test" \
  cargo test -p improv_storage_sql -p improv_storage_pg -p improv_store
The sandbox tests need python3 and bubblewrap; without them they skip
(and say so) rather than fail.
Coverage (≥ 90% functions and branches per crate)
rustup toolchain install nightly -c llvm-tools-preview
cargo install cargo-llvm-cov
scripts/coverage.sh            # prints a per-crate table; exits 1 below 90%
scripts/coverage.sh --html     # also writes target/coverage-html/html/index.html
Inline #[cfg(test)] modules are excluded from the denominator (via the
coverage_nightly cfg cargo-llvm-cov sets), so the percentages measure
library code. CI runs the same gate (coverage job).
Full quality gate
P=$(ls crates | grep -v '^pg_improv$' | sed 's/^/-p improv_/')   # pg_improv has its own workspace
cargo fmt $P -- --check
cargo clippy $P --all-targets --all-features -- -D warnings
cargo test --workspace
cargo deny check
typos
RUSTDOCFLAGS=-Dwarnings cargo doc --workspace --no-deps
scripts/gui-shot-check.sh       # GUI screenshot vs golden (needs Xvfb, ImageMagick, xdotool)
scripts/coverage.sh             # coverage gate (nightly)
(cd crates/pg_improv && cargo fmt --check \
  && cargo clippy --features pg17 --all-targets -- -D warnings \
  && cargo pgrx test pg17 && ./tests/logical.sh)   # the extension
The Formula Language
A formula defines a derived measure in terms of other measures and categories — never in terms of cell addresses. This is what makes logic dimension-aware: you write the rule once, and it applies across every cell of the target measure's tensor.
The formula AST lives in improv_core_model::formula. A Formula wraps an
Expr, which is one of:
Literal(Value)— a constant.Ref(MeasureId, DimensionSpec)— a reference to another measure, with an optional dimension projection.UnaryOp(op, expr)— negation (Neg) or logical not (Not).BinaryOp(op, left, right)— arithmetic (Add,Sub,Mul,Div), logical (And,Or), or comparison (Eq,Ne,Lt,Le,Gt,Ge).Call(FuncId, args)— an aggregation (SUM,AVG,MIN,MAX) or a named scalar function (ABS,ROUND, …).
Writing a formula
You write a formula as text: a target name, =, and an expression.
Revenue = Price * Quantity
The parser (improv_core_model::parser) resolves each name in the expression
against the model, so every measure and category it names must exist. The
target need not exist yet. An unknown name, or anything the grammar does not
allow, is a parse error with a byte position; the parser never panics.
The target may carry a bracketed category list, as in
Revenue[Time, Product] = …. The parser skips that list; it does not set the
measure's categories.
improv add-derived <db> <id> <name> "<expression>" takes only the
expression (the part after =). improv define <db> <id> "<Target> = …"
takes the whole definition.
Operators and precedence
From lowest to highest precedence:
| Level | Operators | Notes |
|---|---|---|
| 1 | OR | left-associative |
| 2 | AND | left-associative |
| 3 | NOT | prefix; applies to a whole comparison |
| 4 | == <> != < <= > >= | at most one per level: a < b < c is an error |
| 5 | & | text join, left-associative |
| 6 | + - | left-associative |
| 7 | * / | left-associative |
| 8 | unary - | prefix |
| 9 | ^ | power, right-associative |
| 10 | % | postfix: x% is x / 100 |
Parentheses group as usual. Keywords (AND, OR, NOT, OVER, TRUE,
FALSE, function names) are case-insensitive.
= is only the assignment after the target. Inside an expression, equality is
==, and <> and != both mean not-equal. So Flag = Price == 10 is a
formula, and X = Price = 10 is an error.
NOT binds looser than a comparison, as in SQL: NOT Price > 15 means
NOT (Price > 15), and NOT a AND b means (NOT a) AND b.
^ follows the mathematical convention: it is right-associative and binds
tighter than unary minus, so 2^3^2 is 2⁹ = 512 and -2^2 is −(2²) = −4.
The spreadsheets read both the other way (64 and 4): write (2^3)^2 and
(-2)^2 for their reading. The exponent may be negative (2^-1 is 0.5).
0^0 is 1, 0^-1 is #DIV/0! and a negative base with a fractional
exponent is #NUM!; POWER(x, y) is the same as x ^ y.
& joins two values as text ("Q" & 3 is Q3; numbers print as they
display, booleans as TRUE/FALSE). 50% is 0.5.
Type rules, checked when the formula compiles:
| Operators | Operands | Result |
|---|---|---|
+ - * / ^ | numbers | number |
& | any two values | text |
AND OR | booleans | boolean |
| comparisons | two values of the same type | boolean |
unary - | number | number |
NOT | boolean | boolean |
Errors
An error is a value, shown as the spreadsheets show it:
| Error | Produced by |
|---|---|
#DIV/0! | division by zero (x / 0, including 0 / 0) |
#NUM! | a numeric domain error (SQRT(-1), LN(0)) or a result too large for a number |
#VALUE! | a value of the wrong kind (VALUE("abc"), CHOOSE out of range) |
#N/A | no value available (NA(), IFS with no true test) |
#NAME?, #REF!, #NULL! | ERROR("#NAME?") etc.; Improv itself does not produce them |
An operator or function given an error returns that error (the left operand,
or the first argument, first). An aggregation over a category containing an
error returns the error (the smallest ERROR.TYPE code if there are
several). ISERROR, ISERR, ISNA and ERROR.TYPE inspect errors, and
IFERROR, IFNA and CLEARERROR replace them.
A missing cell is not an error: where an input has no cell, the result has no cell either (an aggregation skips it).
Typing formulas in your language
The formula bar (GUI) and improv define / add-derived (CLI) read
formulas in the formula locale: IMPROV_LOCALE, else the OS locale
(LANG). In German (de) a formula uses LibreOffice's German function
names, a decimal comma and ; between arguments, and the GUI shows stored
formulas the same way:
| English (stored) | German |
|---|---|
IF(Price > 1.5, ROUND(Price, 2), 0) | WENN(Price > 1,5; RUNDEN(Price; 2); 0) |
SUM(Revenue OVER Time) | SUMME(Revenue OVER Time) |
The English spelling is always accepted as well. Models store formulas in
the English form, so a model opens the same in every locale. Measure and
category names, text in "…" and OVER are never translated. English and
German are the locales so far; another is a table of names
(crates/core_model/src/locale/<tag>.tsv).
Literals
| Literal | Example | Notes |
|---|---|---|
| number | 42, 1.07 | digits and .; no exponent (1e3) and no leading . (.5) |
| text | "hello" | double quotes; no escapes, so the text cannot contain " |
| boolean | TRUE, FALSE | |
| date | #2025-01-01# | midnight UTC |
| date and time | #2025-01-01T09:30:00Z# | RFC 3339 |
A literal may stand alone (X = 42) or appear inside an expression
(Price * 1.07). A literal has no categories, so it broadcasts over the other
operand.
Names
A bare name starts with a letter or _ and continues with letters, digits or
_. Any other name goes in single quotes:
X = 'Unit Price' * 2
X = 'Bob''s Rate' + 1
Inside single quotes, write '' for one ': 'Bob''s Rate' names the
measure Bob's Rate. A quoted name is always a
measure or category name, never a keyword or function, so 'SUM' and
'Over' name measures. '' (empty) and an unclosed quote are errors.
Single quotes are names; double quotes are text.
A qualified name like Matrix.Measure parses, but is always rejected:
Improv has no matrices to qualify a name with. The error names the
qualifier.
Measure references and BY
Measure[Cat, …] sets the reference's by list: keep only the listed
categories. Inside an aggregation the categories it leaves out are collapsed,
so SUM(Quantity[Product] OVER Time) is a per-Product total. Outside one,
the list must name every category of the measure (Quantity[Time, Product]):
Quantity[Product] alone is refused, because nothing would collapse Time
(see Dimension projection below).
Aggregations
Total = SUM(Revenue OVER Time)
The form is AGG(Measure OVER Categories, …). The aggregations include
SUM, AVERAGE (or AVG), MIN, MAX, PRODUCT, SUMSQ, over booleans
AND, OR and XOR, the ordered FIRST, LAST, S and TEXTJOIN, and
the statistics (COUNT, MEDIAN, STDEV, PERCENTILE, COUNTIF,
CORREL, SLOPE, TTEST, …); see the Function Reference.
Total    = SUM(Revenue OVER Time, Region)        -- several categories
Others   = SUM(Revenue OVER ALL EXCEPT Product)  -- all but Product
Big      = SUM(Revenue OVER Time WHERE Revenue > 1000)
Names    = TEXTJOIN(", ", TRUE, Label OVER Product)
Opening  = FIRST(Balance OVER Time)
Spread   = STDEV(Revenue OVER Time)
Top3     = LARGE(Revenue OVER Time, 3)
Fit      = CORREL(Price, Quantity OVER Time)
Big      = COUNTIF(Revenue OVER Time, ">1000")
Sold     = SUMIFS(Revenue, Region OVER Time, "N*", Quantity, ">=10")
Rank     = RANK(Revenue OVER Product)                -- per item: keeps Product
Tier     = RANK.DENSE(Score OVER Person)             -- ties share a rank, no gaps
Buyers   = COUNTUNIQUE(Customer OVER Order)          -- distinct values
- The reduced arguments must be measure references (with an optional
[…]list), not expressions:SUM(Price * 2 OVER Product)is an error; define the expression as a measure first. OVERfollows a reduced argument and applies to all of them. Several categories are separated by commas; a comma followed by anything but a category name starts the next argument (TEXTJOIN("-", TRUE, x OVER T)).OVER ALL EXCEPT Cat, …reduces every category of the measure but those.WHERE conditionkeeps only the cells where the condition is true; the condition may use the measure and any measure over its categories. If no cell passes, the group has no cell.- Rows reach the reduction in item order along the reduced categories,
which is what
FIRST,LASTandTEXTJOINsee. - Other arguments are parameters with one value per group: a literal, or a
measure over the categories the result keeps (
TEXTJOIN(Sep, TRUE, x OVER T)withSepper Product). - The cash-flow functions (
NPV,IRR,MIRR,XNPV,XIRR,FMRR,FVSCHEDULE) read the flows in item order: the first item with a cell is period 0 (NPVdiscounts it one period, as Excel does). An item with no cell is skipped, not a zero flow, so the flows after it move up a period; enter 0 for a period without a flow. - Without
OVER, nothing is reduced (each cell is its own group). - The
…IFand…IFSfunctions take Excel's criteria: a number or boolean means equality, and text may start with=,<>,<,<=,>or>=. Text is compared without regard to case, and=/<>text takes the wildcards*(any run),?(any one character) and~(the next character literally). InSUMIFS(x, c1 OVER T, k1, c2, k2)the summed measure and every criteria measure are reduced together. - Measures reduced together join on the categories they share. Each must
range over the
OVERcategories; any others broadcast and the result keeps them: withroverSrcandMoverSrc × Dst,SUMPRODUCT(r, M OVER Src)is the matrix-vector product, one value perDst. - Per-item reductions (
RANK,RANK.AVG,RANK.DENSE,PERCENTRANK,TREND,GROWTH) give one result per item of their singleOVERcategory, and the result keeps it.RANK.DENSEis SQL'sdense_rank() OVER (ORDER BY x DESC)(order 1:ASC): tied values share a rank and the next value ranks one after them, so 9, 7, 7, 4 rank 1, 2, 2, 3. COUNTUNIQUE(Google Sheets' name) is SQL'scount(DISTINCT x): the number of distinct values among the cells, numbers by value and text case-sensitively. Neither LibreOffice nor Gnumeric has it or a dense rank.- An error among the rows is the result, except that
COUNTskips errors,COUNTAcounts them, the…IFfunctions skip rows whose criteria cell is an error, andAGGREGATE's options 2, 3, 6 and 7 ignore them.
SUM etc. are functions only when ( follows; otherwise the word is an
ordinary measure name.
Positions, neighbours and running totals
Every category has an order: its items' order. Formulas can use it.
Rank     = POSITION(Time)                          -- 1, 2, 3, …
Year     = @ITEM(Time)                             -- the item's name
Growth   = Revenue - PREV(Revenue, Time, 1, 0)     -- change since last year
Ahead    = NEXT(Revenue, Time)                     -- next year's value
Running  = SUM(Revenue OVER Time[FIRST..THIS])     -- running total
Trailing = AVERAGE(Revenue OVER Time[THIS-2..THIS])-- three-period average
ToGo     = SUM(Budget OVER Time[THIS..LAST])
POSITION(T)is the 1-based position of each item ofT;@ITEM(T)its name;@ITEMCOUNT(T)how many itemsThas. They are measures overT, so they broadcast like any other.PREV(x, T, [n = 1], [default])isxat the n-th previous item alongT,NEXTat the n-th next. Before the first item (or where that item has no cell) the result is thedefault, or no cell without one.- A window
OVER T[from..to]gives one result per item: the aggregation over the items fromfromtoto, where each bound isFIRST,LAST,THIS,THIS-norTHIS+n. An empty window is#N/A.
Roles: RELABEL and SWAP
One dimension often plays two roles: Src and Dst are both Person in an
interaction graph. Make each role its own category with the same item
names, and move values between them:
RankBySrc  = RELABEL(Rank[Dst, Iter], Dst, Src)   -- ranges over Src × Iter
Reciprocal = W > 0 AND SWAP(W, Src, Dst) > 0      -- W[a, b] > 0 and W[b, a] > 0
RELABEL(x, From, To)is x with categoryFromreplaced byTo: each cell'sFromitem becomes theToitem with the same name. x must range overFromand not overTo.SWAP(x, A, B)exchanges two categories x ranges over: its value atA = a, B = bis x atA = b, B = a(items matched by name).- Items are matched by name. A cell whose item has no namesake in the other category is dropped (no cell), so a role with extra items loses them: relabel to a category that has them all.
- Both are a map over the cells (a key rewrite), so they stay incremental.
LET and LAMBDA
Margin = LET(rev, Price * Quantity, cost, Unit * Quantity, (rev - cost) / rev)
Double = MAP(Quantity, LAMBDA(q, q * 2))
Square = LAMBDA(x, x * x)(Price - 1)
Running = SCAN(0, Deposits OVER Time, LAMBDA(acc, d, acc * 1.01 + d))
Final   = REDUCE(0, Deposits OVER Time, LAMBDA(acc, d, acc * 1.01 + d))
LET(name, value, …, body)names values for the body (a later value may use an earlier name). A name shadows a measure with the same name.LAMBDA(p, …, body)is a function of its parameters. Call it on the spot (LAMBDA(x, x * x)(Price)) or pass it toMAP,REDUCEorSCAN.MAP(x, …, LAMBDA(p, …, body))applies the body cell by cell.SCAN(init, x OVER T, LAMBDA(acc, v, body))folds alongTin item order: each item's result is the body withaccthe previous item's result (initbefore the first) andvthe item's value.REDUCEkeeps only the last. Both are recurrences underneath, so they update incrementally.
More forms of the same kind:
Grid  = MAKEARRAY(Row, Col, LAMBDA(r, c, r * 10 + c))   -- over Row × Col
Steps = SEQUENCE(Month, 100, 5)                          -- 100, 105, 110, …
Range = BYROW(Sales OVER Product, LAMBDA(row, MAX(row) - MIN(row)))
Total = BYCOL(Sales OVER Month, LAMBDA(col, SUM(col)))
MAKEARRAY(R, C, LAMBDA(r, c, body))evaluates the body over R × C withrandcthe item positions.SEQUENCE(T, [start = 1], [step = 1])is(POSITION(T) - 1) * step + start: a category, not a count, sets its length.BYROW(x OVER C, LAMBDA(row, body))runs the body once per item of x's other categories,rowbeing x's values along C; the body must reduce it (SUM(row),MAX(row) - MIN(row)).BYCOLis the same form: in a dimensional model a row and a column differ only in the category named.
LET, LAMBDA, MAP, MAKEARRAY, SEQUENCE and BYROW expand when the formula is read: the stored formula (and what the formula bar shows) is the expanded expression. A LAMBDA cannot call itself, so every formula still terminates.
Named LAMBDAs (Excel's Name Manager functions) are defined once and called by name:
improv define model.db 1 "Margin = LAMBDA(price, cost, (price - cost) / price)"
improv define model.db 120 "Pct = Margin(Price, Cost) * 100"
A call is stored as a call, not its expansion, so redefining Margin
changes every formula that uses it. A named LAMBDA reads only its
parameters (pass measures as arguments), may call LAMBDAs defined before
it, and never itself. They persist with the model (Mentat and Postgres
stores).
A parameter the body uses where a category goes (OVER c, POSITION(c),
RELABEL's categories) is a category parameter: the call passes a
category name, and a parameter the body reduces (MAX(x OVER c)) takes a
measure:
LOGNORM = LAMBDA(x, c, LN1P(x) / LN1P(MAX(x OVER c)))
An      = LOGNORM(Authored, Person)   -- LN1P(Authored) / LN1P(MAX(Authored OVER Person))
A parameter used both as a value and as a category is an error.
List results: INTO
A function that returns a list says where the list lands: INTO a
category, whose items take the results in order.
Top = SORT(Sales OVER Product, -1 INTO Rank)   -- largest first
Ids = UNIQUE(Customer OVER Order INTO Slot)
The result keeps the measure's other categories and gains Rank: the
k-th value lands at Rank's k-th item. Results beyond Rank's last item are
dropped; if there are fewer, the later items have no cell. INTO must name
a category the measure does not range over.
INTO R, C lays the list over two (or more) categories row by row, the
last varying fastest, as Excel spills a block:
Fit  = LINEST(Sales, Price, Promo OVER Week, TRUE, TRUE INTO StatRow, StatCol)
Grid = SORT(Sales OVER Week INTO Row, Col)
Matrices are a measure over two categories: MDETERM(A OVER R, C).
Matrix results (MINVERSE, MPSEUDOINVERSE, CHOLESKY, EIGEN) come
row by row, so INTO R2, C2 lays them out as a block:
Inv = MINVERSE(A OVER R, C INTO R2, C2).
A matrix product needs no function: operands that share a category join
over it, so with A over R × K and B over K × C,
AB = A * B              -- over R × K × C
P  = SUM(AB OVER K)     -- over R × C: the product
(LINSOLVE is MINVERSE then the same product.) Two measures with no
category in common are still refused, as a likely mistake.
LINEST and LOGEST take any number of x's (every measure before the
options is reduced): the coefficients come last x first, then b, and with
stats Excel's 5 × (k + 1) block. SORTBY(x, by1 OVER T, order1, by2, order2, …) sorts by several keys. SELECTS(values, tests OVER T, condition) keeps the values whose test meets a SUMIF-style criterion.
Lookups
A lookup is a reduction whose key is a parameter: it searches a table along a category and returns the value at the matching item.
Rate  = XLOOKUP(Grade, GradeKey OVER Band, GradeRate, 0)
Slot  = MATCH(Score, Threshold OVER Band)      -- 1-based position along Band
Third = INDEX(Sales OVER Month, 3)
Name  = SELECT(Label, Code OVER Item, Wanted)  -- Quantrix argument order
Names = SELECTLIST(Label, Code OVER Item, Wanted)  -- Wanted over its own category
The key may range over categories the table lacks: with Grade per
Employee and the table per Band, Rate is per Employee, each cell looking
its own grade up in the whole table. Positions (MATCH, XMATCH,
INDEX) are item positions along the category, so an item with no cell
still counts. A table row needs every reduced measure: an item with a key
but no value is not found. The approximate modes do not assume sorted keys;
they pick the nearest key (for MATCH/LOOKUP type 1, the largest ≤ the
key, the last on a tie). XLOOKUP's binary search modes (±2) are the linear
search. Database functions are the aggregations under their spreadsheet
names, with the criteria as WHERE: DSUM(Sales OVER Region WHERE Year == 2025); DGET wants exactly one match.
Recurrences
A measure may read its own earlier values through PREV:
Balance = PREV(Balance, Time, 1, Opening) + Deposits - Withdrawals
Along Time, each period's balance starts from the previous period's
(Opening, a measure per account, before the first). The engine computes it
as a scan in item order, per group of the other categories, and updates it
incrementally: an edit re-runs the chain it is in. Rules:
- every reference to the measure itself is
PREV(itself, T, n, default)along one of its own categories (NEXTcannot refer back); - the rest of the formula is element-wise (no aggregation or other positional function inside it; define those as measures first);
- the measures it reads together range over all of its categories (they supply its cells);
- other cycles between measures are still errors.
Every evaluation still terminates: a scan is as long as the category.
Fixed points: FIXPOINT
A measure can be the fixed point of a step: start from a value and apply
the step until the value stops changing. PageRank over a person-to-person
graph, with Src and Dst two roles of Person, W[Src, Dst] the edge
weights, damping 0.85 and the rank of a person with no out-edge spread
over everyone:
Out      = SUM(W OVER Dst)                -- out-weight per Src
M        = W / Out                        -- transition weights
Dangling = FILL(0 * Out, 1)               -- 1 where Src has no out-edge
PR       = FIXPOINT(SEQUENCE(Src, 1 / @ITEMCOUNT(Src), 0),
             LAMBDA(r, RELABEL((1 - 0.85) / @ITEMCOUNT(Src)
               + 0.85 * (FILL(SUMPRODUCT(r, M OVER Src), 0)
                         + SUMPRODUCT(r, Dangling OVER Src) / @ITEMCOUNT(Src)),
               Dst, Src)),
             100, 0.0000000001)
SUMPRODUCT(r, M OVER Src) is Σ over Src of r·M, one value per Dst, and
RELABEL(…, Dst, Src) reads it back over Src for the next round.
FIXPOINT(init, LAMBDA(r, body), [max_iter = 100], [tolerance = 1e-10])sets r toinit, then r tobodyevaluated at r, until the cells move by at mosttolerancein total (Σ|Δ| over the cells), ormax_iterrounds have run.- Exceeding
max_itergives the last iterate, not an error, and never a hang:max_iteris a whole number from 0 to 10,000 (0 givesinit). The language stays total. max_iterandtoleranceare constant numbers. The parser reads digits and a point only, so write 1e-10 as0.0000000001(or10^-10).- r has
init's type and categories, plus any the body adds: a constantinitwith a body overSrciterates over everySrcitem. Giveinitits categories withSEQUENCE(Src, x, 0)when the body needs r overSrcto begin with (SUMPRODUCT(r, M OVER Src)does). The body must keep r's categories and type. A cell is in the result where it is in both the last iterate and its step; the convergence test treats a cell in only one of them as an infinite change. - A FIXPOINT is a measure's whole formula, and it may not read its own measure (r stands for it). Other measures may read it, and its body may read other FIXPOINT measures.
- The engine solves it round by round. A round evaluates the body's
compiled plan in memory at the iterate: the measures it reads (here
MandDangling) are fixed for the solve, the joins over them are indexed once, and a reduction's rows (which iterate cell meets which edge) are laid out once and refilled each round, as long as the coordinates stay the same. Those measures still update incrementally on the dataflow when an input changes. A body with a node the in-memory evaluator does not take (PREV, a recurrence) runs each round as one dataflow update instead. Both use the same cell operations and give the same cells bit for bit. After an edit it starts from the previous result (if that converged) and agrees with a full recompute; a FIXPOINT whose inputs did not change is not re-solved. A start that fails to converge withinmax_iterrounds restarts frominit, so a result cut off atmax_iteris the same as a fresh evaluation's. - On 1,500 people and 100,000 edges this PageRank matches a plain power iteration to 3e-15 (L1) in 14 rounds, in 0.44 s in a release build (4 ms a round once the rows are laid out; the dataflow over the edges takes 0.25 s), and re-solves after an edge edit in 0.07 s. On 10,000 people and 1,000,000 edges: 13 rounds of 75 ms, 6.9 s in all (3.7 s of it the dataflow), 1.2 s to re-solve after an edit, 3.3 GB at peak.
Functions
Improv has the spreadsheet functions people expect, with Excel's names:
ROUND(Price, 2), MOD(Units, 12), LEFT(Code, 3), SUM(a, b, c).
The Function Reference lists every one, generated from the
code. The argument count and types are checked when the formula is parsed
and compiled: ROUND(Price, 1, 2) is a parse error that shows the
signature, and LEN(Price) (a number where text is wanted) a type error.
Arguments are expressions and broadcast like a binary operator's operands:
ROUND(Revenue / Units, 2) ranges over the union of the arguments'
categories. A literal argument costs nothing extra.
R-style distributions. R.DNAME(x, params…, [give_log]) is the
density or mass at x (or its logarithm); R.PNAME(x, params…, [lower_tail], [log_p]) is P(X ≤ x), or P(X > x) when lower_tail is
FALSE, as a logarithm when log_p is TRUE; R.QNAME(p, …) inverts it,
reading p the same way (a discrete quantile is the smallest k with P(X ≤ k)
≥ p). Parameters out of range are #NUM!. CAUCHY(x, a, TRUE) is the right
tail P(X > x), as in Gnumeric. Improv does not copy Gnumeric's defects:
CUM_BIV_NORM_DIST is exact (Owen's formula), R.DSNORM is right for a
non-zero location, R.PST honours log_p.
Math extras follow Gnumeric, within Improv's limits so every call is
quick: ITHPRIME and NT_PI stop at the 10⁷-th prime, PARTITIONS at n =
4000, the Erlang functions at 10⁶ circuits, other number theory at 2⁵²;
past a limit the answer is #NUM!. HDATE_MONTH numbers Tishri 0 to Elul
11 (12 and 13 for Adar I and II). ROMAN takes Excel's TRUE/FALSE forms;
ARABIC accepts a leading -; ENCODEURL keeps RFC 3986's unreserved
characters.
Complex numbers are text in Excel's form, "3+4i", "-j",
"2.5e-3-i": suffix i or j, no spaces, the same suffix in every
argument of one call. A plain number is a real complex number. Results
print with 15 significant digits, and a real result is still text
(IMSUM("1+i", "1-i") is "2").
Option pricing. The OPT_* functions follow Gnumeric: the first
argument is "c" or "p" ("a"/"e" first for OPT_BINOMIAL,
"cc"/"cp"/"pc"/"pp" for OPT_ON_OPTIONS); OPT_BINOMIAL takes
at most 10,000 steps (Gnumeric 100,000: the tree is quadratic, and that
took seconds). Times are in years;
rates, volatilities and cost of carry are annual fractions (cost of carry
is r for a stock, r − q with a dividend yield, 0 for a future, r − rf for
a currency). OPT_BARRIER, OPT_TOUCH, OPT_PROB_HIT and
OPT_PROB_INMONEY follow LibreOffice, with case-sensitive flags
("c"/"p", "i"/"o" knock in/out, "c"/"e" barrier watched
continuously or at expiry, "f"/"d" pays foreign/domestic) and an
optional Greek ("delta", "gamma", "theta", "vega", "volga",
"vanna", "rho", "rhof"). Where Gnumeric 1.12's bivariate normal is
wrong (some Roll–Geske–Whaley, compound, extendible and two-asset inputs),
Improv returns the correct value.
IF and friends
Bonus = IF(Sales > Target, Sales * 0.1, 0)
Label = IF(Price > 15, "dear", "cheap")
Safe  = IFERROR(Revenue / Units, 0)
IF(test, then, [else]) needs a boolean test and two branches of the same
type. It is lazy: where the test is true only then matters, so a
missing cell or an error in else never shows (and the other way round).
Without else, a false test gives no cell. Where the test is an error, the
result is that error.
The result ranges over the categories of the test and both branches. If the
test has fewer categories than the result (IF(Price > 15, Revenue, 0),
with Price over Product and Revenue over Time×Product), the cells are
those of the test joined with a branch that has the rest (here
Revenue): Improv never invents coordinates. A formula where neither branch
fills in the test's missing categories is a dimension error.
IFS, SWITCH, CHOOSE, IFERROR, IFNA, CLEARERROR and CLEARZERO
are built on IF and behave the same way.
Missing cells: COALESCE and FILL
A formula over a missing cell has no cell, and IF, IFNA and ISNUMBER
cannot change that: they only see the cells their test has. Two functions
give a value where an input has none:
An    = COALESCE(Authored, Vol * 0)   -- Authored, else 0 wherever Vol has a cell
An    = FILL(Authored, 0)             -- Authored, else 0 for every Person
Merit = 0.30 * Vn + 0.25 * FILL(Authored, 0)
Best  = COALESCE(Final, Draft, Estimate, 0)
COALESCE(a, b, …, default)has a cell wherever an argument that ranges over all of the result's categories has one, and takes the first argument with a cell there (the last argument is the default). WithAuthoredset for 2 of 4 people andVolfor all 4,COALESCE(Authored, Vol * 0)has 4 cells.FILL(x, default)has a cell at every item combination of x's categories: x where it has a cell, else the default.- The arguments' categories must nest, and the result ranges over the
largest set. An argument over fewer categories (a literal, or
Volover Person under a Person × Year result) broadcasts onto the cells the others supply but adds none of its own:COALESCE(Mail, Vol)withMailover Person × Year hasMail's cells,FILL(Mail, Vol)every Person × Year.FILL's default may not range beyond x's categories. - The arguments must have one type (an error-only argument,
NA(), takes the others'). An error is a value, soCOALESCEkeeps it:IFERRORreplaces errors. FILL's cells come from the item list, which is fixed for the life of an engine: an edit to an input moves the result incrementally, but a new item takes a rebuild, as any structural change does.
Source forms: CALL and SQL
Two forms are allowed only as the whole right-hand side, and only through
parse_definition (the improv define command):
Score = CALL(myfn, Price, Quantity)
Sales = SQL("SELECT product, amount FROM sales")
CALL(fn, m1, m2, …)makes an external-function measure:fnis a registered external function, followed by zero or more argument measure names (bare or quoted). The function runs outside the dataflow and its results become input cells.SQL("query")takes one double-quoted query string. It describes a SQL-sourced input measure; the caller maps the result columns to dimensions.
Neither may appear inside a larger expression.
Not in the grammar
| Written | Result |
|---|---|
M.Price | error: unknown qualifier: M |
Quantity EXCEPT Time | error: no EXCEPT syntax |
Broadcasting: the Revenue example
The canonical formula is:
Revenue[Time, Product] = Price[Product] * Quantity[Time, Product]
Price ranges over Product only; Quantity ranges over Time and
Product. Their dimensions differ, so the compiler must align them before it
can multiply element-wise. One dimension is a subset of the other
({Product} ⊆ {Time, Product}), so Price is broadcast over Time: the
result is defined over the union, [Time, Product], and each Time reuses the
matching product's price.
The rule is strict: for a binary op, one operand's dimension must be a subset of
the other's. If neither is (say, Product-only added to Region-only), the
compiler rejects it with a dimension mismatch rather than guessing.
Dimension projection: BY / OVER / EXCEPT
A measure reference carries a DimensionSpec with three category lists that
reshape which dimensions the reference exposes:
| Field | Meaning |
|---|---|
by | Categories to keep (group by). If non-empty, only these survive. |
over | Categories to aggregate over (collapse). Used with an aggregation call. |
except | Categories to drop. |
Starting from the measure's base categories, the compiler keeps a category if it
passes by (or by is empty), is not in except, and is not in over. The
over set specifically marks the dimensions an enclosing aggregation collapses.
In the text syntax, Measure[Cat, …] fills by and AGG(Measure OVER Cat)
fills over. Nothing fills except.
Only an aggregation collapses categories. So a bare reference whose by
leaves a category out is a compile error: X = Quantity[Product], with
Quantity over [Time, Product], says "Quantity[…] leaves out category
Time, which only an aggregation can collapse". Inside an aggregation, the
result keeps the categories that by keeps and over does not name.
Aggregation
Aggregation is expressed as a Call whose single argument is a measure
reference. The reference's over list names the categories to collapse; the
result is defined over the remaining categories.
Every function has a fixed FuncId, stored in saved formulas and never
reused (crates/core_model/src/functions.rs). The aggregations:
| Function | FuncId |
|---|---|
SUM | 1 |
AVERAGE (AVG) | 2 |
MIN | 3 |
MAX | 4 |
PRODUCT | 5 |
SUMSQ | 6 |
AND, OR, XOR | 7, 8, 9 |
For example, SUM(Revenue OVER Time) takes Revenue[Time, Product] and
collapses Time, producing a per-product total Revenue[Product]. In the
compiler this becomes an Aggregate plan node grouped by the surviving
categories (Product), with func = FuncId(1).
AVERAGE divides the sum by the count of contributing cells; MIN and MAX
take the extremum. An aggregation's argument must be numeric, except AND,
OR and XOR, which take booleans.
Type and dimension checking
Compiling a formula (improv_engine::compiler::compile_formula) runs two
passes:
infer— walks the AST, resolving each measure reference against the model's metadata and computing every subexpression's value type and dimension. It rejects type errors (e.g. multiplying non-numbers,Noton a number) and structural errors (dimensions that cannot be broadcast).build_plan— lowers the typed tree to aPlanNodegraph, inserting aJoinwhere operand dimensions differ (to broadcast) and anAggregatenode for each aggregation call.
The result is an operator plan that maps directly onto differential-dataflow operators — see Architecture.
Scope today
The engine evaluates input-measure references, literals (standalone or as
operands), unary negation and NOT, the arithmetic, logical and comparison
operators, dimension-aligning joins, aggregations (several measures,
parameters, WHERE, windows, per-item results such as RANK, lookups,
list results with INTO), LET and LAMBDA, the 681
built-in functions of the Function Reference (math,
rounding, text, dates, statistics and distributions, financial, engineering), the lazy
IF family, positions and neighbours (POSITION, PREV, NEXT),
recurrences, bounded fixed points (FIXPOINT), typed error values, non-numeric (Text, Boolean, DateTime)
values, and derived measures that reference other derived measures.
External functions use the CALL(...) definition form and are evaluated
host-side by improv_extfn. Python, R, Julia and Pure run in a sandboxed
subprocess; Wasm runs in-process. SQL-sourced measures use SQL("...").
Gaps:
- no
EXCEPTon a plain reference (onlyOVER ALL EXCEPT …inside an aggregation); - a window or per-item reduction takes one
OVERcategory; TEXTSPLITtakes no row delimiter;LINESTwith several x's refuses collinear x's (#NUM!) rather than dropping them as Excel does;- named LAMBDAs are defined with
improv define(no GUI editor yet); - no
MMULTorLINSOLVEfunction: a matrix product is a join and a sum (see Matrices);FORECAST.ETS.CONFINTis #N/A for seasonal models (LibreOffice's interval is a random simulation); NETWORKDAYSandWORKDAYtake no holiday list yet.
Function Reference
Every built-in function, by category. Names are case-insensitive;
[x] is optional ([x=1]: 1 if omitted), … repeats the
arguments before it, x OVER T is reduced over a category and
INTO K lays a list result along one. Positions are
1-based. An error argument (#DIV/0!, #N/A, …) makes the result
that error, except in the functions that test for errors. See
The Formula Language for operators, types and
dimensions.
Aggregations
Written F(Measure OVER Category): collapse one category. Each also has a scalar form over its arguments, listed under its category.
| Function | Returns | Description |
|---|---|---|
SUM(values OVER T) | number | the sum over a category (also DSUM) |
AVERAGE(values OVER T) | number | the mean over a category (also AVG, DAVERAGE) |
MIN(values OVER T) | number | the smallest value over a category (also DMIN) |
MAX(values OVER T) | number | the largest value over a category (also DMAX) |
PRODUCT(values OVER T) | number | the product over a category (also DPRODUCT) |
SUMSQ(values OVER T) | number | the sum of squares over a category |
AND(values OVER T) | boolean | whether every value over a category is true |
OR(values OVER T) | boolean | whether any value over a category is true |
XOR(values OVER T) | boolean | whether an odd number of values over a category are true |
FIRST(values OVER T) | the branches' type | the value at the first item (in category order) that has one |
LAST(values OVER T) | the branches' type | the value at the last item that has one |
S(values OVER T) | text | the first value, as text (Quantrix) |
TEXTJOIN(delimiter, ignore_empty, values OVER T) | text | the values in item order joined by the delimiter (skipping empty text when ignore_empty is TRUE) |
Logical
IF and the functions built on it evaluate only the branch they choose, so an error or missing cell in the other branch does not matter.
| Function | Returns | Description |
|---|---|---|
AND(logical1, …) | boolean | whether every argument is true |
OR(logical1, …) | boolean | whether any argument is true |
XOR(logical1, …) | boolean | whether an odd number of arguments are true |
IF(logical_test, value_if_true, [value_if_false]) | the branches' type | then where the test is true, else (or no cell) where it is false |
IFS(logical_test1, value_if_true1, …) | the branches' type | the value paired with the first true test |
SWITCH(expression, value1, result1, …, [default]) | the branches' type | the result paired with the first value equal to the expression, else the default |
CHOOSE(index_num, value1, …) | the branches' type | the index_num-th value (1-based) |
IFERROR(value, value_if_error) | the branches' type | the value, or the alternative where it is an error |
IFNA(value, value_if_na) | the branches' type | the value, or the alternative where it is #N/A |
CLEARERROR(value, [alternative]) | the branches' type | the value, or the alternative (or no cell) where it is an error |
CLEARZERO(value, [alternative]) | number | the value, or the alternative (or no cell) where it is zero |
COALESCE(value1, …, default) | the branches' type | a cell wherever any argument that reads a measure has one: the first argument with a cell, else the last (the default) |
BETWEEN(x, low, high, [inclusive]) | boolean | whether low ≤ x ≤ high (strict when inclusive is FALSE) |
TRUE() | boolean | TRUE |
FALSE() | boolean | FALSE |
SCAN(initial_value, array OVER T, lambda) | the branches' type | SCAN(initial_value, array OVER T, LAMBDA(acc, v, body)): the running fold along T, one value per item |
REDUCE(initial_value, array OVER T, lambda) | the branches' type | REDUCE(initial_value, array OVER T, LAMBDA(acc, v, body)): the fold's last value |
LET(name, value, …, body) | the branches' type | LET(name, value, …, body): the body with each name bound to its value |
LAMBDA(p, …, body) | the branches' type | LAMBDA(p, …, body): a function of its parameters, called on the spot or passed to MAP, REDUCE or SCAN |
MAKEARRAY(rows, cols, lambda) | the branches' type | MAKEARRAY(rows, cols, LAMBDA(r, c, body)): the body over the categories rows × cols, with r and c the item positions |
BYROW(array OVER C, lambda) | the branches' type | BYROW(array OVER C, LAMBDA(row, body)): the body per item of array's other categories, row being the values along C (the body reduces it: SUM(row), …) (also BYCOL) |
MAP(array1, …, lambda) | the branches' type | MAP(array1, …, LAMBDA(p, …, body)): the body applied element by element |
Information and errors
| Function | Returns | Description |
|---|---|---|
ISERROR(value) | boolean | whether the value is any error |
ISERR(value) | boolean | whether the value is an error other than #N/A |
ISNA(value) | boolean | whether the value is #N/A |
NA() | number | the #N/A error |
ERROR(name) | number | the error a code names ("#DIV/0!") |
ERROR.TYPE(error_val) | number | 1 #NULL!, 2 #DIV/0!, 3 #VALUE!, 4 #REF!, 5 #NAME?, 6 #NUM!, 7 #N/A; #N/A for a non-error |
ISBLANK(value) | boolean | whether the value is blank: always FALSE for a value, since a missing cell has none (ISBLANK("") is FALSE) (also ISEMPTY) |
ISNUMBER(value) | boolean | whether the value is a number; a date is one, as in Excel |
ISTEXT(value) | boolean | whether the value is text |
ISNONTEXT(value) | boolean | whether the value is not text (TRUE for an error) |
ISLOGICAL(value) | boolean | whether the value is a boolean |
ISDATE(value) | boolean | whether the value is a date |
ISNUMBERORDATE(value) | boolean | whether the value is a number or a date |
ISEVEN(number) | boolean | whether the integer part is even (also ISEVEN_ADD) |
ISODD(number) | boolean | whether the integer part is odd (also ISODD_ADD) |
N(value) | number | the value as a number: a date's serial number, TRUE 1, FALSE and text 0 |
T(value) | text | the value if it is text, else "" |
TYPE(value) | number | 1 number (or date), 2 text, 4 boolean, 16 error |
Math and trigonometry
Angles are in radians.
| Function | Returns | Description |
|---|---|---|
SUM(number1, …) | number | the sum of the arguments |
AVERAGE(number1, …) | number | the mean of the arguments |
MIN(number1, …) | number | the smallest argument (also MIN2) |
MAX(number1, …) | number | the largest argument (also MAX2) |
PRODUCT(number1, …) | number | the product of the arguments |
SUMSQ(number1, …) | number | the sum of the squares of the arguments |
ABS(number) | number | absolute value |
NEG(number) | number | negation |
SIGN(number) | number | −1, 0 or 1 |
SQRT(number) | number | square root (#NUM! below zero) |
SQRTPI(number) | number | √(x·π) |
EXP(number) | number | e to the power x |
EXPM1(x) | number | eˣ − 1, accurate near 0 |
LN(number) | number | natural logarithm |
LN1P(x) | number | ln(1 + x), accurate near 0 |
LOG(number, [base=10]) | number | logarithm to a base (default 10) |
LOG10(number) | number | base-10 logarithm |
LOG2(x) | number | base-2 logarithm |
POWER(number, power) | number | number raised to power (same as ^) |
MOD(number, divisor) | number | remainder, with the divisor's sign |
QUOTIENT(numerator, denominator) | number | integer part of a quotient |
PI() | number | π |
DEGREES(angle) | number | radians to degrees |
RADIANS(angle) | number | degrees to radians |
SIN(number) | number | sine (radians) |
COS(number) | number | cosine |
TAN(number) | number | tangent |
ASIN(number) | number | arcsine |
ACOS(number) | number | arccosine |
ATAN(number) | number | arctangent |
ATAN2(x_num, y_num) | number | angle of the point (x, y) |
SINH(number) | number | hyperbolic sine |
COSH(number) | number | hyperbolic cosine |
TANH(number) | number | hyperbolic tangent |
ASINH(number) | number | inverse hyperbolic sine |
ACOSH(number) | number | inverse hyperbolic cosine |
ATANH(number) | number | inverse hyperbolic tangent |
SEC(number) | number | secant |
CSC(number) | number | cosecant |
COT(number) | number | cotangent |
SECH(number) | number | hyperbolic secant |
CSCH(number) | number | hyperbolic cosecant |
COTH(number) | number | hyperbolic cotangent |
ACOT(number) | number | inverse cotangent |
ACOTH(number) | number | inverse hyperbolic cotangent |
SINPI(x) | number | sin(πx), exact at integers |
COSPI(x) | number | cos(πx), exact at integers |
TANPI(x) | number | tan(πx), exact at integers |
COTPI(x) | number | cot(πx), exact at integers |
HYPOT(number1, …) | number | √(Σ xᵢ²) without overflow |
FACT(number) | number | factorial |
FACTDOUBLE(number) | number | double factorial n!! |
COMBIN(number, number_chosen) | number | combinations of number items taken number_chosen at a time |
COMBINA(number, number_chosen) | number | combinations with repetition |
PERMUT(number, number_chosen) | number | permutations of number items taken number_chosen at a time |
PERMUTATIONA(number, number_chosen) | number | permutations with repetition |
GCD(number1, …) | number | greatest common divisor |
LCM(number1, …) | number | least common multiple |
MULTINOMIAL(number1, …) | number | (Σ n)! / Π n! |
RAWSUBTRACT(number1, …) | number | the first argument minus the rest |
INVSUMINV(number1, …) | number | 1 / Σ(1/xᵢ) |
GAMMA(number) | number | the gamma function Γ(x) |
GAMMALN(x) | number | ln Γ(x), for x > 0 (also GAMMALN.PRECISE) |
BETA(x, y) | number | the Euler beta function B(a, b) |
BETALN(x, y) | number | ln |
DIGAMMA(x) | number | the digamma function ψ(x) |
IGAMMA(a, x, [lower=TRUE], [regularize=TRUE], [real=TRUE]) | number | the incomplete gamma function of a and x: lower (default) or upper, regularized (default) or not; the imaginary part (real = FALSE) is 0 |
POCHHAMMER(x, n) | number | the rising factorial Γ(x + n) / Γ(x) |
ERF(lower_limit, [upper_limit]) | number | the error function erf(x), or erf(upper) − erf(lower) |
ERF.PRECISE(x) | number | the error function erf(x) |
ERFC(x) | number | the complementary error function 1 − erf(x) (also ERFC.PRECISE) |
SUMA(values OVER T) | number | the sum, counting TRUE as 1 and text as 0 |
SUMPRODUCT(array1, … OVER T) | number | Σ xᵢ·yᵢ·… over the rows where every measure has a cell |
SUMX2MY2(array_x, array_y OVER T) | number | Σ(x² − y²) |
SUMX2PY2(array_x, array_y OVER T) | number | Σ(x² + y²) |
SUMXMY2(array_x, array_y OVER T) | number | Σ(x − y)² |
SERIESSUM(x, n, m, coefficients OVER T) | number | Σ cᵢ·x^(n + i·m), the coefficients c in item order (i from 0) |
POLYNOMIAL(x, coefficients OVER T) | number | Σ cᵢ·xⁱ, the coefficients c in item order (the constant c₀ first) |
PERCENTOF(data_subset, data_all OVER T) | number | Σ subset / Σ all |
LAMBERTW(x, [k=0]) | number | the Lambert W function: the w with w·eʷ = x, on branch k 0 (the default, x ≥ −1/e) or −1 (−1/e ≤ x < 0) |
AGM(a, b) | number | the arithmetic-geometric mean of a, b ≥ 0 |
GD(x) | number | the Gudermannian function: 2·atan(tanh(x/2)) |
ILOG(x, [base=10]) | number | the integer logarithm: the largest k with baseᵏ ≤ x, for x > 0 and an integer base ≥ 2 (default 10) |
REDUCEPI(x, e, [q]) | number | x reduced modulo π/2ᵉ as if π were exact: the xr with x = xr + j·π/2ᵉ and |
FIB(n) | number | the n-th Fibonacci number, n ≥ 1 (truncated); #NUM! past n = 1476, where it overflows |
ISPRIME(n) | boolean | whether n is prime (FALSE below 2) |
ITHPRIME(i) | number | the i-th prime, i from 1 to 10⁷ (Gnumeric: 10⁸) |
PFACTOR(n) | number | the smallest prime factor of n ≥ 2 (#VALUE! below 2) |
NT_D(n) | number | the number of divisors of n ≥ 1 |
NT_SIGMA(n) | number | the sum of the divisors of n ≥ 1 |
NT_PHI(n) | number | Euler's totient: how many of 1…n are coprime to n ≥ 1 |
NT_MU(n) | number | the Möbius function of n ≥ 1: 0 if a square divides n, else (−1)^(number of prime factors) |
NT_OMEGA(n) | number | the number of distinct prime factors of n ≥ 1 |
NT_PI(n) | number | how many primes are ≤ n (0 below 2; n up to 179 424 673, the 10⁷-th prime) |
NT_RADICAL(n) | number | the product of the distinct prime factors of n ≥ 1 |
PARTITIONS(n) | number | the number of ways to write n ≥ 0 as a sum of positive integers (n up to 4000) |
FLT.MAX() | number | the largest finite double, 1.7976931348623157e308 |
FLT.MIN() | number | the smallest positive normal double, 2.2250738585072014e-308 |
FLT.RADIX() | number | the floating-point base, 2 |
FLT.NEXTAFTER(x, y) | number | the next double after x toward y ("+" or "-" for the infinities); y itself if y = x |
MDETERM(A OVER R, C) | number | MDETERM(A OVER R, C): the determinant of the square matrix A (rows along R, columns along C); 0 if singular |
LOGMDETERM(A OVER R, C) | number | LOGMDETERM(A OVER R, C): ln |
MINVERSE(A OVER R, C INTO R2, C2) | number | MINVERSE(A OVER R, C INTO R2, C2): the inverse of the square matrix A, row by row; #NUM! if singular |
MPSEUDOINVERSE(A OVER R, C, [threshold] INTO C2, R2) | number | MPSEUDOINVERSE(A OVER R, C, [threshold] INTO C2, R2): the Moore–Penrose pseudo-inverse (C × R, row by row); singular values up to threshold (default 256 ε) times the largest count as zero |
CHOLESKY(A OVER R, C INTO R2, C2) | number | CHOLESKY(A OVER R, C INTO R2, C2): the lower-triangular L with L·Lᵀ = A for a symmetric positive-definite A (asymmetric pairs averaged), row by row; #NUM! where A is not positive definite |
EIGEN(A OVER R, C INTO R2, C2) | number | EIGEN(A OVER R, C INTO R2, C2): for a symmetric A (asymmetric pairs averaged), its eigenvalues largest magnitude first, then the matrix of their unit eigenvectors as columns: (n + 1) × n values, row by row |
FOURIER(y OVER T, [inverse] INTO K) | text | FOURIER(y OVER T, [inverse] INTO K): Gnumeric's discrete Fourier transform (scaled by 1/n, zero-padded to a power of two), each value as complex text "a+bi" |
Rounding
Rounding is decimal: ROUND(2.675, 2) is 2.68.
| Function | Returns | Description |
|---|---|---|
ROUND(number, [num_digits=0]) | number | to num_digits decimal places, halves away from zero |
ROUNDUP(number, [num_digits=0]) | number | away from zero to num_digits places |
ROUNDDOWN(number, [num_digits=0]) | number | toward zero to num_digits places |
ROUNDSIG(value, digits) | number | to digits significant digits |
TRUNC(number, [num_digits=0]) | number | truncate to num_digits places |
INT(number) | number | down to an integer |
FLOOR(number, [significance=1]) | number | down to a multiple of significance (default 1) |
CEIL(x) | number | up to an integer |
CEILING(number, [significance=1]) | number | up to a multiple of significance (default 1) |
FLOOR.MATH(number, [significance=1], [mode=0]) | number | down to a multiple; mode ≠ 0 rounds negatives toward zero |
CEILING.MATH(number, [significance=1], [mode=0]) | number | up to a multiple; mode ≠ 0 rounds negatives away from zero |
FLOOR.PRECISE(number, [significance=1]) | number | down to a multiple, ignoring the multiple's sign |
CEILING.PRECISE(number, [significance=1]) | number | up to a multiple, ignoring the multiple's sign |
ISO.CEILING(number, [significance=1]) | number | same as CEILING.PRECISE |
MROUND(number, multiple) | number | to the nearest multiple |
EVEN(number) | number | away from zero to an even integer |
ODD(number) | number | away from zero to an odd integer |
Text
Lengths and positions count characters, not bytes.
| Function | Returns | Description |
|---|---|---|
CHAR(number) | text | the character with code n (1–255) |
UNICHAR(number) | text | the Unicode character n |
CODE(text) | number | the code of the first character |
UNICODE(text) | number | the code point of the first character |
CLEAN(text) | text | remove non-printing characters |
CONCAT(text1, …) | text | join values as text (same as &) |
CONCATENATE(text1, …) | text | join values as text |
EXACT(text1, text2) | boolean | case-sensitive equality |
FIND(find_text, within_text, [start_num=1]) | number | 1-based position of find_text in within_text, case-sensitive |
SEARCH(find_text, within_text, [start_num=1]) | number | 1-based position, case-insensitive, with * and ? wildcards |
LEFT(text, [num_chars=1]) | text | the first num_chars characters (default 1) |
RIGHT(text, [num_chars=1]) | text | the last num_chars characters (default 1) |
MID(text, start_num, num_chars) | text | num_chars characters from a 1-based start_num |
LEN(text) | number | the number of characters |
LOWER(text) | text | lowercase |
UPPER(text) | text | uppercase |
PROPER(text) | text | capitalize each word |
REPLACE(old_text, start_num, num_chars, new_text) | text | replace num_chars characters from a 1-based start_num |
REPT(text, number_times) | text | repeat text number_times times |
SUBSTITUTE(text, old_text, new_text, [instance_num]) | text | replace every (or the instance_num-th) occurrence of old_text |
TRIM(text) | text | remove leading, trailing and repeated spaces |
VALUE(text) | number | text as a number |
TEXTBEFORE(text, delimiter, [instance_num=1], [match_mode=0], [match_end=0], [if_not_found]) | text | text before the instance_num-th delimiter |
TEXTAFTER(text, delimiter, [instance_num=1], [match_mode=0], [match_end=0], [if_not_found]) | text | text after the instance_num-th delimiter |
TEXTBETWEEN(text, start_delimiter, end_delimiter) | text | text between the first start delimiter and the next end delimiter |
COUNTMATCHES(text, search) | number | how many times search occurs in text |
TEXT(value, format_text) | text | format with an Excel number-format code: 0 # ? . , % E+ E- "text" \c _c *c, General, ; sections (positive;negative;zero;text with @), colors; dates y m d h s AM/PM A/P. Unsupported (#VALUE!): conditions, locales, [h] elapsed time, fractional seconds, fractions, eras |
FIXED(number, [decimals=2], [no_commas=FALSE]) | text | rounded to decimals places (default 2) as text, with thousands commas unless no_commas |
DOLLAR(number, [decimals=2]) | text | as en-US currency text: $1,234.57, negatives in parentheses, decimals default 2 |
NUMBERVALUE(text, [decimal_separator="."], [group_separator=","]) | number | text as a number with explicit decimal (default .) and group (default ,) separators |
VALUETOTEXT(value, [format=0]) | text | a value as text; format 1 quotes text |
REGEX(text, expression, [replacement], [flags]) | text | the first match (#N/A if none), or with a replacement the text with the first match replaced; the fourth argument is "g" (replace all) or the occurrence to replace. Patterns use the Rust regex syntax, not ICU's |
REGEXTEST(text, pattern, [case_sensitivity=0]) | boolean | whether the pattern matches; case_sensitivity 1 ignores case. Rust regex syntax |
REGEXEXTRACT(text, pattern, [return_mode=0], [case_sensitivity=0]) | text | the first match (#N/A if none); only return mode 0, modes 1 and 2 (arrays) are #VALUE!. Rust regex syntax (also REGEX.EXTRACT) |
REGEXREPLACE(text, pattern, replacement, [occurrence=0], [case_sensitivity=0]) | text | replace every match (or the occurrence-th, negative from the end) with $n-style replacement text. Rust regex syntax |
TEXTSPLIT(text OVER T, col_delimiter, [row_delimiter], [ignore_empty=FALSE] INTO K) | text | the parts of the text between col_delimiter matches (case-sensitive), in order; written without OVER, each cell splits on its own: TEXTSPLIT(Text, "," INTO Part). row_delimiter must be "" (splitting into rows is not supported yet); ignore_empty drops empty parts; empty text is #VALUE! |
ARRAYTOTEXT(array OVER T, [format=0]) | text | the values as text in item order: format 0 "1, 2, a", format 1 {1,2,"a"} |
ASC(text) | text | full-width ASCII and katakana as half-width, as LibreOffice's ASC (a voiced kana becomes its letter and a sound mark) |
JIS(text) | text | half-width ASCII and katakana as full-width, as LibreOffice's JIS (a letter and its sound mark join) (also DBCS) |
BAHTTEXT(number) | text | a number as Thai baht and satang in words, rounded to the satang |
ROT13(text) | text | ASCII letters rotated 13 places; anything else unchanged |
ENCODEURL(text) | text | UTF-8 percent-encoding of every byte but A–Z a–z 0–9 - _ . ~ (#VALUE! for empty text) |
ROMAN(number, [form=0]) | text | 0–3999 in Roman numerals; form 0 classic (or TRUE) to 4 most concise (or FALSE) |
ARABIC(text) | number | Roman numerals (0–3999) as a number; case and surrounding spaces ignored, a leading - negates, "" is 0 |
Date and time
Dates are date-time values (UTC, millisecond precision). A number given where a date is wanted is a spreadsheet serial date (1 = 1900-01-01).
| Function | Returns | Description |
|---|---|---|
DATE(year, month, day) | date | a date; out-of-range months and days roll over, years 0–1899 add 1900 |
DATEVALUE(date_text) | date | parse a date: 2025-01-31, 2025-01-31T09:30:00Z (the time is dropped) or 1/31/2025 |
TIME(hour, minute, second) | date | a time of day on serial day 0 (1899-12-30), wrapping at 24 hours |
TIMEVALUE(time_text) | number | parse a time (09:30, 9:30 PM, 2025-01-31T09:30:00Z) as a fraction of a day |
YEAR(serial_number) | number | the year |
MONTH(serial_number) | number | the month, 1–12 |
DAY(serial_number) | number | the day of the month |
HOUR(serial_number) | number | the hour, 0–23 |
MINUTE(serial_number) | number | the minute |
SECOND(serial_number) | number | the second, rounded |
WEEKDAY(serial_number, [return_type=1]) | number | day of the week: type 1 Sunday=1 (default), 2 Monday=1, 3 Monday=0, 11–17 day 1 is Monday…Sunday |
WEEKNUM(serial_number, [return_type=1]) | number | week of the year (the week of January 1 is 1), weeks starting on type's day as in WEEKDAY (1, 2, 11–17); type 21 is the ISO week (also WEEKNUM_EXCEL2003) |
ISOWEEKNUM(date) | number | the ISO 8601 week number |
ISOYEAR(date) | number | the ISO 8601 week-numbering year |
DAYOFYEAR(date) | number | the day of the year, 1–366 |
DAYNAME(date) | text | the English weekday name of a date, or of a day number 1–7 (1 is Sunday) |
MONTHNAME(month) | text | the English name of month 1–12 |
DAYS(end_date, start_date) | number | days from start to end (end − start, times included) |
DAYS360(start_date, end_date, [method=FALSE]) | number | days between on a 360-day year, US (NASD) method or European when TRUE |
DATEDIF(start_date, end_date, unit) | number | complete "Y" years, "M" months or "D" days between; "YM", "YD", "MD" ignore the larger units |
EDATE(start_date, months) | date | the same day n months later (clamped to the month's end) |
EOMONTH(start_date, months) | date | the last day of the month n months later |
YEARFRAC(start_date, end_date, [basis=0]) | number | the fraction of a year between: basis 0 US 30/360 (default), 1 actual/actual, 2 actual/360, 3 actual/365, 4 European 30/360 |
NETWORKDAYS(start_date, end_date) | number | working days (Monday–Friday) from start to end inclusive; no holidays argument yet (it needs an aggregation) (also NETWORKDAYS_EXCEL2003) |
NETWORKDAYS.INTL(start_date, end_date, [weekend=1]) | number | working days with a weekend of 1–7 (two days), 11–17 (one day) or a "0000011" Monday-first mask; no holidays argument yet |
WORKDAY(start_date, days) | date | the date n working days (Monday–Friday) after start; no holidays argument yet |
WORKDAY.INTL(start_date, days, [weekend=1]) | date | WORKDAY with a weekend as in NETWORKDAYS.INTL; no holidays argument yet |
NOW() | date | the current date and time (UTC); re-evaluated when the model is recalculated |
TODAY() | date | the current date (UTC midnight); re-evaluated when the model is recalculated |
DAYSINMONTH(date) | number | the number of days in the date's month |
DAYSINYEAR(date) | number | the number of days in the date's year |
WEEKSINYEAR(date) | number | the number of ISO weeks (52 or 53) in the date's year |
ISLEAPYEAR(date) | boolean | whether the date's year is a leap year |
MONTHS(start_date, end_date, type) | number | months between: type 0 complete months, 1 calendar months |
WEEKS(start_date, end_date, type) | number | weeks between: type 0 complete weeks, 1 calendar (Monday) weeks |
YEARS(start_date, end_date, type) | number | years between: type 0 complete years, 1 calendar years |
UNIX2DATE(t) | date | the date of a Unix time in seconds |
DATE2UNIX(d) | number | a date as Unix time in seconds |
DUR2DAYS(duration) | number | a duration (a number of days) in days |
DUR2HOURS(duration) | number | a duration in days as hours |
DUR2MINUTES(duration) | number | a duration in days as minutes |
DUR2SECONDS(duration) | number | a duration in days as seconds |
DUR2MILLISECONDS(duration) | number | a duration in days as milliseconds |
DUR2WEEKS(duration) | number | a duration in days as weeks |
STRIPDURATION(duration) | number | the value (durations are already a number of days) |
EASTERSUNDAY(year) | date | Easter Sunday (Gregorian) of a year 1583–9956; 0–29 mean 2000–2029, 30–99 mean 1930–1999 |
ASCENSIONTHURSDAY(year) | date | Ascension Thursday, 39 days after Easter Sunday |
ASHWEDNESDAY(year) | date | Ash Wednesday, 46 days before Easter Sunday |
GOODFRIDAY(year) | date | Good Friday, 2 days before Easter Sunday |
PENTECOSTSUNDAY(year) | date | Pentecost Sunday, 49 days after Easter Sunday |
DATE2JULIAN(date) | number | the Julian day number of a date |
HDATE_JULIAN(year, month, day) | number | the Julian day number of Gregorian year, month, day (out-of-range days and months roll over) |
HDATE(year, month, day) | text | the Hebrew date of Gregorian year, month, day, as "20 Tebet 5784" (#VALUE! for a month outside 1–12 or a day outside 1–31) |
HDATE_HEB(year, month, day) | text | the Hebrew date of Gregorian year, month, day in Hebrew, as "כ׳ בְּטֵבֵת התשפ״ד" |
HDATE_DAY(year, month, day) | number | the day of the Hebrew month of Gregorian year, month, day |
HDATE_MONTH(year, month, day) | number | the Hebrew month of Gregorian year, month, day: 0 Tishri … 11 Elul, 12 Adar I, 13 Adar II |
HDATE_YEAR(year, month, day) | number | the Hebrew year of Gregorian year, month, day |
DATE2HDATE(date) | text | the Hebrew date of a date, as "20 Tebet 5784" |
DATE2HDATE_HEB(date) | text | the Hebrew date of a date in Hebrew |
Dimensional
Functions of a cell's position in a category, and the ordered (previous/next, running) forms.
| Function | Returns | Description |
|---|---|---|
POSITION(category) | number | 1-based position of this cell's item along the category |
@ITEM(category) | text | the name of this cell's item along the category |
@ID(category) | text | the item name (Improv item names are unique within a category) |
@ITEMCOUNT(category) | number | the number of items in the category |
PREV(x, category, [n=1], [default]) | the branches' type | the value at the n-th previous item along the category (n = 1); off the end, the default, else no cell |
NEXT(x, category, [n=1], [default]) | the branches' type | the value at the n-th next item along the category (n = 1); off the end, the default, else no cell |
SEQUENCE(T, [start=1], [step=1]) | the branches' type | SEQUENCE(T, [start=1], [step=1]): start, start + step, … along T's items, (POSITION(T) - 1) * step + start |
RELABEL(x, from_category, to_category) | the branches' type | x read with category From replaced by To, each item mapped to To's item of the same name (items with no namesake are dropped) |
SWAP(x, category_a, category_b) | the branches' type | x read with categories A and B exchanged, items matched by name (W at Src = a, Dst = b is SWAP(W, Src, Dst) at Src = b, Dst = a) |
FIXPOINT(init, lambda, [max_iter=100], [tolerance=1e-10]) | the branches' type | FIXPOINT(init, LAMBDA(r, body), [max_iter=100], [tolerance=1e-10]): r = init, then r = body(r) until the cells change by at most tolerance in total (Σ |
FILL(x, default) | the branches' type | a cell at every item combination of x's categories: x where it has a cell, else the default |
SORT(array OVER T, [sort_order=1] INTO K) | the branches' type | the values in ascending order (descending when sort_order is -1) |
UNIQUE(array OVER T, [exactly_once=FALSE] INTO K) | the branches' type | each distinct value once, in item order (only values that occur once when exactly_once is TRUE) |
FILTER(array, include OVER T, [if_empty] INTO K) | the branches' type | the values of array whose include is TRUE, in item order; if none, if_empty (else #N/A: Excel's #CALC!) |
SORTBY(array, by_array1 OVER T, [sort_order1], … INTO K) | the branches' type | SORTBY(array, by_array1 OVER T, [sort_order1], [by_array2, sort_order2], …): the values of array sorted by by_array1, ties by by_array2, … (stable; a key descends when its order is -1) |
TAKE(array OVER T, rows INTO K) | the branches' type | the first rows values in item order (the last -rows when rows is negative) |
DROP(array OVER T, rows INTO K) | the branches' type | the values TAKE leaves out: all but the first rows (the last -rows when rows is negative), in item order |
SELECTS(values, tests OVER T, condition INTO K) | the branches' type | Quantrix: the values whose test meets the condition (a criterion like ">5" or "a*", as in SUMIF), in item order |
XLOOKUP(lookup_value, lookup_array OVER T, return_array, [if_not_found], [match_mode=0], [search_mode=1]) | the values' type | return_array at the item where lookup_array matches lookup_value (match_mode 0 exact, -1 next smaller, 1 next larger, 2 wildcard; search_mode 1 first to last, -1 last to first, ±2 the same as ±1); if_not_found (else #N/A) when none does |
XMATCH(lookup_value, lookup_array OVER T, [match_mode=0], [search_mode=1]) | number | the 1-based item position along the category where lookup_array matches lookup_value (XLOOKUP's modes); #N/A when none does |
MATCH(lookup_value, lookup_array OVER T, [match_type=1]) | number | the 1-based item position of lookup_value: match_type 1 (default) the largest ≤ it, 0 the first equal (text with * and ? wildcards), -1 the smallest ≥ it; #N/A when none |
LOOKUP(lookup_value, lookup_vector OVER T, result_vector) | the values' type | result_vector at the largest lookup_vector ≤ lookup_value (ascending); #N/A when none |
INDEX(array OVER T, row_num) | the branches' type | the value at the row_num-th item (1-based); #REF! out of range, #N/A where that item has no cell (also VALUEAT) |
SELECT(values, keys OVER T, lookup) | the branches' type | values at the first item (in item order) whose key equals lookup; #N/A when none (SELECTLIST: a lookup over its own category gives one result per lookup) (also SELECTLIST) |
SELECTBETWEEN(values, keys OVER T, low, high, [inclusive]) | the branches' type | values at the first item whose key is between low and high (strictly when inclusive is FALSE); #N/A when none |
SELECTGREATERTHAN(values, keys OVER T, lookup, [inclusive]) | the branches' type | values at the first item whose key is > lookup (≥ when inclusive is TRUE); #N/A when none |
SELECTLESSTHAN(values, keys OVER T, lookup, [inclusive]) | the branches' type | values at the first item whose key is < lookup (≤ when inclusive is TRUE); #N/A when none |
Statistical
| Function | Returns | Description |
|---|---|---|
MODE.MULT(values OVER T INTO K) | number | every most frequent value, in order of first occurrence (#N/A if none repeats) |
LINEST(known_ys, known_xs1, … OVER T, [const=TRUE], [stats=FALSE] INTO K) | number | LINEST(known_ys, known_xs1, [known_xs2, …] OVER T, [const], [stats]): the least-squares fit y = m1·x1 + … + b: mk, …, m1, b (const = FALSE: b = 0); with stats, Excel's 5×(k+1) block row by row (one x: m, b, se_m, se_b, r², se_y, F, df, ss_reg, ss_resid); INTO R, C lays it out as the block |
LOGEST(known_ys, known_xs1, … OVER T, [const=TRUE], [stats=FALSE] INTO K) | number | LOGEST(known_ys, known_xs1, [known_xs2, …] OVER T, [const], [stats]): y = b·m1^x1·…, fitted to ln y: mk, …, m1, b (const = FALSE: b = 1); with stats LINEST's block, for ln y |
FREQUENCY(data_array OVER T, bin1, … INTO K) | number | counts of x in the bins given as numbers b1, b2, …: ≤ b1, (b1, b2], …, > bn (n + 1 counts; Excel takes the bins as a range) |
BETA.DIST(x, alpha, beta, cumulative, [a=0], [b=1]) | number | the beta distribution of x on [A, B] (default [0, 1]): density, or cumulative |
BETADIST(x, alpha, beta, [a=0], [b=1]) | number | the cumulative beta distribution of x on [A, B] (default [0, 1]) |
BETA.INV(probability, alpha, beta, [a=0], [b=1]) | number | the beta quantile on [A, B] (default [0, 1]) (also BETAINV) |
BINOM.DIST(number_s, trials, probability_s, cumulative) | number | the binomial probability of k successes in n trials: P(K = k), or P(K ≤ k) (also BINOMDIST) |
BINOM.INV(trials, probability_s, alpha) | number | the smallest k with binomial P(K ≤ k) ≥ alpha, for n trials of probability p (also CRITBINOM) |
BINOM.DIST.RANGE(trials, probability_s, number_s, [number_s2]) | number | the binomial P(k1 ≤ K ≤ k2) for n trials of probability p (k2 defaults to k1) (also B) |
CHISQ.DIST(x, deg_freedom, cumulative) | number | the chi-square distribution: density, or left tail (also CHISQDIST) |
CHISQ.DIST.RT(x, deg_freedom) | number | the chi-square right tail (also CHIDIST) |
CHISQ.INV(probability, deg_freedom) | number | the chi-square left-tail quantile (also CHISQINV) |
CHISQ.INV.RT(probability, deg_freedom) | number | the chi-square right-tail quantile (also CHIINV) |
EXPON.DIST(x, lambda, cumulative) | number | the exponential distribution of rate λ: density, or cumulative (also EXPONDIST) |
F.DIST(x, deg_freedom1, deg_freedom2, cumulative) | number | the F distribution: density, or left tail |
F.DIST.RT(x, deg_freedom1, deg_freedom2) | number | the F right tail (also FDIST) |
F.INV(probability, deg_freedom1, deg_freedom2) | number | the F left-tail quantile |
F.INV.RT(probability, deg_freedom1, deg_freedom2) | number | the F right-tail quantile (also FINV) |
GAMMA.DIST(x, alpha, beta, cumulative) | number | the gamma distribution of shape α and scale β: density, or cumulative (also GAMMADIST) |
GAMMA.INV(probability, alpha, beta) | number | the gamma quantile (also GAMMAINV) |
GAUSS(z) | number | Φ(z) − 0.5: the standard normal probability between 0 and z |
HYPGEOM.DIST(sample_s, number_sample, population_s, number_pop, cumulative) | number | the hypergeometric probability of k successes in a sample of n from N holding K: P(X = k), or P(X ≤ k) |
HYPGEOMDIST(sample_s, number_sample, population_s, number_pop) | number | the hypergeometric probability P(X = k) |
LOGNORM.DIST(x, mean, standard_dev, cumulative) | number | the log-normal distribution: density, or cumulative |
LOGNORMDIST(x, mean, standard_dev) | number | the cumulative log-normal distribution |
LOGNORM.INV(probability, mean, standard_dev) | number | the log-normal quantile (also LOGINV) |
NEGBINOM.DIST(number_f, number_s, probability_s, cumulative) | number | the negative binomial probability of f failures before the s-th success: P(F = f), or P(F ≤ f) |
NEGBINOMDIST(number_f, number_s, probability_s) | number | the negative binomial probability P(F = f) |
NORM.DIST(x, mean, standard_dev, cumulative) | number | the normal distribution: density, or cumulative (also NORMDIST) |
NORM.INV(probability, mean, standard_dev) | number | the normal quantile (also NORMINV) |
NORM.S.DIST(z, cumulative) | number | the standard normal distribution: density, or cumulative |
NORMSDIST(z) | number | the cumulative standard normal distribution Φ(z) |
NORM.S.INV(probability) | number | the standard normal quantile (also NORMSINV) |
PHI(x) | number | the standard normal density |
POISSON.DIST(x, mean, cumulative) | number | the Poisson probability of k events at mean λ: P(X = k), or P(X ≤ k) (also POISSON) |
T.DIST(x, deg_freedom, cumulative) | number | Student's t distribution: density, or left tail |
T.DIST.RT(x, deg_freedom) | number | Student's t right tail |
T.DIST.2T(x, deg_freedom) | number | Student's t two-tailed probability |
TDIST(x, deg_freedom, tails) | number | Student's t right tail (tails = 1) or two-tailed probability (tails = 2), for x ≥ 0 |
T.INV(probability, deg_freedom) | number | Student's t left-tail quantile |
T.INV.2T(probability, deg_freedom) | number | Student's t two-tailed quantile (also TINV) |
WEIBULL.DIST(x, alpha, beta, cumulative) | number | the Weibull distribution of shape α and scale β: density, or cumulative (also WEIBULL) |
FISHER(x) | number | the Fisher transformation atanh(x) |
FISHERINV(y) | number | the inverse Fisher transformation tanh(y) |
CONFIDENCE.NORM(alpha, standard_dev, size) | number | the half-width of a normal confidence interval at significance alpha, for sd and sample size n (also CONFIDENCE) |
CONFIDENCE.T(alpha, standard_dev, size) | number | the half-width of a Student's t confidence interval at significance alpha, for sd and sample size n |
STANDARDIZE(x, mean, standard_dev) | number | the z-score (x − mean) / sd |
AVERAGEA(values OVER T) | number | the mean, counting TRUE as 1 and text and FALSE as 0 |
AVERAGEIF(range OVER T, criteria, [average_range]) | number | the mean of average_range (else range) where range meets the criteria |
AVERAGEIFS(average_range, criteria_range1 OVER T, criteria1, …) | number | the mean of x where every criteria measure meets its criterion |
AVEDEV(values OVER T) | number | the mean absolute deviation from the mean |
COUNT(values OVER T) | number | the number of numbers (and dates) (also DCOUNT) |
COUNTA(values OVER T) | number | the number of cells (errors included) (also DCOUNTA) |
COUNTUNIQUE(values OVER T) | number | the number of distinct values, SQL's count(DISTINCT …) (text compares case-sensitively; an error among them is the result) |
COUNTBLANK(range OVER T) | number | the number of items with no cell (or empty text) |
COUNTIF(range OVER T, criteria) | number | the number of cells meeting the criterion (">5", "<>x", "a*", 3) |
COUNTIFS(criteria_range1 OVER T, criteria1, …) | number | the number of rows where every criteria measure meets its criterion |
SUMIF(range OVER T, criteria, [sum_range]) | number | the sum of sum_range (else range) where range meets the criteria |
SUMIFS(sum_range, criteria_range1 OVER T, criteria1, …) | number | the sum of x where every criteria measure meets its criterion |
MAXA(values OVER T) | number | the largest value, counting TRUE as 1 and text and FALSE as 0 |
MAXIFS(max_range, criteria_range1 OVER T, criteria1, …) | number | the largest x where every criteria measure meets its criterion (0 if none) |
MINA(values OVER T) | number | the smallest value, counting TRUE as 1 and text and FALSE as 0 |
MINIFS(min_range, criteria_range1 OVER T, criteria1, …) | number | the smallest x where every criteria measure meets its criterion (0 if none) |
MEDIAN(values OVER T) | number | the median |
MODE(values OVER T) | number | the most frequent value (the first in item order on a tie; #N/A if none repeats) (also MODE.SNGL) |
GEOMEAN(values OVER T) | number | the geometric mean (#NUM! for a value ≤ 0) |
HARMEAN(values OVER T) | number | the harmonic mean (#NUM! for a value ≤ 0) |
TRIMMEAN(array OVER T, percent) | number | the mean without the fraction of values at the tails (rounded down to an even count) |
DEVSQ(values OVER T) | number | Σ(x − mean)² |
STDEV(values OVER T) | number | the sample standard deviation (also STDEV.S, DSTDEV) |
STDEVP(values OVER T) | number | the population standard deviation (also STDEV.P, DSTDEVP) |
STDEVA(values OVER T) | number | the sample standard deviation, counting TRUE as 1 and text and FALSE as 0 |
STDEVPA(values OVER T) | number | the population standard deviation, counting TRUE as 1 and text and FALSE as 0 |
VAR(values OVER T) | number | the sample variance (also VAR.S, DVAR) |
VARP(values OVER T) | number | the population variance (also VAR.P, DVARP) |
VARA(values OVER T) | number | the sample variance, counting TRUE as 1 and text and FALSE as 0 |
VARPA(values OVER T) | number | the population variance, counting TRUE as 1 and text and FALSE as 0 |
KURT(values OVER T) | number | the sample excess kurtosis |
KURTP(values OVER T) | number | the population excess kurtosis |
SKEW(values OVER T) | number | the sample skewness |
SKEWP(values OVER T) | number | the population skewness (also SKEW.P) |
LARGE(array OVER T, k) | number | the k-th largest value |
SMALL(array OVER T, k) | number | the k-th smallest value |
PERCENTILE(array OVER T, k) | number | the p-th percentile, interpolated, 0 ≤ p ≤ 1 (also PERCENTILE.INC) |
PERCENTILE.EXC(array OVER T, k) | number | the p-th percentile, exclusive of 0 and 1 |
QUARTILE(array OVER T, quart) | number | the q-th quartile (0 min … 4 max) (also QUARTILE.INC) |
QUARTILE.EXC(array OVER T, quart) | number | the q-th quartile (1 … 3), exclusive |
PROB(x_range, prob_range OVER T, lower_limit, [upper_limit]) | number | Σ p over the values x in [low, high] (x = low without high); #NUM! unless every 0 < p ≤ 1 and Σ p = 1 |
SUBTOTAL(function_num, values OVER T) | number | the reduction a code picks: 1 AVERAGE, 2 COUNT, 3 COUNTA, 4 MAX, 5 MIN, 6 PRODUCT, 7 STDEV, 8 STDEVP, 9 SUM, 10 VAR, 11 VARP (101–111 the same) |
AGGREGATE(function_num, options, array OVER T, [k]) | number | SUBTOTAL's codes and 12 MEDIAN, 13 MODE, 14 LARGE, 15 SMALL, 16 PERCENTILE, 17 QUARTILE, 18 PERCENTILE.EXC, 19 QUARTILE.EXC; options 2, 3, 6, 7 skip errors |
RANK(ref OVER T, [order=0]) | number | each item's rank among the values (order 0, the default, ranks the largest 1) (also RANK.EQ) |
RANK.AVG(ref OVER T, [order=0]) | number | each item's rank, ties sharing their mean rank |
PERCENTRANK(array OVER T, [x], [significance=3]) | number | each item's (or x's) rank as a fraction 0 … 1, to significance (3) significant digits (also PERCENTRANK.INC) |
RANK.DENSE(ref OVER T, [order=0]) | number | each item's dense rank: tied values share a rank and the next value ranks one after them, SQL's dense_rank() (order 0, the default, ranks the largest 1) |
PERCENTRANK.EXC(array OVER T, [x], [significance=3]) | number | each item's (or x's) rank as a fraction, exclusive of 0 and 1 |
TREND(known_ys, known_xs OVER T, [const=TRUE]) | number | each item's value on the least-squares line of y on x, at its own x (through 0 if const is FALSE) |
GROWTH(known_ys, known_xs OVER T, [const=TRUE]) | number | each item's value on the least-squares curve y = b·mˣ (fitting ln y; b = 1 if const is FALSE) |
CORREL(array1, array2 OVER T) | number | the Pearson correlation of x and y (also PEARSON) |
RSQ(known_ys, known_xs OVER T) | number | the square of the Pearson correlation |
COVAR(array1, array2 OVER T) | number | the population covariance (also COVARIANCE.P) |
COVARIANCE.S(array1, array2 OVER T) | number | the sample covariance |
SLOPE(known_ys, known_xs OVER T) | number | the least-squares slope of y on x |
INTERCEPT(known_ys, known_xs OVER T) | number | the least-squares intercept of y on x |
STEYX(known_ys, known_xs OVER T) | number | the standard error of the predicted y |
FORECAST(x, known_ys, known_xs OVER T) | number | the least-squares line of y on x at x0 (also FORECAST.LINEAR) |
EXPA(known_ys, known_xs OVER T, [simple]) | number | A of the fit y = A·e^(Bx): least squares of ln y weighted by y (simple = TRUE: unweighted, as LOGEST) |
EXPB(known_ys, known_xs OVER T, [simple]) | number | B of the fit y = A·e^(Bx) |
EXPFORECAST(x, known_ys, known_xs OVER T, [simple]) | number | the fit y = A·e^(Bx) at x0 |
CHITEST(actual_range, expected_range OVER T) | number | the χ² test p-value of actual against expected (also CHISQ.TEST) |
FTEST(array1, array2 OVER T) | number | the two-tailed F-test p-value that a and b have the same variance (also F.TEST) |
TTEST(array1, array2 OVER T, tails, type) | number | the t-test p-value (tails 1 or 2; type 1 paired, 2 equal variance, 3 unequal) (also T.TEST) |
ZTEST(array OVER T, x, [sigma]) | number | the one-tailed z-test p-value of the mean against μ0 (σ defaults to the sample's) (also Z.TEST) |
AUTOCORREL(values OVER T) | number | the lag-1 autocorrelation in item order (GSL) (also GSL_STATS_LAG1_AUTOCORRELATION) |
DGET(values OVER T) | the branches' type | the single value (with WHERE, the single match); #NUM! when more than one (a WHERE that keeps none leaves no cell) |
PROBBLOCK(traffic, circuits) | number | the Erlang-B probability that a call is blocked when traffic erlangs load circuits (1 to 10⁶; truncated below 100) |
OFFTRAF(traffic, circuits) | number | the offered traffic that carries traffic erlangs on circuits (#VALUE! if circuits cannot carry it) |
DIMCIRC(traffic, gos) | number | the fewest circuits (up to 10⁶) that carry traffic erlangs with blocking at most gos, 0 < gos ≤ 1 |
OFFCAP(circuits, gos) | number | the traffic circuits carry with blocking gos, 0 < gos < 1 |
BERNOULLI(k, p) | number | the Bernoulli probability of k (0 or 1) for success probability p |
CAUCHY(x, a, cumulative) | number | the Cauchy distribution of scale a at x: density, or (as Gnumeric) the right tail P(X > x) |
EXPPOWDIST(x, a, b) | number | the exponential-power density of scale a and exponent b at x |
GEOMDIST(k, p, cumulative) | number | the geometric probability of k failures before the first success: P(K = k), or P(K ≤ k) |
LANDAU(x) | number | the Landau density at x (Kölbig and Schorr's approximation, about 9 digits) |
LAPLACE(x, a) | number | the Laplace density of width a at x |
LOGISTIC(x, a) | number | the logistic density of scale a at x |
PARETO(x, a, b) | number | the Pareto density of exponent a and scale b at x |
RAYLEIGH(x, sigma) | number | the Rayleigh density of scale σ at x |
RAYLEIGHTAIL(x, a, sigma) | number | the Rayleigh tail density (lower limit a, scale σ) at x |
SNORM.DIST.RANGE(x1, x2) | number | Φ(x2) − Φ(x1): the standard normal probability between x1 and x2 |
OWENT(h, a) | number | Owen's T function T(h, a) |
CUM_BIV_NORM_DIST(a, b, rho) | number | the standard bivariate normal P(X ≤ a, Y ≤ b) with correlation ρ, |
R.DBETA(x, shape1, shape2, [give_log]) | number | the density at x of the beta distribution of shapes shape1 and shape2, or its logarithm (give_log) |
R.PBETA(x, shape1, shape2, [lower_tail], [log_p]) | number | P(X ≤ x) for the beta distribution of shapes shape1 and shape2, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QBETA(p, shape1, shape2, [lower_tail], [log_p]) | number | the quantile of the beta distribution of shapes shape1 and shape2: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DBINOM(x, size, prob, [give_log]) | number | the probability mass at x of the binomial distribution of size trials of success probability prob, or its logarithm (give_log) |
R.PBINOM(x, size, prob, [lower_tail], [log_p]) | number | P(X ≤ x) for the binomial distribution of size trials of success probability prob, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QBINOM(p, size, prob, [lower_tail], [log_p]) | number | the quantile of the binomial distribution of size trials of success probability prob: the smallest x with P(X ≤ x) ≥ p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DCAUCHY(x, location, scale, [give_log]) | number | the density at x of the Cauchy distribution of location and scale, or its logarithm (give_log) |
R.PCAUCHY(x, location, scale, [lower_tail], [log_p]) | number | P(X ≤ x) for the Cauchy distribution of location and scale, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QCAUCHY(p, location, scale, [lower_tail], [log_p]) | number | the quantile of the Cauchy distribution of location and scale: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DCHISQ(x, df, [give_log]) | number | the density at x of the chi-square distribution of df degrees of freedom, or its logarithm (give_log) |
R.PCHISQ(x, df, [lower_tail], [log_p]) | number | P(X ≤ x) for the chi-square distribution of df degrees of freedom, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QCHISQ(p, df, [lower_tail], [log_p]) | number | the quantile of the chi-square distribution of df degrees of freedom: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DEXP(x, scale, [give_log]) | number | the density at x of the exponential distribution of the given scale (mean), or its logarithm (give_log) |
R.PEXP(x, scale, [lower_tail], [log_p]) | number | P(X ≤ x) for the exponential distribution of the given scale (mean), or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QEXP(p, scale, [lower_tail], [log_p]) | number | the quantile of the exponential distribution of the given scale (mean): the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DF(x, df1, df2, [give_log]) | number | the density at x of the F distribution of df1 and df2 degrees of freedom, or its logarithm (give_log) |
R.PF(x, df1, df2, [lower_tail], [log_p]) | number | P(X ≤ x) for the F distribution of df1 and df2 degrees of freedom, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QF(p, df1, df2, [lower_tail], [log_p]) | number | the quantile of the F distribution of df1 and df2 degrees of freedom: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DGAMMA(x, shape, scale, [give_log]) | number | the density at x of the gamma distribution of shape and scale, or its logarithm (give_log) |
R.PGAMMA(x, shape, scale, [lower_tail], [log_p]) | number | P(X ≤ x) for the gamma distribution of shape and scale, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QGAMMA(p, shape, scale, [lower_tail], [log_p]) | number | the quantile of the gamma distribution of shape and scale: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DGEOM(x, prob, [give_log]) | number | the probability mass at x of the geometric distribution (failures before the first success) of success probability prob, or its logarithm (give_log) |
R.PGEOM(x, prob, [lower_tail], [log_p]) | number | P(X ≤ x) for the geometric distribution (failures before the first success) of success probability prob, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QGEOM(p, prob, [lower_tail], [log_p]) | number | the quantile of the geometric distribution (failures before the first success) of success probability prob: the smallest x with P(X ≤ x) ≥ p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DGUMBEL(x, mu, beta, [give_log]) | number | the density at x of the Gumbel distribution of location μ and scale β, or its logarithm (give_log) |
R.PGUMBEL(x, mu, beta, [lower_tail], [log_p]) | number | P(X ≤ x) for the Gumbel distribution of location μ and scale β, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QGUMBEL(p, mu, beta, [lower_tail], [log_p]) | number | the quantile of the Gumbel distribution of location μ and scale β: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DHYPER(x, m, n, k, [give_log]) | number | the probability mass at x of the hypergeometric distribution of the white balls among k drawn from m white and n black, or its logarithm (give_log) |
R.PHYPER(x, m, n, k, [lower_tail], [log_p]) | number | P(X ≤ x) for the hypergeometric distribution of the white balls among k drawn from m white and n black, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QHYPER(p, m, n, k, [lower_tail], [log_p]) | number | the quantile of the hypergeometric distribution of the white balls among k drawn from m white and n black: the smallest x with P(X ≤ x) ≥ p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DLNORM(x, meanlog, sdlog, [give_log]) | number | the density at x of the log-normal distribution of log-mean and log-sd, or its logarithm (give_log) |
R.PLNORM(x, meanlog, sdlog, [lower_tail], [log_p]) | number | P(X ≤ x) for the log-normal distribution of log-mean and log-sd, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QLNORM(p, meanlog, sdlog, [lower_tail], [log_p]) | number | the quantile of the log-normal distribution of log-mean and log-sd: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DNBINOM(x, size, prob, [give_log]) | number | the probability mass at x of the negative binomial distribution (failures before the size-th success) of success probability prob, or its logarithm (give_log) |
R.PNBINOM(x, size, prob, [lower_tail], [log_p]) | number | P(X ≤ x) for the negative binomial distribution (failures before the size-th success) of success probability prob, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QNBINOM(p, size, prob, [lower_tail], [log_p]) | number | the quantile of the negative binomial distribution (failures before the size-th success) of success probability prob: the smallest x with P(X ≤ x) ≥ p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DNORM(x, mean, sd, [give_log]) | number | the density at x of the normal distribution of mean μ and standard deviation σ, or its logarithm (give_log) |
R.PNORM(x, mean, sd, [lower_tail], [log_p]) | number | P(X ≤ x) for the normal distribution of mean μ and standard deviation σ, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QNORM(p, mean, sd, [lower_tail], [log_p]) | number | the quantile of the normal distribution of mean μ and standard deviation σ: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DPOIS(x, lambda, [give_log]) | number | the probability mass at x of the Poisson distribution of mean λ, or its logarithm (give_log) |
R.PPOIS(x, lambda, [lower_tail], [log_p]) | number | P(X ≤ x) for the Poisson distribution of mean λ, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QPOIS(p, lambda, [lower_tail], [log_p]) | number | the quantile of the Poisson distribution of mean λ: the smallest x with P(X ≤ x) ≥ p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DRAYLEIGH(x, scale, [give_log]) | number | the density at x of the Rayleigh distribution of the given scale, or its logarithm (give_log) |
R.PRAYLEIGH(x, scale, [lower_tail], [log_p]) | number | P(X ≤ x) for the Rayleigh distribution of the given scale, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QRAYLEIGH(p, scale, [lower_tail], [log_p]) | number | the quantile of the Rayleigh distribution of the given scale: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DSNORM(x, shape, location, scale, [give_log]) | number | the density at x of the skew-normal distribution of shape, location and scale, or its logarithm (give_log) |
R.PSNORM(x, shape, location, scale, [lower_tail], [log_p]) | number | P(X ≤ x) for the skew-normal distribution of shape, location and scale, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QSNORM(p, shape, location, scale, [lower_tail], [log_p]) | number | the quantile of the skew-normal distribution of shape, location and scale: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DST(x, df, shape, [give_log]) | number | the density at x of the skew-t distribution of df degrees of freedom and the given shape, or its logarithm (give_log) |
R.PST(x, df, shape, [lower_tail], [log_p]) | number | P(X ≤ x) for the skew-t distribution of df degrees of freedom and the given shape, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QST(p, df, shape, [lower_tail], [log_p]) | number | the quantile of the skew-t distribution of df degrees of freedom and the given shape: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DT(x, df, [give_log]) | number | the density at x of the Student t distribution of df degrees of freedom, or its logarithm (give_log) |
R.PT(x, df, [lower_tail], [log_p]) | number | P(X ≤ x) for the Student t distribution of df degrees of freedom, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QT(p, df, [lower_tail], [log_p]) | number | the quantile of the Student t distribution of df degrees of freedom: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.DWEIBULL(x, shape, scale, [give_log]) | number | the density at x of the Weibull distribution of shape and scale, or its logarithm (give_log) |
R.PWEIBULL(x, shape, scale, [lower_tail], [log_p]) | number | P(X ≤ x) for the Weibull distribution of shape and scale, or P(X > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QWEIBULL(p, shape, scale, [lower_tail], [log_p]) | number | the quantile of the Weibull distribution of shape and scale: the x with P(X ≤ x) = p, or of P(X > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
R.PTUKEY(x, nmeans, df, [nranges=1], [lower_tail], [log_p]) | number | P(Q ≤ x) for the largest of nranges (default 1) studentized ranges of nmeans means with df degrees of freedom, or P(Q > x) (lower_tail = FALSE), or its logarithm (log_p) |
R.QTUKEY(p, nmeans, df, [nranges=1], [lower_tail], [log_p]) | number | the quantile of the studentized range of nmeans means with df degrees of freedom, the largest of nranges (default 1): the x with P(Q ≤ x) = p, or of P(Q > x) (lower_tail = FALSE), p may be a logarithm (log_p) |
SSMEDIAN(array OVER T, [interval=1]) | number | the median of grouped data (Gnumeric): each value the midpoint of an interval of width interval (default 1), interpolated within the median's interval |
INTERPOLATION(xs, ys OVER T, target, [method], [next]) | number | INTERPOLATION(xs, ys OVER T, target, [method], [next]): ys interpolated at target (Gnumeric): method 0 linear, 2 staircase, 4 natural cubic spline; 1, 3, 5 the same averaged over [target, next] |
HPFILTER(values OVER T, [lambda=1600]) | number | each item's trend under the Hodrick–Prescott filter with smoothing λ (default 1600); the cycle is y − trend; needs 6 values |
ADTEST(values OVER T) | number | the p-value of the Anderson–Darling test of normality (Gnumeric; 8 values or more) |
CVMTEST(values OVER T) | number | the p-value of the Cramér–von Mises test of normality (Gnumeric; 8 values or more) |
LKSTEST(values OVER T) | number | the p-value of the Lilliefors (Kolmogorov–Smirnov) test of normality (Gnumeric; 5 values or more) |
SFTEST(values OVER T) | number | the p-value of the Shapiro–Francia test of normality (Gnumeric; 5 to 5000 values) |
ADTEST.STAT(values OVER T) | number | the Anderson–Darling statistic A² (adjusted for n), Gnumeric's ADTEST second value |
CVMTEST.STAT(values OVER T) | number | the Cramér–von Mises statistic W², Gnumeric's CVMTEST second value |
LKSTEST.STAT(values OVER T) | number | the Lilliefors statistic D, Gnumeric's LKSTEST second value |
SFTEST.STAT(values OVER T) | number | the Shapiro–Francia statistic W', Gnumeric's SFTEST second value |
LOGREG(known_ys, known_xs OVER T, [affine], [stats] INTO K) | number | LOGREG(known_ys, known_xs OVER T, [affine], [stats] INTO K): the least-squares fit y = m·ln x + b (Gnumeric): m, b (affine = FALSE: b = 0); with stats LINEST's 5×2 block for ln x, row by row |
LOGFIT(known_ys, known_xs OVER T INTO K) | number | LOGFIT(known_ys, known_xs OVER T INTO K): the fit y = a + b·ln(sign·(x − c)) by Gnumeric's trial-and-error search: sign, a, b, c and the sum of squared residuals; #NUM! if the points are not logarithmic enough |
PERIODOGRAM(y OVER T, [filter] INTO K) | number | PERIODOGRAM(y OVER T, [filter] INTO K): the magnitudes of the first half of the Fourier transform (Gnumeric), after a window: 0 none, 1 Bartlett, 2 Hann, 3 Welch |
CRONBACH(x1, x2, … OVER T) | number | CRONBACH(x1, x2, … OVER T): Cronbach's α of the items x1, x2, … (one row per respondent; population variances, as Gnumeric) |
FORECAST.ETS(target_date, values, timeline OVER T, [seasonality], [data_completion], [aggregation]) | number | FORECAST.ETS(target_date, values, timeline OVER T, [seasonality], [data_completion], [aggregation]): the additive Holt–Winters (triple exponential smoothing) forecast at target_date, LibreOffice's algorithm; seasonality 1 detects the season, 0 none; a target_date before the timeline's end is #NUM! (also FORECAST.ETS.ADD) |
FORECAST.ETS.MULT(target_date, values, timeline OVER T, [seasonality], [data_completion], [aggregation]) | number | FORECAST.ETS.MULT(target_date, values, timeline OVER T, …): FORECAST.ETS with multiplicative seasons (LibreOffice) |
FORECAST.ETS.CONFINT(target_date, values, timeline OVER T, [confidence_level=0.95], [seasonality], [data_completion], [aggregation]) | number | FORECAST.ETS.CONFINT(target_date, values, timeline OVER T, [confidence_level], [seasonality], …): the half-width of the prediction interval (default confidence_level 0.95); only for seasonality 0 (LibreOffice simulates seasonal intervals randomly): otherwise #N/A (also FORECAST.ETS.PI.ADD) |
FORECAST.ETS.PI.MULT(target_date, values, timeline OVER T, [confidence_level=0.95], [seasonality], [data_completion], [aggregation]) | number | FORECAST.ETS.PI.MULT(target_date, values, timeline OVER T, …): FORECAST.ETS.CONFINT for the multiplicative model (the same for seasonality 0, the only one supported) |
FORECAST.ETS.STAT(values, timeline OVER T, statistic_type, [seasonality], [data_completion], [aggregation]) | number | FORECAST.ETS.STAT(values, timeline OVER T, statistic_type, …): a statistic of FORECAST.ETS's fit: 1 α, 2 β (trend), 3 γ (season), 4 MASE, 5 SMAPE, 6 MAE, 7 RMSE, 8 step, 9 seasonality (also FORECAST.ETS.STAT.ADD) |
FORECAST.ETS.STAT.MULT(values, timeline OVER T, statistic_type, [seasonality], [data_completion], [aggregation]) | number | FORECAST.ETS.STAT.MULT(values, timeline OVER T, statistic_type, …): FORECAST.ETS.STAT of the multiplicative model |
FORECAST.ETS.SEASONALITY(values, timeline OVER T, [data_completion], [aggregation]) | number | FORECAST.ETS.SEASONALITY(values, timeline OVER T, [data_completion], [aggregation]): the season length FORECAST.ETS detects (1: none) |
LEVERAGE(A OVER R, C INTO K) | number | LEVERAGE(A OVER R, C INTO K): the regression leverages, the diagonal of A·(AᵀA)⁻¹·Aᵀ, one per row of A (Gnumeric); #NUM! if A's columns are dependent |
Financial
Rates are per period; cash flows are in item order along their OVER category.
| Function | Returns | Description |
|---|---|---|
FV(rate, nper, pmt, [pv], [type]) | number | future value: FV(rate, nper, pmt, [pv], [type]) |
PV(rate, nper, pmt, [fv], [type]) | number | present value: PV(rate, nper, pmt, [fv], [type]) |
PMT(rate, nper, pv, [fv], [type]) | number | payment per period: PMT(rate, nper, pv, [fv], [type]) |
IPMT(rate, per, nper, pv, [fv], [type]) | number | interest part of payment per: IPMT(rate, per, nper, pv, [fv], [type]) |
PPMT(rate, per, nper, pv, [fv], [type]) | number | principal part of payment per: PPMT(rate, per, nper, pv, [fv], [type]) |
NPER(rate, pmt, pv, [fv], [type]) | number | number of periods: NPER(rate, pmt, pv, [fv], [type]) |
RATE(nper, pmt, pv, [fv], [type], [guess]) | number | rate per period (iterative): RATE(nper, pmt, pv, [fv], [type], [guess]) |
CUMIPMT(rate, nper, pv, start_period, end_period, type) | number | interest paid from period start to end: CUMIPMT(rate, nper, pv, start_period, end_period, type) (also CUMIPMT_ADD) |
CUMPRINC(rate, nper, pv, start_period, end_period, type) | number | principal paid from period start to end: CUMPRINC(rate, nper, pv, start_period, end_period, type) (also CUMPRINC_ADD) |
ISPMT(rate, per, nper, pv) | number | interest of period per with straight-line principal: ISPMT(rate, per, nper, pv) |
EFFECT(nominal_rate, npery) | number | effective annual rate of a nominal rate compounded npery times (also EFFECT_ADD) |
NOMINAL(effect_rate, npery) | number | nominal annual rate of an effective rate compounded npery times (also NOMINAL_ADD) |
PDURATION(rate, pv, fv) | number | periods for pv to grow to fv at rate: PDURATION(rate, pv, fv) (also G_DURATION) |
RRI(nper, pv, fv) | number | equivalent growth rate per period: RRI(nper, pv, fv) |
DOLLARDE(fractional_dollar, fraction) | number | a fractional dollar price (1.02 with fraction 16 is 1 and 2/16) as a decimal |
DOLLARFR(decimal_dollar, fraction) | number | a decimal dollar price as a fraction (in the integer part's units) |
SLN(cost, salvage, life) | number | straight-line depreciation per period: SLN(cost, salvage, life) |
SYD(cost, salvage, life, per) | number | sum-of-years'-digits depreciation: SYD(cost, salvage, life, per) |
DB(cost, salvage, life, period, [month=12]) | number | fixed declining balance: DB(cost, salvage, life, period, [month=12]) |
DDB(cost, salvage, life, period, [factor=2]) | number | double declining balance: DDB(cost, salvage, life, period, [factor=2]) |
VDB(cost, salvage, life, start_period, end_period, [factor=2], [no_switch]) | number | declining balance between two periods: VDB(cost, salvage, life, start_period, end_period, [factor=2], [no_switch]) |
AMORDEGRC(cost, date_purchased, first_period, salvage, period, rate, [basis]) | number | French degressive depreciation: AMORDEGRC(cost, date_purchased, first_period, salvage, period, rate, [basis]) |
AMORLINC(cost, date_purchased, first_period, salvage, period, rate, [basis]) | number | French linear depreciation: AMORLINC(cost, date_purchased, first_period, salvage, period, rate, [basis]) |
ACCRINT(issue, first_interest, settlement, rate, par, frequency, [basis], [calc_method]) | number | accrued interest of a periodic-coupon security: ACCRINT(issue, first_interest, settlement, rate, par, frequency, [basis], [calc_method]) |
ACCRINTM(issue, settlement, rate, [par=1000], [basis]) | number | accrued interest paid at maturity: ACCRINTM(issue, settlement, rate, [par=1000], [basis]) |
COUPDAYBS(settlement, maturity, frequency, [basis]) | number | days from the coupon period's start to settlement |
COUPDAYS(settlement, maturity, frequency, [basis]) | number | days in the coupon period holding settlement |
COUPDAYSNC(settlement, maturity, frequency, [basis]) | number | days from settlement to the next coupon |
COUPNCD(settlement, maturity, frequency, [basis]) | date | the next coupon date after settlement |
COUPNUM(settlement, maturity, frequency, [basis]) | number | coupons payable between settlement and maturity |
COUPPCD(settlement, maturity, frequency, [basis]) | date | the coupon date on or before settlement |
DISC(settlement, maturity, pr, redemption, [basis]) | number | discount rate: DISC(settlement, maturity, pr, redemption, [basis]) |
DURATION(settlement, maturity, coupon, yld, frequency, [basis]) | number | Macaulay duration: DURATION(settlement, maturity, coupon, yld, frequency, [basis]) (also BONDDURATION) |
MDURATION(settlement, maturity, coupon, yld, frequency, [basis]) | number | modified duration: MDURATION(settlement, maturity, coupon, yld, frequency, [basis]) (also BONDMDURATION) |
INTRATE(settlement, maturity, investment, redemption, [basis]) | number | interest rate of a fully invested security: INTRATE(settlement, maturity, investment, redemption, [basis]) |
ODDFPRICE(settlement, maturity, issue, first_coupon, rate, yld, redemption, frequency, [basis]) | number | price with an odd first period: ODDFPRICE(settlement, maturity, issue, first_coupon, rate, yld, redemption, frequency, [basis]) |
ODDFYIELD(settlement, maturity, issue, first_coupon, rate, pr, redemption, frequency, [basis]) | number | yield with an odd first period: ODDFYIELD(settlement, maturity, issue, first_coupon, rate, pr, redemption, frequency, [basis]) |
ODDLPRICE(settlement, maturity, last_interest, rate, yld, redemption, frequency, [basis]) | number | price with an odd last period: ODDLPRICE(settlement, maturity, last_interest, rate, yld, redemption, frequency, [basis]) |
ODDLYIELD(settlement, maturity, last_interest, rate, pr, redemption, frequency, [basis]) | number | yield with an odd last period: ODDLYIELD(settlement, maturity, last_interest, rate, pr, redemption, frequency, [basis]) |
PRICE(settlement, maturity, rate, yld, redemption, frequency, [basis]) | number | price per 100 face value: PRICE(settlement, maturity, rate, yld, redemption, frequency, [basis]) |
PRICEDISC(settlement, maturity, discount, redemption, [basis]) | number | price of a discounted security: PRICEDISC(settlement, maturity, discount, redemption, [basis]) |
PRICEMAT(settlement, maturity, issue, rate, yld, [basis]) | number | price of a security paying interest at maturity: PRICEMAT(settlement, maturity, issue, rate, yld, [basis]) |
RECEIVED(settlement, maturity, investment, discount, [basis]) | number | amount at maturity of a fully invested security: RECEIVED(settlement, maturity, investment, discount, [basis]) |
TBILLEQ(settlement, maturity, discount) | number | bond-equivalent yield of a Treasury bill: TBILLEQ(settlement, maturity, discount) |
TBILLPRICE(settlement, maturity, discount) | number | price per 100 face of a Treasury bill: TBILLPRICE(settlement, maturity, discount) |
TBILLYIELD(settlement, maturity, pr) | number | yield of a Treasury bill: TBILLYIELD(settlement, maturity, pr) |
YIELD(settlement, maturity, rate, pr, redemption, frequency, [basis]) | number | yield of a periodic-coupon security (iterative): YIELD(settlement, maturity, rate, pr, redemption, frequency, [basis]) |
YIELDDISC(settlement, maturity, pr, redemption, [basis]) | number | annual yield of a discounted security: YIELDDISC(settlement, maturity, pr, redemption, [basis]) |
YIELDMAT(settlement, maturity, issue, rate, pr, [basis]) | number | annual yield of a security paying interest at maturity: YIELDMAT(settlement, maturity, issue, rate, pr, [basis]) |
NPV(rate, values OVER T) | number | net present value of the flows in item order, the first discounted one period (a missing item is skipped, not zero): NPV(rate, values OVER T) |
XNPV(rate, values, dates OVER T) | number | net present value of flows at dates, discounted from the first date (365-day years): XNPV(rate, values, dates OVER T) |
IRR(values OVER T, [guess=0.1]) | number | internal rate of return of the flows in item order (iterative): IRR(values OVER T, [guess=0.1]) |
XIRR(values, dates OVER T, [guess=0.1]) | number | internal rate of return of flows at dates (iterative): XIRR(values, dates OVER T, [guess=0.1]) |
MIRR(values OVER T, finance_rate, reinvest_rate) | number | modified internal rate of return, outflows financed and inflows reinvested: MIRR(values OVER T, finance_rate, reinvest_rate) |
FMRR(values OVER T, safe_rate, reinvest_rate, reinvest_min) | number | financial management rate of return (GNU Oleo): outflows pulled back at the safe rate, inflows of at least reinvest_min pushed forward at the reinvestment rate: FMRR(values OVER T, safe_rate, reinvest_rate, reinvest_min) |
FVSCHEDULE(principal, schedule OVER T) | number | principal compounded over the rates in item order: FVSCHEDULE(principal, schedule OVER T) |
OPT_BS(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes price of a European option: OPT_BS(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_BS_DELTA(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes delta: OPT_BS_DELTA(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_BS_GAMMA(spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes gamma (calls and puts alike): OPT_BS_GAMMA(spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_BS_RHO(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes rho: OPT_BS_RHO(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_BS_THETA(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes theta: OPT_BS_THETA(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_BS_VEGA(spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes vega (calls and puts alike): OPT_BS_VEGA(spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_BS_CARRYCOST(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) | number | Black-Scholes sensitivity to the cost of carry: OPT_BS_CARRYCOST(call_put, spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_GARMAN_KOHLHAGEN(call_put, spot, strike, time, domestic_rate, foreign_rate, volatility) | number | currency option: OPT_GARMAN_KOHLHAGEN(call_put, spot, strike, time, domestic_rate, foreign_rate, volatility) |
OPT_FRENCH(call_put, spot, strike, trading_time, calendar_time, rate, volatility, cost_of_carry) | number | Black-Scholes with trading-day volatility: OPT_FRENCH(call_put, spot, strike, trading_time, calendar_time, rate, volatility, cost_of_carry) |
OPT_JUMP_DIFF(call_put, spot, strike, time, rate, volatility, lambda, gamma) | number | Merton jump diffusion: OPT_JUMP_DIFF(call_put, spot, strike, time, rate, volatility, lambda, gamma) |
OPT_MILTERSEN_SCHWARTZ(call_put, p_t, f_t, strike, t1, t2, v_s, v_e, v_f, rho_se, rho_sf, rho_ef, kappa_e, kappa_f) | number | commodity futures option: OPT_MILTERSEN_SCHWARTZ(call_put, p_t, f_t, strike, t1, t2, v_s, v_e, v_f, rho_se, rho_sf, rho_ef, kappa_e, kappa_f) |
OPT_EXEC(call_put, spot, strike, time, rate, volatility, cost_of_carry, lambda) | number | executive stock option: OPT_EXEC(call_put, spot, strike, time, rate, volatility, cost_of_carry, lambda) |
OPT_FORWARD_START(call_put, spot, alpha, time_start, time, rate, volatility, cost_of_carry) | number | forward start option: OPT_FORWARD_START(call_put, spot, alpha, time_start, time, rate, volatility, cost_of_carry) |
OPT_TIME_SWITCH(call_put, spot, strike, a, time, m, dt, rate, cost_of_carry, volatility) | number | discrete time switch option: OPT_TIME_SWITCH(call_put, spot, strike, a, time, m, dt, rate, cost_of_carry, volatility) |
OPT_SIMPLE_CHOOSER(spot, strike, time1, time2, rate, cost_of_carry, volatility) | number | simple chooser option: OPT_SIMPLE_CHOOSER(spot, strike, time1, time2, rate, cost_of_carry, volatility) |
OPT_BAW_AMER(call_put, spot, strike, time, rate, volatility, cost_of_carry) | number | Barone-Adesi-Whaley American approximation: OPT_BAW_AMER(call_put, spot, strike, time, rate, volatility, cost_of_carry) |
OPT_BJER_STENS(call_put, spot, strike, time, rate, volatility, cost_of_carry) | number | Bjerksund-Stensland American approximation: OPT_BJER_STENS(call_put, spot, strike, time, rate, volatility, cost_of_carry) |
OPT_RGW(spot, strike, time_payout, time_exp, rate, d, volatility) | number | Roll-Geske-Whaley American call with one known dividend: OPT_RGW(spot, strike, time_payout, time_exp, rate, d, volatility) |
OPT_BINOMIAL(amer_euro, call_put, steps, spot, strike, time, rate, volatility, [cost_of_carry]) | number | Cox-Ross-Rubinstein binomial tree: OPT_BINOMIAL(amer_euro, call_put, steps, spot, strike, time, rate, volatility, [cost_of_carry]) |
OPT_COMPLEX_CHOOSER(spot, strike_call, strike_put, time, time_call, time_put, rate, cost_of_carry, volatility) | number | complex chooser option: OPT_COMPLEX_CHOOSER(spot, strike_call, strike_put, time, time_call, time_put, rate, cost_of_carry, volatility) |
OPT_ON_OPTIONS(type, spot, strike1, strike2, time1, time2, rate, cost_of_carry, volatility) | number | option on an option ("cc", "cp", "pc", "pp"): OPT_ON_OPTIONS(type, spot, strike1, strike2, time1, time2, rate, cost_of_carry, volatility) |
OPT_EXTENDIBLE_WRITER(call_put, spot, strike1, strike2, time1, time2, rate, cost_of_carry, volatility) | number | writer-extendible option: OPT_EXTENDIBLE_WRITER(call_put, spot, strike1, strike2, time1, time2, rate, cost_of_carry, volatility) |
OPT_2_ASSET_CORRELATION(call_put, spot1, spot2, strike1, strike2, time, cost_of_carry1, cost_of_carry2, rate, volatility1, volatility2, rho) | number | two-asset correlation option: OPT_2_ASSET_CORRELATION(call_put, spot1, spot2, strike1, strike2, time, cost_of_carry1, cost_of_carry2, rate, volatility1, volatility2, rho) |
OPT_EURO_EXCHANGE(spot1, spot2, qty1, qty2, time, rate, cost_of_carry1, cost_of_carry2, volatility1, volatility2, rho) | number | European option to exchange asset 2 for asset 1: OPT_EURO_EXCHANGE(spot1, spot2, qty1, qty2, time, rate, cost_of_carry1, cost_of_carry2, volatility1, volatility2, rho) |
OPT_AMER_EXCHANGE(spot1, spot2, qty1, qty2, time, rate, cost_of_carry1, cost_of_carry2, volatility1, volatility2, rho) | number | American option to exchange asset 2 for asset 1: OPT_AMER_EXCHANGE(spot1, spot2, qty1, qty2, time, rate, cost_of_carry1, cost_of_carry2, volatility1, volatility2, rho) |
OPT_SPREAD_APPROX(call_put, fut_price1, fut_price2, strike, time, rate, volatility1, volatility2, rho) | number | Kirk's futures spread option approximation: OPT_SPREAD_APPROX(call_put, fut_price1, fut_price2, strike, time, rate, volatility1, volatility2, rho) |
OPT_FIXED_STRK_LKBK(call_put, spot, spot_min, spot_max, strike, time, rate, cost_of_carry, volatility) | number | fixed-strike lookback: OPT_FIXED_STRK_LKBK(call_put, spot, spot_min, spot_max, strike, time, rate, cost_of_carry, volatility) |
OPT_FLOAT_STRK_LKBK(call_put, spot, spot_min, spot_max, time, rate, cost_of_carry, volatility) | number | floating-strike lookback: OPT_FLOAT_STRK_LKBK(call_put, spot, spot_min, spot_max, time, rate, cost_of_carry, volatility) |
OPT_BARRIER(spot, vol, r, rf, maturity, strike, lower, upper, rebate, put_call, in_out, continuous_or_end, [greek]) | number | barrier option: OPT_BARRIER(spot, vol, r, rf, maturity, strike, lower, upper, rebate, put_call, in_out, continuous_or_end, [greek]) |
OPT_TOUCH(spot, vol, r, rf, maturity, lower, upper, foreign_domestic, in_out, continuous_or_end, [greek]) | number | one/no-touch option: OPT_TOUCH(spot, vol, r, rf, maturity, lower, upper, foreign_domestic, in_out, continuous_or_end, [greek]) |
OPT_PROB_HIT(spot, vol, mu, maturity, lower, upper) | number | probability of touching a barrier: OPT_PROB_HIT(spot, vol, mu, maturity, lower, upper) |
OPT_PROB_INMONEY(spot, vol, mu, maturity, lower, upper, [strike], [put_call]) | number | probability of ending between the barriers (and in the money): OPT_PROB_INMONEY(spot, vol, mu, maturity, lower, upper, [strike], [put_call]) |
Engineering
Complex numbers are text, "3+4i" (suffix i or j); base conversions use 10-digit two's complement for negatives.
| Function | Returns | Description |
|---|---|---|
BIN2DEC(number) | number | binary text as a number |
BIN2HEX(number, [places]) | text | binary text as hexadecimal, zero-padded to places |
BIN2OCT(number, [places]) | text | binary text as octal, zero-padded to places |
DEC2BIN(number, [places]) | text | an integer in −512…511 as binary text |
DEC2HEX(number, [places]) | text | an integer in −2³⁹…2³⁹−1 as hexadecimal text |
DEC2OCT(number, [places]) | text | an integer in −2²⁹…2²⁹−1 as octal text |
HEX2BIN(number, [places]) | text | hexadecimal text as binary |
HEX2DEC(number) | number | hexadecimal text as a number |
HEX2OCT(number, [places]) | text | hexadecimal text as octal |
OCT2BIN(number, [places]) | text | octal text as binary |
OCT2DEC(number) | number | octal text as a number |
OCT2HEX(number, [places]) | text | octal text as hexadecimal |
BASE(number, radix, [min_length]) | text | an integer in 0…2⁵³−1 as text in a radix 2…36, zero-padded to min_length (also NUMTOBASE) |
DECIMAL(text, radix) | number | text in a radix 2…36 as a number (also BASETONUM) |
HEXREP(x) | text | the bytes of a number's IEEE double, little-endian, in hexadecimal |
BITAND(number1, number2) | number | bitwise and |
BITOR(number1, number2) | number | bitwise or |
BITXOR(number1, number2) | number | bitwise exclusive or |
BITLSHIFT(number, shift_amount) | number | shifted left by shift_amount bits (right if negative), at most 53 either way |
BITRSHIFT(number, shift_amount) | number | shifted right by shift_amount bits (left if negative), at most 53 either way |
CONVERT(number, from_unit, to_unit) | number | a measurement converted between units of Excel's table (SI and binary prefixes allowed); #N/A for unknown or mismatched units |
DELTA(number1, [number2=0]) | number | 1 if the numbers are equal (number2 defaults to 0), else 0 |
GESTEP(number, [step=0]) | number | 1 if number ≥ step (default 0), else 0 |
COMPLEX(real_num, i_num, [suffix="i"]) | text | the complex number re + im·i as text, with suffix "i" (default) or "j" |
IMREAL(inumber) | number | a complex number's real part |
IMAGINARY(inumber) | number | a complex number's imaginary part |
IMABS(inumber) | number | a complex number's modulus |
IMARGUMENT(inumber) | number | a complex number's angle in radians, −π…π (#NUM! at 0) |
IMCONJUGATE(inumber) | text | the complex conjugate |
IMNEG(inumber) | text | −z |
IMINV(inumber) | text | 1/z |
IMSUM(inumber1, …) | text | the sum of complex numbers |
IMPRODUCT(inumber1, …) | text | the product of complex numbers |
IMSUB(inumber1, inumber2) | text | z1 − z2 |
IMDIV(inumber1, inumber2) | text | z1 / z2 |
IMPOWER(inumber, number) | text | z raised to a real power |
IMSQRT(inumber) | text | the principal square root |
IMEXP(inumber) | text | e^z |
IMLN(inumber) | text | the principal natural logarithm |
IMLOG10(inumber) | text | the principal base-10 logarithm |
IMLOG2(inumber) | text | the principal base-2 logarithm |
IMSIN(inumber) | text | the complex sine |
IMCOS(inumber) | text | the complex cosine |
IMTAN(inumber) | text | the complex tangent |
IMSEC(inumber) | text | the complex secant |
IMCSC(inumber) | text | the complex cosecant |
IMCOT(inumber) | text | the complex cotangent |
IMSINH(inumber) | text | the complex hyperbolic sine |
IMCOSH(inumber) | text | the complex hyperbolic cosine |
IMTANH(inumber) | text | the complex hyperbolic tangent |
IMSECH(inumber) | text | the complex hyperbolic secant |
IMCSCH(inumber) | text | the complex hyperbolic cosecant |
IMCOTH(inumber) | text | the complex hyperbolic cotangent |
IMARCSIN(inumber) | text | the complex arcsine (principal branch) |
IMARCCOS(inumber) | text | the complex arccosine |
IMARCTAN(inumber) | text | the complex arctangent |
IMARCSEC(inumber) | text | the complex arcsecant |
IMARCCSC(inumber) | text | the complex arccosecant |
IMARCCOT(inumber) | text | the complex arccotangent |
IMARCSINH(inumber) | text | the complex inverse hyperbolic sine |
IMARCCOSH(inumber) | text | the complex inverse hyperbolic cosine |
IMARCTANH(inumber) | text | the complex inverse hyperbolic tangent |
IMARCSECH(inumber) | text | the complex inverse hyperbolic secant |
IMARCCSCH(inumber) | text | the complex inverse hyperbolic cosecant |
IMARCCOTH(inumber) | text | the complex inverse hyperbolic cotangent |
IMFACT(inumber) | text | the complex factorial z! = Γ(z + 1) |
IMGAMMA(inumber) | text | the complex gamma function Γ(z) |
BESSELI(x, n) | number | the modified Bessel function Iₙ(x) |
BESSELJ(x, n) | number | the Bessel function Jₙ(x) |
BESSELK(x, n) | number | the modified Bessel function Kₙ(x), x > 0 |
BESSELY(x, n) | number | the Bessel function Yₙ(x), x > 0 |
IMIGAMMA(a, inumber, [lower=TRUE], [regularize=TRUE]) | text | the complex incomplete gamma function of a and z: lower (default) or upper, regularized (default) or not |
The Desktop GUI
improv-gui is the egui/eframe desktop front-end, styled after the original
NeXTSTEP Lotus Improv: NeXT's four-level grayscale (no color anywhere, a gray
selection), flat controls with 1 px black outlines, worksheet windows with NeXT
title bars on a dark gray workspace, white grid cells, a formula list in each worksheet window, a floating application menu,
on-grid category tiles for pivoting, a model browser window and an Info panel.
Run it (from the Nix dev shell, which provides the GUI runtime libraries):
bash docs/demo/sample-model.sh sample.db
nix develop -c cargo run -p improv_gui -- sample.db
Pivoting by dragging the Region tile, paging, editing a Quantity cell while
the Revenue worksheet recomputes, selecting a range for its Sum, and adding
a formula. Recorded by docs/demo/gui-movie.sh.
The pivot grid
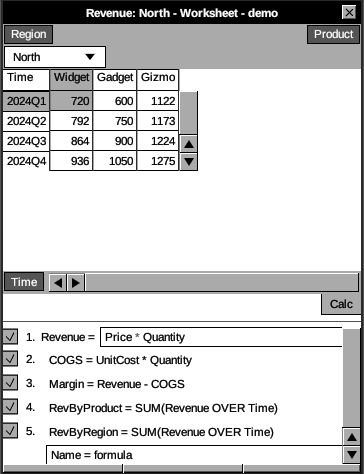
The window has five regions:
- Application menu (floating, top left) — NeXTSTEP's vertical menu. Drag
its black
Improvtitle bar to move it. An item marked with a triangle opens a submenu to its right; click it again, press Escape or click elsewhere to close it. Info ▸ Info Panel… shows or hides the Info panel; File ▸ Save saves the model, Revert to Saved reloads it from the store (the way out of a save conflict), and Import/Export CSV… opens the CSV wizard; Edit has Undo and Redo; Worksheet has Pivot, Add Matrix, Remove Matrix and Save View; View has Model Browser, which shows or hides the model browser, then lists the saved views, with a check on the current one, and picking one switches the workspace to it; Graph ▸ Show Chart toggles the chart; Help ▸ Functions… (also F1) opens the function help; Hide minimizes and Quit closes the window. Format, Print and Services, and New, Open, Save As and Close in the File menu, are not built yet and draw grayed out. Key equivalents, shown at the right of their item, take Ctrl (Cmd on macOS):ssave,zundo,Z(Shift+Z) oryredo,hhide,qquit. They don't fire while a text field has focus. - Model browser (window, bottom left of the workspace) — titled
<file> - Model. It leads with a white list of saved views, oneName - Worksheetrow each with a worksheet icon: click a row to select it and read its description below (measure, categories, pages); double-click to open it. Under that, a name field and Save view save the current canvas. Collapsed below are Categories (with their items) and Measures (each labeledinputorformulaat the right; click one to select it). Its close box hides it; View ▸ Model Browser brings it back. - Worksheet windows (center) — the dark gray workspace holds one
window per matrix, titled
<matrix> - Worksheet - <file>. Drag a title bar to move a window and its bottom bar to resize it (the left third drags the bottom-left corner, the right third the bottom-right). Clicking a window makes it key (black title bar) and gives its matrix the keyboard. With more than one matrix open, each window's close box removes its matrix. Worksheet ▸ Add Matrix opens another window, and Save View records every window's place and size. A fresh window opens right of the menu, sized to its grid. - Pivot grid (in each worksheet window) — the measure projected onto the
current axes. Here Revenue is shown with Product on columns, Time on rows,
and Region paged. The category tiles are dark-gray chips, placed as in
NeXT Improv: page tiles top-left, each above a white item field (click it to
pick the page shown;
[/]and PageUp / PageDown step it too), column tiles top-right, row tiles bottom-left beside the scroller. Drag a tile to another strip to re-pivot without touching the formula (the strips light up as drop targets only while you drag), or right-click it and choose Move to Rows / Columns / Pages. The same menu filters the category: uncheck an item to hide it from this worksheet, or choose Show all; a filtered tile readsName*. Cells are white with thin black rules; the selection and its row and column headers turn gray. Click a cell to select it; double-click it (or press Enter / F2) to edit, Enter to commit, Esc to cancel. Input cells carry a faint underline; hover a derived cell to see its formula. Arrows (orhjkl) move the cursor, andn/ Shift+nshow the next or previous measure. Shift+arrows, Shift+click or a drag select a range, and the status bar shows its Sum. - Formula list (bottom of each worksheet window) — every formula,
numbered, with a Calc button above and a checkbox that enables it.
Click a row to select its measure; the selected row becomes an editor:
Enter commits (re-typechecks and recomputes), Esc reverts. Type
Name = formulaon the last line and press Enter to add a measure. A formula that fails, in either editor, stays as typed with the fault underlined (see Formula errors). - Info panel (window, top right of the workspace, closed at start) — opened by Info ▸ Info Panel…: the selected measure's id, kind, value type, dimensions, dependencies, and formula. Its close box closes it.
- Status bar (bottom) — the last action's outcome (
saved model,recalculated,undo,added Margin, or an error) on the left, cleared after 5 seconds, and the selection's Sum on the right.
The native window title reads Improv — <file> (Untitled in memory), with
a trailing • while the model has edits that are not saved: any edit of an
in-memory model, or a model whose last autosave failed.
Function help
Help ▸ Functions…, or F1 from anywhere (a formula edit included), opens
the Functions window at the workspace's right: a search line, the matching
functions grouped by category with their signatures, and the selected
one's details. The search matches names, aliases and descriptions, best
first (pmt finds PMT, then IPMT, PPMT, …; payment finds them by
description). Up and Down move the selection. The details show the
signature with the parameter names (PMT(rate, nper, pv, [fv], [type]),
[optional], … repeating), the category and aliases, the description,
and the argument types. Insert, a double-click or Enter puts NAME(
into the formula you were editing (the selected row's, else the
Name = formula line), at the caret, and returns the keyboard to it.
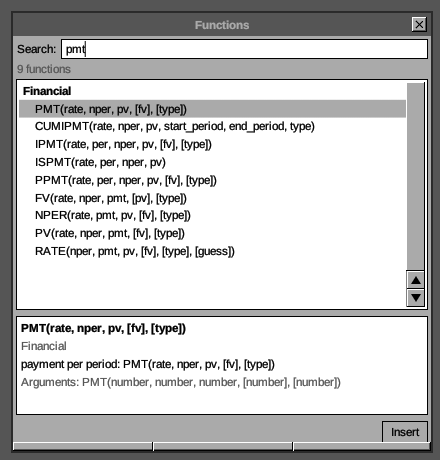
Autocomplete
Both formula editors complete as you type. Start a name (PM, Qua, or a
quoted 'Unit) and a list drops under the edit: matching functions with
their signatures and a dimmed one-line description, then the model's
measures and categories, at most eight. Up and Down move the selection;
Tab or Enter accepts it, Esc closes the list. With the list closed, Enter
commits the formula as before. Accepting a function writes NAME( with
the caret after the (; a measure or category named with spaces is
quoted for you ('Unit Cost').
While the caret is at the end of the text, the rest of the selected name
and its parameters trail it in light gray (PM shows T(rate, nper, pv, [fv], [type])). Inside a call the parameters still to give trail it: after
PMT(0.05, they read nper, pv, [fv], [type]). A tooltip over the edit
shows the signature with the argument the caret is in bold and
underlined, the description and the category.
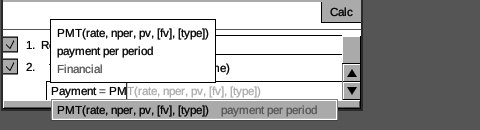
Formula errors
When a formula fails, the place it fails is underlined in the editor, and under the row are the message and, dimmed, why:
- an unknown measure or category:
did you mean Price?, the nearest names in the model (a misspelled function's suggestion is in the message itself:unknown function: PMTT; did you mean PMT?); - the wrong number of arguments: the call's name is underlined, the
message spells the parameters, and the hint says what is off,
missing pv: 2 given; - a
(never closed: that(is underlined,( opened here is never closed: add ); - an aggregation without
OVER: its form,IRR(values OVER T, [guess=0.1]).
A type or dimension error has no position, so the editor underlines the
first function or measure the message names (in Quantity + LEN(Price),
LEN). A row whose saved formula no longer compiles shows its error the
same way. Editing the text clears the mark.
Stacked axes
Drag the Region tile from the top-left pages strip onto the bottom row strip and the row axis becomes the stacked product of Time × Region:
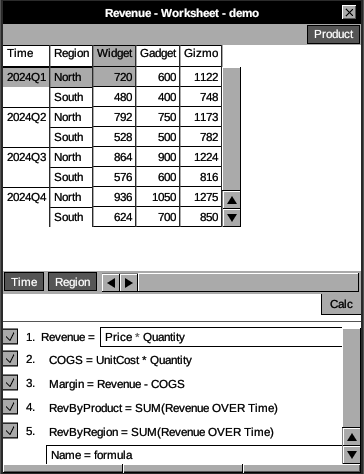
Each Time group (2024Q1, 2024Q2, …) now expands into its Region rows (North / South), with the outer Time label printed once per group. Any number of categories can stack on either axis; the grid renders the full Cartesian product, and rows are virtualized so a stacked axis of millions of lines stays responsive.
Incremental recalculation
Editing an input cell propagates as a delta through differential dataflow — only the touched cells and their dependents recompute. The same behavior on the CLI:
A model in Postgres
The GUI opens a model stored in Postgres from its URL,
improv-gui 'postgres://me@127.0.0.1/sales?sslmode=disable&model=plan'. Input
measures bound to a table show that table's rows, and editing a cell updates
the row. Here the price of Q1 Widget was changed in SQL, and the GUI shows
the recomputed revenue (1200):
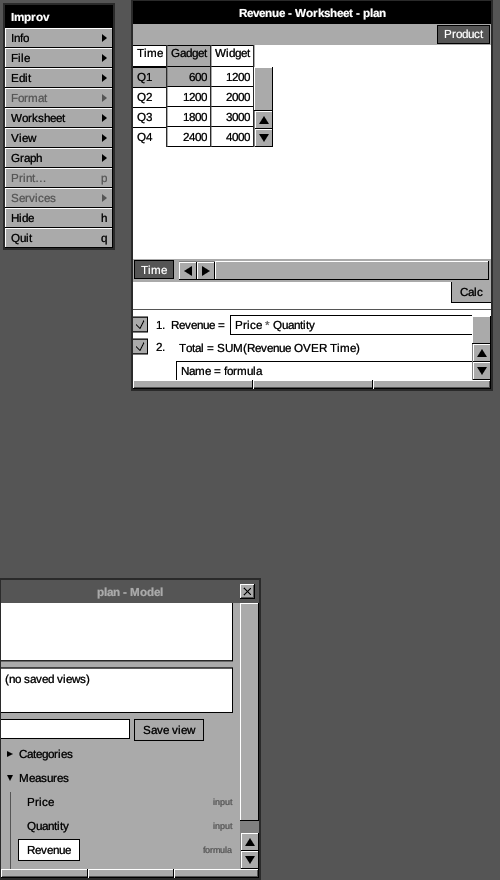
Recording the movie and screenshots
docs/demo/gui-movie.sh rebuilds the demo model, runs the GUI on a headless
X server and records the movie above with ffmpeg, driving it with
xdotool. scripts/gui-shot.sh takes the screenshot the CI compares
against its golden image.
Improv in Postgres (pg_improv)
pg_improv brings Improv's models to data that already lives in Postgres.
Your tables stay the source of truth for the data; the structure — the
categories, measures and formulas — is an Improv model stored in the improv
schema; the results of every derived measure land in ordinary tables
(improv_<model>.<measure>) that any SQL client can read, index, GRANT or
replicate. The same model opens in the desktop GUI.
Five-minute tour
# postgresql.conf (then restart)
shared_preload_libraries = 'pg_improv'
wal_level = logical
improv.database = 'sales'
CREATE EXTENSION pg_improv;
CREATE TABLE sales (quarter text, product text, price float8, qty float8,
                    PRIMARY KEY (quarter, product));
INSERT INTO sales VALUES ('Q1','Widget',10,100), ('Q1','Gadget',20,30),
                         ('Q2','Widget',10,200), ('Q2','Gadget',20,60);

SELECT improv.create_model('plan');
SELECT improv.bind_category('plan', 'Time',    'sales', 'quarter');
SELECT improv.bind_category('plan', 'Product', 'sales', 'product');
SELECT improv.bind_measure ('plan', 'Price',    'sales', 'price');
SELECT improv.bind_measure ('plan', 'Quantity', 'sales', 'qty');
SELECT improv.define('plan', 'Revenue = Price * Quantity');
SELECT improv.define('plan', 'Total = SUM(Revenue OVER Time)');

SELECT * FROM improv_plan.revenue;     -- kept current from here on
improv-gui "postgres://me@localhost/sales?model=plan"
A migration can re-run improv.define('plan', 'Revenue = …', replace => true): the same formula changes nothing (no version bump, no row
written), and a new one recomputes the measure and its dependents in the
same transaction, writing only the rows whose value changed. It is an
ERROR, naming the dependent, when the new formula would change the type a
dependent reads. improv.drop_measure('plan', 'Total') drops a measure
and its result table (an input's binding), and refuses while another
measure references it.
A named LAMBDA is defined the same way and called by any formula of the model:
SELECT improv.define('merit', 'LOGNORM = LAMBDA(x, c, LN1P(x) / LN1P(MAX(x OVER c)))');
SELECT improv.define('merit', 'An = LOGNORM(Authored, Person)');
c is a category parameter: the call passes a category. The lambda lives
in improv.lambda. Redefining it with replace => true recomputes every
measure that calls it, as redefining a measure does;
improv.drop_measure('merit', 'LOGNORM') drops it once nothing calls it.
The GUI shares the table, so a lambda defined in either place is called
from the other.
The GUI shows the model as worksheet windows. Editing a formula there
redefines it in Postgres; editing an input cell updates the bound row of
sales; everyone's SQL view of improv_plan.revenue follows.
Ways to keep results current
Transactions. In trigger and commit modes, and with
improv.recalc(), the results change inside the writer's transaction: other
sessions see them only once it commits, and ROLLBACK, an error or
ROLLBACK TO SAVEPOINT undo them with the change. trigger recomputes
after every write statement, so the writer reads its own new results.
commit recomputes once, just before COMMIT, so a read earlier in the
transaction sees the old results (call improv.recalc('plan') there to
read your writes). In logical mode the
results follow the commit in the worker's own transaction, and an aborted
write never reaches them at all, because logical decoding carries committed
transactions only. A batch's results and the slot's position commit
together, so a crash neither loses nor doubles a change.
logical (default) | trigger | commit | improv.recalc() | |
|---|---|---|---|---|
| Results update | after the commit, by a background worker | inside the writer's statement | inside the writer's transaction, just before COMMIT | when you call it |
| Consistency | eventual (lags the commit by one poll plus the change's own work) | transactional, read-your-writes | transactional; reads before COMMIT see the old results | transactional, in your snapshot |
| Writer pays | nothing (the worker applies only the changed cells) | the recompute, on every write statement | one recompute per transaction, of the written tables' dependents | the recompute, when you choose |
| On your tables | a publication (and REPLICA IDENTITY FULL if no PK) | four statement triggers each | nothing | nothing |
| Needs | wal_level = logical, preload, a PK or REPLICA IDENTITY FULL (set for you) | nothing | preload | nothing |
Switch with SELECT improv.set_sync_mode('plan', 'commit') (or 'logical',
'trigger', 'manual'). Entering trigger or commit mode recomputes
once. commit mode needs pg_improv in shared_preload_libraries (or
session_preload_libraries), because the hooks that notice a write must be
in every backend; set_sync_mode refuses it otherwise. A recompute that
fails at COMMIT rolls the transaction back with an error naming the
model. improv.recalc('plan') works in every mode, and
improv.recalc('plan', ARRAY['Price']) recomputes only what depends on Price.
improv.what_if('plan', '[{"measure":"Price","coord":{"Time":"Q1","Product":"Widget"},"value":12}]')
returns the derived cells that would change, writing nothing. Its value
column is jsonb: a number, true/false, a string, or a date as an RFC
3339 string, and an edit's "value" takes the same forms.
improv.status('plan') shows the mode and, in logical mode, the slot's lag
and how the worker applied its batches: incremental_applies counts the
batches it fed to the live engine, rebuilds its full reloads. On an
append-only fact table rebuilds stays put while incremental_applies
grows.
Several rows per coordinate
A fact table often has many rows per coordinate (one per order, say). Bind
the measure with an aggregate and each coordinate's rows are folded into
one input cell: improv.bind_measure('plan', 'Amount', 'orders', 'amount', agg => 'sum') (also avg, min, max, count, and count_distinct, SQL's
count(DISTINCT value_col); over a bool column, min and max are
SQL's bool_and and bool_or). Without agg, two rows on
one coordinate are an error. An aggregated measure is read-only from the
GUI: a save that edits one of its cells fails, so change the rows in SQL.
Value types
A measure's type comes from its column: numbers (int*, float*,
numeric), bool, text (text, varchar, char) and dates (date,
timestamp, timestamptz, kept to the millisecond in UTC). A derived
measure has the type of its formula, so improv.define('plan', 'Pricey = Price > 15') makes improv_plan.pricey a boolean column. Result tables'
value columns are double precision, boolean, text or timestamptz.
Other column types are refused by bind_measure. A derived measure with
no dimensions (MaxVol = MAX(Vol OVER Person) over a measure of Person
alone) gets a one-row result table with just the value column; it has no
row while the formula has no cell.
Logical and trigger sync follow a table's row changes, so in those modes
only tables bind; a view binds in manual mode (refresh with
improv.recalc()).
Choosing: use logical for busy tables (writers stay fast; measured
at 100k cells: 8 ms per UPDATE and its results visible ~50 ms later, vs
~1.1 s with a trigger). Use trigger when a
writer must read derived results in its own transaction. Use commit when
results must commit with the write but a transaction makes many writes (100
one-row updates in one transaction at 10k cells: 82 ms, against 6.6 s in
trigger mode), or when you can't put triggers on the tables. Use recalc
after bulk loads or inside migrations.
Functions written in Improv's language
LANGUAGE improv lets any role write a SQL function as an Improv formula:
CREATE FUNCTION bonus(sales float8, target float8) RETURNS float8
  LANGUAGE improv IMMUTABLE AS $$
    Ratio = sales / target
    MAX2(Ratio - 1, 0) * 1000
  $$;
SELECT rep, bonus(sales, target) FROM quota;
The SQL arguments are the inputs, by name; Name = expr lines define
intermediate measures; the last line is the result. Lines may be the DSL or
controlled English (price times qty). The semantics are the engine's: a
NULL argument gives NULL wherever the result depends on it, and an error
value (#DIV/0! from a division by zero, …) is NULL, or an ERROR with
improv.raise_errors = on. Aggregations need categories, so SUM(x OVER Time) is
rejected; put it in a model. A call costs about 0.14 µs for a one-line
body and 0.24 µs for bonus above. See
crates/pg_improv/README.md for the types and rules.
Upgrades and backups
pg_improv supports Postgres 15–18. To upgrade, install the new release,
restart Postgres, then run ALTER EXTENSION pg_improv UPDATE. pg_dump
keeps the models and their results. A restored database's worker makes a
new replication slot and catches up with one recompute.
Durability
In logical mode the worker writes a batch of results and advances its slot
in one transaction, so after a crash or pg_terminate_backend it
re-reads and re-applies; nothing is lost or counted twice, and rolled-back
writes never appear. A slot retains WAL until confirmed, so set
max_slot_wal_keep_size and watch improv.status(model).lag_bytes.
See crates/pg_improv/README.md for the full SQL API, limits
(improv.max_cells), and the benchmark table.
A family's finances in Postgres (pg_improv)
This chapter walks through a complete example: one family's books for
January to June 2026, kept in ordinary Postgres tables, with four Improv
models on top that reconcile the bank statements, track the budget, add up
net worth, and project the savings goals. The files are in
crates/pg_improv/examples/family-finance/ and
crates/pg_improv/tests/finance.sh runs them end to end and checks the
numbers below.
crates/pg_improv/tests/finance.sh       # scratch cluster on port 55460, ~10 s
KEEP=1 crates/pg_improv/tests/finance.sh  # leave it running to explore
psql -h ~/pgi-finance -p 55460 -U improv family
Or, in a database of your own (with pg_improv preloaded, see
Improv in Postgres):
psql -d family -f schema.sql -f data.sql -f model.sql -f queries.sql
The family
Dana (software engineer, W-2) and Sam (teacher, W-2, plus a design consulting business paid on 1099s) and their kids Maya (10) and Leo (6). They have:
- Bank accounts: joint checking, a joint savings account that holds three sinking funds, a tax-reserve savings account for the consulting income, and a high-yield savings rainy-day fund.
- Foreign currency: a euro checking account in Germany, plus euro and yen cash, converted to dollars at month-end rates.
- Two credit cards, paid in full by autopay.
- Retirement: Dana's 401(k) with an employer match, Dana's rollover traditional IRA, Sam's Roth IRA, and a family health savings account.
- College: a 529 plan for each child.
- Investing: a joint brokerage account and a crypto wallet (BTC, ETH), held as units and valued at each month's price.
- Property and debt: a house with a mortgage (interest, principal and escrow), a financed SUV with a car loan, and a paid-off sedan.
The schema at a glance
schema.sql creates schema finance. The tables fall into five groups:
| Group | Tables | Notes |
|---|---|---|
| Reference | currency, household, person, period, fx_rate, institution, account, envelope | account.account_type is one of checking, savings, credit, loan, mortgage, retirement, 529, health_savings, brokerage, crypto, fx_cash, asset. account.tracking says how its value is known: ledger, holdings or valuation. |
| Ledger | txn, ledger_month, statement | txn is what the family recorded: date, account, amount, currency, payee, envelope, transfer_id pairing the two legs of a transfer, and status (cleared or pending). statement is what each bank reports. |
| Income and taxes | income_source, invoice, income, tax_setaside | W-2 paystubs with withholdings and pre-tax deferrals; consulting invoices and the payments for them, with nothing withheld. |
| Investments, property, debt | security, price, holding, valuation, loan, loan_schedule | Units × price for investment accounts; a market estimate or depreciation for the house and cars; the amortization schedule for the two loans. |
| Plan | budget, plan_settings, savings_goal, goal_account, goal_horizon, goal_expense_window | Monthly budgets per envelope; goals with targets, contributions and return assumptions; precomputed compounding factors. |
Money is numeric(14,2) in the account's own currency. Signs follow the
household: a deposit is positive, a charge negative, so a credit card, loan or
mortgage has a negative balance (money owed). Banks report those as a
positive "balance owed", and account.balance_sign = -1 says how to
compare the two. Every table has a primary key, foreign keys and CHECKs
(for example income.net_deposit must equal gross minus every withholding
and deferral), and every table has a COMMENT.
There are 17 budget envelopes: housing, utilities, groceries, transport,
childcare, kids' activities, healthcare, insurance, subscriptions, dining,
travel and fun, gifts, giving, debt payments, estimated taxes, savings, and
bank fees. Each is essential, discretionary, savings, tax or fees.
What Improv does, and what SQL does
Improv's formulas compute over categories: SUM(Actual OVER Month) and
Price * Units. When this example was written they had no IF, no
POWER, no "previous month", and a result had to keep at least one
dimension, so it handles those in SQL. Improv now has all three (IF,
^ / POWER, PREV and running windows such as SUM(x OVER Month[FIRST..THIS]); see The Formula Language); the
example still shows the SQL route, which works on every Improv version. A
formula over a missing cell still has no cell unless it says otherwise
with COALESCE or FILL (IFERROR covers errors, not missing cells):
| Need | Where | How |
|---|---|---|
| Running balance per account | SQL: ledger_month | A table refreshed by statement-level triggers on txn and fx_rate (a MERGE of the running sum). Improv cannot refer to the previous period, and pg_improv cannot sync from a view (see below). |
Compound growth (1 + r/12)^n and annuity factors | SQL: goal_horizon | Filled by refresh_goal_horizon() with power(). Improv has no POWER. |
| "Is this envelope essential?", "is this money owed?" | Columns | 0/1 numbers (envelope.is_essential, account.balance_sign) multiplied into formulas. Improv has no IF, and a boolean cannot be multiplied. |
| A household-wide total | Improv, kept per Month or per Goal | UnreconciledCount[Month], NetWorth[Month]. There are no dimensionless results. |
| Loan amortization | SQL: loan_schedule | A recursive query, run once when the data is loaded. |
| Everything else | Improv | Differences, flags, variances, year to date, savings rate, the employer match, net worth, projections, shortfalls, what-ifs. |
All four models bind tables, not views. pg_improv can bind a view only in
manual mode: logical mode needs REPLICA IDENTITY and trigger mode
needs transition tables, and Postgres gives a view neither. So the running
balances are a trigger-maintained table, and that is also what lets the
logical sync below see a new transaction.
Model 1: reconciliation (recon)
Question: does each account's ledger match the bank statement, month by month?
Inputs, per (Month, Account): LedgerBalance and ClearedBalance (the
running sums from ledger_month), FxRate, TransfersHome (that month's
transfer legs in dollars), StatementBalance (from statement); per
Account: BalanceSign.
BankBalance       = StatementBalance * BalanceSign      -- a card's "$439.02 owed" is -439.02
Difference        = BankBalance - ClearedBalance        -- the bank has not seen pending charges
Reconciled        = ABS(Difference) < 0.005
Pending           = LedgerBalance - ClearedBalance
DifferenceHome    = Difference * FxRate                 -- euros in dollars
Unreconciled      = MIN2(FLOOR(ABS(Difference) * 200), 1)   -- 1 if off by >= half a cent
UnreconciledCount = SUM(Unreconciled OVER Account)      -- per Month
AbsDifferenceHome = ABS(DifferenceHome)
OffByHome         = SUM(AbsDifferenceHome OVER Account)
TransfersNet      = SUM(TransfersHome OVER Account)     -- both legs present: 0
TransfersBalanced = ABS(TransfersNet) < 0.005
Unreconciled is the IF workaround: FLOOR(|d| × 200) is at least 1
exactly when |d| ≥ 0.005, and MIN2(…, 1) caps it, so it is a 0/1 count.
data.sql plants five problems in June. The model finds four of them and
lists the fifth as pending:
== 1. Which accounts do not reconcile in June, and by how much?
   account   | bank_says | ledger_cleared | difference | difference_usd | pending
-------------+-----------+----------------+------------+----------------+---------
 amex        |   -439.02 |       -1963.14 |    1524.12 |        1524.12 | -412.00
 visa        |  -1668.40 |       -1754.80 |      86.40 |          86.40 |    0.00
 checking    |  21402.97 |       21427.97 |     -25.00 |         -25.00 |    0.00
 eur_account |   9183.10 |        9170.60 |      12.50 |          13.50 |    0.00

== 2. Reconciliation summary by month (accounts off, total off in USD, transfers in balance?)
  month  | accounts_off | off_by_usd | transfers_net | transfers_balanced
---------+--------------+------------+---------------+--------------------
 2026-05 |            0 |       0.00 |          0.00 | t
 2026-06 |            4 |    1649.02 |      -1524.12 | f
Reading it:
- Amex, +1524.12: a missing transaction. The June autopay was entered on
the checking side only. The card's leg is missing, so the ledger still
owes the May balance (1524.12), and June's transfers do not net to zero
(
TransfersNet = -1524.12). - Visa, +86.40: a duplicate. The June 20 Corner Market charge was entered twice.
- Checking, -25.00: a fee nobody entered. The bank charged an outgoing wire fee.
- Euro account, +12.50 EUR ($13.50): an FX difference. The family entered EUR 1,000 for the June wire; the bank's conversion credited EUR 1,012.50.
- Amex pending -412.00: a hotel hold that has not posted. It is in the
ledger as
pending, the bank does not show it yet, andDifferencecompares cleared balances, so it is not counted as a problem.
Reconciling a statement
Enter the bank's closing balance (positive for money owed), then look at
improv_recon.difference for that month. Fix the ledger and the results
update on their own. tests/finance.sh commits these four fixes:
BEGIN;
INSERT INTO finance.txn (txn_date, account_id, amount, payee, transfer_id)   -- the missing leg
VALUES ('2026-06-25', 'amex', 1524.12, 'Autopay, thank you', 'pay-amex-2026-06');
DELETE FROM finance.txn WHERE memo = 'entered twice';                         -- the duplicate
INSERT INTO finance.txn (txn_date, account_id, amount, payee, memo)           -- the FX difference
VALUES ('2026-06-05', 'eur_account', 12.50, 'Sparkasse Rhein', 'FX difference on the June wire');
INSERT INTO finance.txn (txn_date, account_id, amount, payee, envelope_id)    -- the fee
VALUES ('2026-06-05', 'checking', -25.00, 'Harbor CU: outgoing wire fee', 'bank_fees');
COMMIT;
Nothing calls improv.recalc. The txn triggers refresh ledger_month
in the same transaction. The pg_improv worker decodes the commit and applies
the changed rows. Within about 0.2 s every June Difference is 0,
UnreconciledCount is 0 and TransfersBalanced is true. The budget and
net-worth models follow too: groceries lose the duplicate, bank fees gain
the wire fee, and net worth rises by $1,599.02. The pending hotel hold is
still pending.
Model 2: cash flow and budget (budget)
Question: where did the money go, against the plan?
Outflow[Month, Envelope] is the ledger itself, bound with
agg => 'sum': every txn row with an envelope is summed into its
(month, envelope) cell. Rows with no envelope (income, opening balances, the
receiving leg of a transfer) have a NULL dimension and are skipped. Budget
comes from the budget table, IsSpending (0 for the savings envelope)
from envelope, and income from the income paystubs (again
agg => 'sum', per (Month, Source)).
Actual        = NEG(Outflow)                  -- spending is negative in the ledger
Variance      = Actual - Budget               -- > 0: overspent
OverBudget    = Actual > Budget               -- a boolean result
YtdActual     = SUM(Actual OVER Month)        -- per Envelope, January to date
YtdBudget     = SUM(Budget OVER Month)
YtdVariance   = YtdActual - YtdBudget
Spending      = SUM(SpendingPart OVER Envelope)   -- SpendingPart = Actual * IsSpending
SavedFromChecking = SUM(SavedPart OVER Envelope)  -- SavedPart = Actual * (1 - IsSpending)
EmployerMatch = MIN2(K401, Gross * MatchCap) * MatchRate
PayrollSaved  = SUM(PayrollSavedPart OVER Source) -- 401(k) + health savings deferrals + match
SavingsRate   = (SavedFromChecking + PayrollSaved) / TotalGross
Unallocated   = TotalNetPay - Spending - SavedFromChecking
SetAsideDue   = Gross * SetAsideRate              -- 30% of consulting income
SetAsideGap   = SetAsideDue - SetAside
The employer match is a formula on pay: 50% of the 401(k) deferral, counting deferrals only up to 6% of gross. Dana defers 10% of $6,500 a paycheck, so the match counts $780 of the $1,300 and adds $390 a month.
== 4. Where are we over budget in June?
 envelope  | budget  | actual  | over_by
-----------+---------+---------+---------
 fun       |  150.00 |  460.00 |  310.00
 childcare | 1200.00 | 1420.00 |  220.00
 groceries |  850.00 | 1050.11 |  200.11
 dining    |  250.00 |  309.05 |   59.05
 gifts     |   50.00 |   89.00 |   39.00
 utilities |  480.00 |  503.69 |   23.69

== 6. Income, saving and the savings rate, by month
  month  |  gross   | net_pay  | spending | saved_from_checking | saved_by_payroll | savings_rate_pct | left_over
---------+----------+----------+----------+---------------------+------------------+------------------+-----------
 2026-05 | 22600.00 | 16152.40 |  7907.48 |             4000.00 |          1990.00 |             26.5 |   4244.92
 2026-06 | 20400.00 | 13952.40 |  9455.65 |             4000.00 |          1990.00 |             29.4 |    496.75

== 8. Is enough of the consulting income in the tax reserve?
  month  |   source   |   due   |  moved  | short_by
---------+------------+---------+---------+----------
 2026-05 | sam_design | 1260.00 | 1000.00 |   260.00
June fun is over because of the $412 hotel hold. Groceries include the duplicate charge until it is fixed. Year to date (query 5), fun is $1,440 over, mostly next summer's flights.
Setting budgets
A budget is one row per (month, envelope) in finance.budget. To change
one, update the row and the variances follow:
UPDATE finance.budget SET amount = 300 WHERE month = '2026-06' AND envelope_id = 'dining';
A new envelope needs an envelope row and its budget rows. Spending
lands in it as soon as txn rows carry its id.
Model 3: net worth (networth)
Question: what do we own minus what do we owe, each month, in dollars?
Each account has exactly one of a ledger balance, holdings or a valuation. A formula over a missing cell has no cell, so the model totals each kind separately and adds the totals:
LedgerValue   = Balance * Fx                         -- euros and yen at the month-end rate
PositionValue = Units * Price                        -- per (Month, Account, Security)
HoldingsValue = SUM(PositionValue OVER Security)     -- 401(k), IRAs, health savings, 529s, brokerage, crypto
OwnedPart     = LedgerValue * (1 + Sign) / 2         -- Sign is 1 (owned) or -1 (owed)
OwedPart      = NEG(LedgerValue) * (1 - Sign) / 2
Cash          = SUM(OwnedPart OVER Account)
Investments   = SUM(HoldingsValue OVER Account)
Property      = SUM(Valuation OVER Account)          -- house and cars
Liabilities   = SUM(OwedPart OVER Account)           -- cards, car loan, mortgage
Assets        = Cash + Investments + Property
NetWorth      = Assets - Liabilities
DebtToAssets  = Liabilities / Assets
Crypto is just another holding: BTC and ETH units times their month-end price. The mortgage balance falls by each payment's principal (a transfer from checking). Interest and escrow are spending in the housing envelope.
== 9. Net worth trend (USD)
  month  | cash  | investments | property | liabilities | net_worth | change | debt_to_assets_pct
---------+-------+-------------+----------+-------------+-----------+--------+--------------------
 2026-01 | 50765 |      403326 |   586800 |      337733 |    703158 |        |               32.4
 2026-02 | 52969 |      412645 |   587800 |      336384 |    717030 |  13871 |               31.9
 2026-03 | 59195 |      409315 |   588800 |      335185 |    722124 |   5094 |               31.7
 2026-04 | 61837 |      427766 |   591300 |      333925 |    746978 |  24854 |               30.9
 2026-05 | 68524 |      443452 |   593300 |      334084 |    771191 |  24213 |               30.2
 2026-06 | 69278 |      455097 |   594300 |      333594 |    785081 |  13890 |               29.8
(The change column is SQL's lag() over the result table. Improv has no
previous-period reference, but a result table is an ordinary table.)
Model 4: planning (plan)
Question: at today's pace, will each goal be met, and if not, how much more a month would it take?
There are seven goals in savings_goal, each with a target date on a June 30:
| Goal | Funded by | Target |
|---|---|---|
| Retirement (Dana at 62, 2048) | 401(k), traditional IRA, Roth IRA | $2,500,000 |
| College for Maya (2034) and Leo (2037) | each child's 529 | $120,000 each |
| Rainy day (2027) | high-yield savings | 6 months of essential expenses |
| Summer 2027 trip | 50% of joint savings | $9,500 |
| Replace the sedan (2030) | 30% of joint savings | $24,000 |
| New roof (2028) | 20% of joint savings | $8,000 |
current_balance is the goal's share of its accounts on June 30. model.sql
reads it back from the net-worth model's result tables with an ordinary
UPDATE … FROM improv_networth.holdingsvalue.
goal_horizon holds, for each goal and each plan anniversary up to its
target date, Growth = (1 + r/12)^n and Annuity = ((1 + r/12)^n − 1) / (r/12)
(monthly compounding, end-of-month contributions), and IsTargetYear (1 on
the target date). SQL computes these; today (1 + Rate/12)^N in a
formula does it too.
EssentialPart     = Budget * IsEssential
EssentialBudget   = SUM(EssentialPart OVER Envelope)       -- per Month
WeightedEssential = EssentialBudget * Weight               -- Weight = 1/6 per month
MonthlyEssentials = SUM(WeightedEssential OVER Month)      -- the average, per Goal
Target            = TargetAmount + MonthsOfCover * MonthlyEssentials

Payroll           = DeferralRate * Salary / 12             -- 401(k) deferrals
EmployerMatch     = MIN2(DeferralRate, MatchCap) * MatchRate * Salary / 12
MonthlySaving     = Contribution + Payroll + EmployerMatch

Projected         = Current * Growth + MonthlySaving * Annuity   -- per (Goal, Year)
ProjectedAtTarget = SUM(TargetPart OVER Year)              -- TargetPart = Projected * IsTargetYear
AnnuityAtTarget   = SUM(AnnuityPart OVER Year)
Shortfall         = MAX2(Target - ProjectedAtTarget, 0)
OnTrack           = ProjectedAtTarget >= Target
ExtraMonthly      = Shortfall / AnnuityAtTarget            -- the saving that closes the gap
RequiredMonthly   = MonthlySaving + ExtraMonthly
Progress          = Projected / Target
The rainy-day target is a formula over the budget: six times the average
monthly essential budget (housing, utilities, groceries, transport,
childcare, healthcare, insurance and the car payment), $5,503.30, so
$33,019.80. Raise childcare's budget and the target moves.
IsTargetYear picks the target year's projection out of the series without
an IF. MAX2(…, 0) floors the shortfall.
== 11. Are we on track for each goal?
      goal       | target_date | today  | monthly | target  | projected | on_track | shortfall
-----------------+-------------+--------+---------+---------+-----------+----------+-----------
 rainy_day       | 2027-06-30  |  24839 |  500.00 |   33020 |     31962 | f        |      1057
 vacation        | 2027-06-30  |   5706 |  250.00 |    9500 |      8706 | f        |       794
 house_projects  | 2028-06-30  |   2282 |   50.00 |    8000 |      3482 | f        |      4518
 car_replacement | 2030-06-30  |   3424 |  100.00 |   24000 |      8224 | f        |     15776
 college_maya    | 2034-06-30  |  35980 |  250.00 |  120000 |     83066 | f        |     36934
 college_leo     | 2037-06-30  |  18766 |  250.00 |  120000 |     76365 | f        |     43635
 retirement      | 2048-06-30  | 306515 | 2190.00 | 2500000 |   2339882 | f        |    160118

== 12. How much more to save each month to close each shortfall?
      goal       | saving_now | add_monthly | required_monthly
-----------------+------------+-------------+------------------
 car_replacement |     100.00 |      328.68 |           428.68
 college_maya    |     250.00 |      313.69 |           563.69
 retirement      |    2190.00 |      293.14 |          2483.14
 college_leo     |     250.00 |      248.63 |           498.63
 house_projects  |      50.00 |      188.23 |           238.23
 rainy_day       |     500.00 |       86.51 |           586.51
 vacation        |     250.00 |       66.17 |           316.17
Reading the planning tables
improv_plan.projected(Goal, Year): the balance at each anniversary. Query 13 lists Maya's 529 year by year, reaching 69% of its target by 2034.improv_plan.shortfallandimprov_plan.ontrack(Goal): the gap at the target date.improv_plan.extramonthly(Goal): how much more to save each month, starting now, to close it. The sedan fund needs the most: $328.68 more a month.
The vacation line checks by hand: $5,705.98 today + 12 × $250 = $8,705.98, $794.02 short, closed by $794.02 / 12 = $66.17 more a month.
Changing goals
Goals are rows. Change a target, contribution or return in savings_goal
and the projections follow. Changing a return or a target date changes the
growth factors, so run SELECT finance.refresh_goal_horizon() afterwards.
What-if
improv.what_if evaluates the model with some inputs changed, in memory, and
returns only the derived cells that would differ. It writes nothing.
SELECT measure, coord ->> 'Goal' AS goal, value
  FROM improv.what_if('plan',
       '[{"measure": "DeferralRate", "coord": {"Goal": "retirement"}, "value": 0.15}]')
 WHERE measure IN ('Payroll', 'EmployerMatch', 'MonthlySaving',
                   'ProjectedAtTarget', 'Shortfall', 'ExtraMonthly', 'OnTrack');
== 14. What if Dana raises the 401(k) deferral from 10% to 15%? (writes nothing)
      measure      |    goal    |  would_be
-------------------+------------+------------
 ExtraMonthly      | retirement | 0.00
 MonthlySaving     | retirement | 2840.00
 OnTrack           | retirement | true
 Payroll           | retirement | 1950.00
 ProjectedAtTarget | retirement | 2694928.57
 Shortfall         | retirement | 0.00
EmployerMatch is missing from the answer because it does not change: the
match stops at 6% of pay. The extra $650 a month closes the whole $160,118
retirement gap.
Cutting dining out by $100 a month and putting it toward the trip is a change to the vacation goal's contribution (the plan model does not see dining):
== 15. What if we cut dining out by $100 a month and save it for the trip?
      measure      |   goal   | would_be
-------------------+----------+----------
 ExtraMonthly      | vacation | 0.00
 MonthlySaving     | vacation | 350.00
 OnTrack           | vacation | true
 ProjectedAtTarget | vacation | 9905.98
 Shortfall         | vacation | 0.00
what_if returns jsonb values, so OnTrack comes back as true, not a
number. Cast with care (value::numeric fails on a boolean).
Keeping it current
model.sql builds each model in manual mode and runs improv.recalc once,
so the results are complete when the script returns. Its last statement
switches every model to logical. From then on the background worker keeps
them current from committed changes to the bound tables. The test measures
0.1 to 0.2 s from commit to visible result.
Things to know
- Results are
double precision. A difference of 1524.12 may read1524.1200000000001. Round for display (round(value::numeric, 2)), and compare with a tolerance, asReconcileddoes. - Only derived measures get result tables. Read an input (a bound
column such as
Budget) from its own table. - Fill zeros, don't leave cells out.
savings_goalhas every column for every goal (0 where it does not apply), becauseContribution + Payrollhas no cell for a goal with noPayroll.
Files
| File | What |
|---|---|
schema.sql | Schema finance: tables, keys, checks, comments, the ledger_month and goal_horizon refreshers. |
data.sql | Six months of books, deterministic, with the five planted problems. |
model.sql | The four models. |
queries.sql | Fifteen questions answered from the result tables, the last two of them what-ifs. |
tests/finance.sh | Runs everything on a scratch cluster and checks 49 values, including the logical-sync fix-up. |
Improv in DuckDB
The improv DuckDB extension brings Improv's formula language and its
multidimensional models to DuckDB: evaluate any built-in function from SQL,
look functions up, and run a model over a table or a query, getting back one
row per computed cell.
Where pg_improv keeps a model in Postgres and keeps its
results current as the data changes, the DuckDB extension is stateless.
improv(source, model) reads the source, computes, and returns rows, the
way an analytical query does. Nothing is stored and there is nothing to
keep in sync.
Install
INSTALL improv FROM community;   -- once it is in the community registry
LOAD improv;
A local build (see crates/duckdb_improv/README.md) is unsigned:
duckdb -unsigned -c "LOAD 'crates/duckdb_improv/build/release/improv.duckdb_extension'; ..."
One binary loads into DuckDB v1.5.6 and later, v2.0 included.
Formulas: improv_calc
SELECT improv_calc('ROUND(PMT(rate/12, n, -pv), 2)',
                   json_object('rate', 0.06, 'n', 360, 'pv', 200000));
-- 1199.1

SELECT loan_id,
       improv_calc('ROUND(PMT(rate/12, years*12, -principal), 2)',
                   json_object('rate', rate, 'years', years, 'principal', principal)) AS payment
FROM loans;
improv_calc(formula [, inputs]) evaluates one formula in
Improv's formula language: operators, IF and its
family, LET, LAMBDA, and the scalar forms of the
built-in functions (math, rounding, statistics,
financial, text, dates, engineering). An aggregation over a category
(SUM(x OVER Time)) needs a model; use improv(...) for that.
- inputs is a JSON object:
json_object('x', col, ...)or a literal like'{"x": 2}'. Each key is a name the formula can use. Its JSON type is the input's type: number, boolean or text (DuckDB'sjson_objectwrites aDATEas text). A JSONnullis a missing input, and a result that depends on it is NULL:improv_calc('x + 1', '{"x": null}')is NULL, whileIF(TRUE, 5, x)is still 5. - The result is a
DOUBLE: a number; a boolean as 1 or 0; a date as its spreadsheet serial number (days since 1899-12-30). Text and error values (1/0is#DIV/0!) are NULL. - A formula that does not parse or type-check, or inputs that are not a
JSON object, fail the query with the reason:
improv_calc: parse error at 2: unexpected end of input. - A leading
=is allowed ('=ROUND(2.675, 2)'). - Each formula is compiled once per shape of inputs (names and types) and cached, so running one formula over a million rows parses it once.
improv_calc_text(formula [, inputs]) is the same but returns VARCHAR:
text results as they are, numbers to 15 significant digits, dates in RFC
3339, and errors as their codes.
SELECT improv_calc_text('1/0');                                     -- #DIV/0!
SELECT improv_calc_text('UPPER(name) & "!"', json_object('name', 'ada'));  -- ADA!
SELECT improv_calc_text('TEXT(EDATE(DATE(2024, 1, 31), 1), "yyyy-mm-dd")'); -- 2024-02-29
Function help: improv_functions
SELECT name, signature, description FROM improv_functions() WHERE category = 'financial';
SELECT name, signature FROM improv_functions(query := 'payment');
One row per built-in function (681): name, category
(math, financial, text, datetime, …), signature
(PMT(rate, nper, pv, [fv], [type])), returns
(number | boolean | text | date | any), description and aliases
(other spellings, or NULL). With query :=, only the functions whose name
or description matches, best match first.
Models: improv(source, model)
CREATE TABLE sales(year INTEGER, product VARCHAR, price DECIMAL(10,2), qty INTEGER);
INSERT INTO sales VALUES
  (2024, 'WidgetA', 10, 100), (2024, 'WidgetB', 20, 50),
  (2025, 'WidgetA', 11, 70), (2025, 'WidgetA', 11, 50), (2025, 'WidgetB', 20, 40);

SELECT * FROM improv('sales', '
  category Time = year
  category Product = product
  input Price = price max
  input Quantity = qty sum
  Revenue = Price * Quantity
  Share = Revenue / SUM(Revenue OVER Product)
  Growth = Revenue - PREV(Revenue, Time, 1, 0)
');
| measure | Time | Product | value | value_text |
|---|---|---|---|---|
| Revenue | 2024 | WidgetA | 1000.0 | 1000 |
| Revenue | 2024 | WidgetB | 1000.0 | 1000 |
| Revenue | 2025 | WidgetA | 1320.0 | 1320 |
| Revenue | 2025 | WidgetB | 800.0 | 800 |
| Share | 2024 | WidgetA | 0.5 | 0.5 |
| Share | 2025 | WidgetA | 0.6226415094339622 | 0.622641509433962 |
| … | ||||
| Growth | 2025 | WidgetB | -200.0 | -200 |
These are the values improv eval gives for the same model (the extension's
test suite checks that).
source is a table or view name, or a query: anything starting with
SELECT, WITH, FROM or VALUES, or in parentheses.
SELECT * FROM improv('SELECT * FROM sales WHERE year >= 2025', '...');
SELECT * FROM improv('read_csv(''sales.csv'')', '...');  -- not a query: use FROM
SELECT * FROM improv('FROM read_csv(''sales.csv'')', '...');
model has one item per line. Blank lines and lines starting with #
or -- are ignored, and keywords are case-insensitive.
category <Name> = <column>
input    <Name> = <column> [sum | avg | min | max | count]
<Name> = <formula>
categorymakes a dimension from a column. Its items are the column's distinct non-NULL values in the column's own order: numbers numerically, dates chronologically, text alphabetically.PREVandNEXTfollow that order. Each category becomes a result column of that name.inputis a measure read from a column, over every category. Two source rows on the same coordinate are an error unless the line names an aggregation, which then combines them (qty sumabove adds 2025's two WidgetA rows). Numeric columns of any type are numbers,BOOLEANis a boolean andVARCHARis text;countcounts any type.Name = formulais a derived measure: any formula over the inputs, the derived measures above it, and itself throughPREV(a running total isBalance = PREV(Balance, Time, 1, 0) + Deposits). Aggregations across a category (SUM(Revenue OVER Product)),RANK, running forms and the rest of the formula language all work.- A column name with spaces or capitals goes in double quotes:
category Time = "Fiscal Year". DuckDB matches column names case-insensitively. - A source row with a NULL category value is skipped; a NULL input value is no cell.
The result has one row per derived cell: measures in declaration order,
each measure's cells in item order. Its columns are measure, then one
VARCHAR column per category (NULL where the measure does not range over
that category: SUM(x OVER Product) has no Product), then
value DOUBLE (NULL for text, booleans and errors) and value_text
(every value as text; errors as #DIV/0!, …). It is an ordinary table
expression, so you can filter, join and pivot it:
PIVOT (SELECT * FROM improv('sales', '...') WHERE measure = 'Revenue')
  ON "Time" USING first(value) GROUP BY "Product";
Errors fail the query and name the line:
improv: model line 2: Quantity: two source rows have the coordinate (2025, WidgetA); add an aggregation (sum, avg, min, max, count or count_distinct) to the input line
improv: model line 1: the source has no column "yr" (it has: year, product, price, qty)
improv: model line 7: definition: parse error at 12: unknown measure: Revnue
Notes
- The source is read through the extension's own connections to the same
database (a small pool,
IMPROV_DUCKDB_POOL, default one per core up to 8). It sees committed data: not rows the calling transaction has written but not committed, and not the caller'sTEMPtables. Materialize those into a regular table first. - The whole result is computed at bind time, so it suits models up to a few
million cells. For a model that stays live as its data changes, use
pg_improv or
improv stream. - Enum and date inputs are not supported in models yet. A date column works as a category.
The HTTP Server
improv-server serves a JSON HTTP API over one model store:
improv-server model.db 127.0.0.1:3000   # or IMPROV_ADDR=...; model defaults to improv.db
improv-server 'postgres://me@127.0.0.1/sales?sslmode=disable&model=plan'
Endpoints
| Method | Path | Body | Notes |
|---|---|---|---|
| GET | /health | Public liveness probe. | |
| GET | /model | The whole model. | |
| GET | /measures | Id, name, kind, categories. | |
| GET | /measures/:id/values | Stored inputs, or computed values. | |
| POST | /measures/:id/eval | {"edits": [{"measure": 101, "coord": [[1, 10], [2, 20]], "value": 90}], "persist": false} | What-if edits through the live engine; "persist": true writes them. Ids are numeric; "value": null clears a cell. The answer names coordinates by category and item name. |
| POST | /measures/:id/cells | {"coord": {"dims": {"1": 10, "2": 20}}, "value": 90} | Set one input cell (category id → item id). |
| POST | /nl/parse | {"text": "revenue is price times quantity"} | Controlled English to a formula. |
| POST | /nl/describe | {"formula": …} | A formula (as /nl/parse returns it) to controlled English. |
| GET | /scheduler/status | Refresh scheduler state. |
Values written through the API are numbers.
Authentication
Every route except /health needs Authorization: Bearer <token> once a
token is configured. Tokens are compared in constant time.
| Variable | Meaning |
|---|---|
IMPROV_API_TOKEN, IMPROV_API_TOKENS | Read-write tokens (one, or comma-separated). |
IMPROV_API_TOKENS_RO | Read-only tokens (comma-separated). GETs and what-if /eval work; POST /cells and "persist": true return 403. |
IMPROV_ALLOW_OPEN=1 | Allow open mode (no tokens) on a non-loopback address. Without it the server refuses to start. |
Writes
A write must name an existing input measure and a coordinate with exactly one item for each of the measure's categories; values must be finite. Anything else is a 400. Writes are serialized, so concurrent writers do not lose updates. The server caches the loaded model. If another process (the GUI, the CLI, SQL on a Postgres model) saved since the server loaded it, the server's next write is refused with 409 Conflict, writing nothing, and the cache is dropped, so a retry reloads and succeeds. Reads serve the cached model until then.
Limits
| Limit | Value |
|---|---|
| Request body | 1 MiB (413 above) |
Edits per /eval | 10,000 (400 above) |
| Request time | 30 s (408), including time queued for a slot |
| Requests in flight | 64; the rest queue |
| Header read | 10 s; IMPROV_HEADER_TIMEOUT_MS overrides |
The server speaks HTTP/1.1 only.
Internal errors return {"error": "internal error", "request_id": N}; the
detail is logged to stderr under the same id.
Refresh scheduler
The scheduler refreshes CALL (external-function) measures in the
background. Refreshing runs code stored in the model, so it is off by
default.
| Variable | Meaning |
|---|---|
IMPROV_SCHEDULER=1 | Enable the scheduler. |
IMPROV_EXTFN_ALLOW | Path to the allowlist file. |
IMPROV_SCHEDULER_TICK_SECS | Tick period (default 5). |
The scheduler runs a function only if its digest is listed in the allowlist
file, one lowercase hex digest per line (# comments allowed). Other
functions are skipped, and a warning is logged. The digest is the SHA-256 of
the function name, a NUL byte and the body:
printf '%s\0%s' double 'result = args[0] * 2' | sha256sum
Scheduler refreshes always run in the Restricted sandbox, whatever the
function's pure flag says.
Controlled Natural Language
improv_nl_formula translates between formulas and a controlled natural
language: a small, fixed, deterministic grammar — not open-English NLP. There
are no LLMs and no external services. The same grammar parses a sentence into a
formula and renders a formula back into a sentence.
Two functions form the surface:
parse_nl_formula(ctx, text)→Formuladescribe_formula(ctx, formula)→String
Both take an NlContext built from a Model, which resolves measure and
category names (case-insensitively) to ids.
The grammar
sentence   = [ subject copula ] expr [ "." ]
subject    = measure-name          (* parsed, then discarded *)
copula     = "equals" | "is"

expr       = term { ("plus" | "+" | "minus" | "-") term }
term       = factor { ("times" | "*" | "divided" "by" | "/") factor }
factor     = number
           | agg-call
           | measure-ref
           | "(" expr ")"

agg-call   = ["the"] ("sum" | "average" | "min" | "max") "of" measure-ref
measure-ref= measure-name { dim-phrase }
dim-phrase = "over" cat-list                 (* aggregate over  -> DimensionSpec.over *)
           | ("by" | "for" "each") cat-list  (* keep / group by -> DimensionSpec.by   *)
cat-list   = category-name { "and" category-name }
Subject and copula are discarded
A sentence may open with <measure> equals or <measure> is, but the parser
strips it: the returned Formula is only the right-hand-side expression. The
target measure is a property of where the formula is stored, not of the
expression tree. So both of these parse to the same formula:
Revenue equals price times quantity.
price times quantity
The copula is only stripped when one actually follows the first word, so a bare
expression like price times quantity (no copula) still parses correctly.
Operators
| Phrase | Symbol | Operation |
|---|---|---|
plus | + | addition |
minus | - | subtraction |
times | * | multiplication |
divided by | / | division |
Precedence is the usual arithmetic one: times/divided by bind tighter than
plus/minus. So price times quantity plus revenue parses as
(price * quantity) + revenue. Parentheses override precedence.
Aggregation phrases
An aggregation reads as the <func> of <measure-ref> (the the is optional).
The function words map to the same function ids as the
formula language:
| Phrase | FuncId |
|---|---|
sum of | 1 |
average of | 2 |
min of | 3 |
max of | 4 |
Dimension phrases
A dimension phrase binds to the nearest preceding measure reference and fills in
that reference's DimensionSpec:
over <categories>setsover— the categories an enclosing aggregation collapses.by <categories>orfor each <categories>setsby— the categories to keep / group by.
Categories in a list are joined with and, e.g. over time and region.
The except field of a DimensionSpec is not expressible in this grammar.
A full example
the sum of revenue over time for each product
parses to a SUM call over a Revenue reference whose over = [Time] and
by = [Product] — i.e. total revenue per product, summed across years.
Round-trip and rendering
describe_formula is the inverse rendering. It uses a fixed vocabulary:
- Operators render as their words (
plus,minus,times,divided by). - Aggregations render as
the <func> of .... - A reference's
overrenders asover ...; itsbyrenders asfor each ...(notby).
So the example above renders back as:
the sum of Revenue over Time for each Product
Because describe uses for each for the by list and the grammar accepts
both by and for each, describe → parse is a stable round trip for the
supported constructs. Comparison and logical operators have best-effort English
renderings (is greater than, and, or, ...) so describe never fails, but
they are outside the parseable surface. The same holds for two more
renderings: unary minus describes as negative X, and a non-aggregating
function call as itself (ROUND(Price, 2), IF(…)); neither parses back,
so write those in the formula DSL.
Architecture & Design
Improv is a small Cargo workspace. Each crate has one job and depends only on the ones below it.
Crate layout
| Crate | Package | Purpose |
|---|---|---|
core_model | improv_core_model | Categories, items, measures, coordinates, formulas, values, and the formula text parser. No GUI or storage code. |
engine | improv_engine | Formula compiler and differential-dataflow evaluation: one-shot evaluate and the live session::Engine. |
verified | improv_verified | Small integer kernels the engine calls, with Verus specifications and machine-checked proofs (see Formal verification). |
nl_formula | improv_nl_formula | Controlled natural language ⇄ formula translation. |
storage_mentat | improv_storage_mentat | Model ⇄ datoms in an embedded, SQLite-backed Mentat file. |
storage_pg | improv_storage_pg | Model ⇄ the improv.* catalog in Postgres, with bound measures read from and written to their fact tables. |
store | improv_store | Store: one store type over both backends, picked by Store::open from the target (path or postgres://…?model=). |
storage_sql | improv_storage_sql | Import SQL query results into a model, export a measure to a table, refresh. SQLite, PostgreSQL, DuckDB. |
storage_csv | improv_storage_csv | Import a CSV/TSV file into a model; export a measure's cells (input or computed) to CSV/TSV. |
data_source | improv_data_source | The import bookkeeping shared by storage_sql and storage_csv: create categories and the measure, intern dimension values as items. |
extfn | improv_extfn | External functions. Python, R, Julia and Pure run in a sandboxed subprocess (bwrap on Linux); Wasm runs in-process on wasmi with fuel and memory limits. |
cli | improv_cli | The improv command-line tool. |
tui | improv_tui | improv-tui, a VisiCalc-style terminal pivot grid. |
gui | improv_gui | improv-gui, the desktop GUI (egui/eframe). |
server | improv_server | improv-server, a JSON HTTP API over a model store. |
pg_model | improv_pg_model | The Postgres-free core of pg_improv: catalog rows → Model, bound rows → cells, engine results → SQL. |
pg_improv | pg_improv | The Postgres extension (pgrx): Improv models over Postgres tables. A thin shell over SPI and pg_model. |
The computation pipeline
A derived measure's formula is compiled through a typed intermediate form into an operator plan, which is then built into a differential-dataflow graph and run. Input cells are fed as data; computed values come back out.
graph TD
    A["Model<br/>(measures + input cells)"] --> B["Formula (AST)"]
    B --> C["infer<br/>type + dimension inference"]
    C --> D["TypedExpr"]
    D --> E["build_plan<br/>insert Join / Aggregate"]
    E --> F["PlanNode graph"]
    F --> G["dataflow builder"]
    G --> H["differential-dataflow<br/>InputSession -> operators -> reduce"]
    A -. "typed input cells" .-> H
    H --> I["computed values<br/>measure -> (coord -> CellValue)"]
The two compiler passes (infer, build_plan) live in
engine::compiler; the plan node types in engine::plan; the dataflow builder
and the one-shot evaluate entry point in engine::dataflow.
PlanNode kinds map onto differential-dataflow operators:
PlanNodeKind | Dataflow operator |
|---|---|
InputMeasure | an InputSession collection (or an already built derived measure) |
Literal | a one-cell collection at the empty coordinate; as a MapBinary operand it is folded into the map closure instead |
MapUnary | map |
MapBinary | join on the shared categories, then map element-wise |
Join | re-key both sides to shared categories, join, rebuild the union key |
Aggregate | re-key to the group-by coordinate, then reduce (SUM/AVG/MIN/MAX) |
FuncCall | a scalar function (ABS, ROUND, …): map for one argument, join then map for two |
A final reduce collapses each key to a single value before results are
captured. Derived measures are built in dependency order, so one derived
measure can feed another; a cycle is rejected.
Why differential dataflow
Differential dataflow is a hard requirement of the design: the engine computes
incrementally, so an edit propagates as a delta and only the affected cells
recompute. The engine's spike (dd_revenue_is_incremental) proves this: after
computing Revenue = Price * Quantity, it changes one Quantity cell and
confirms the matching Revenue cell updates while an unaffected cell does not
recompute.
The version pin is deliberate and delicate — differential-dataflow = "=0.13.0" with timely = "=0.13.0". Newer DD pulls a timely line that does
not compile on the project's rustc; an older DD compiles but aborts on a
merge_batcher bug under debug assertions. 0.13.0 is the pair that both
compiles and runs. Do not bump it without re-validating.
The live engine
evaluate runs a model once and returns. Interactive users need more: change
one cell and see what it affects, without a rebuild. That is
engine::session::Engine.
Engine::new(model, targets) compiles the plans for the target derived
measures, then starts a dataflow on its own thread (timely's
execute_directly, one worker). Every input measure gets an InputSession.
The model's input cells are fed in at time 0. new returns the handle and
the first Snapshot.
After that the engine is fed edits:
#![allow(unused)]
fn main() {
pub struct Edit {
    pub measure: MeasureId,
    pub coord: CoordKey,
    pub value: Option<CellValue>, // None removes the cell
}
}
apply(edits) sends a batch over a channel. The worker retracts each cell's
old value, inserts the new one, advances time by one, and steps the dataflow
until the probe passes that time. Only the deltas flow, so only the affected
cells recompute. set and clear are one-edit shortcuts. The reply is the
new Snapshot.
A Snapshot is Arc<HashMap<MeasureId, Arc<MeasureValues>>>, where
MeasureValues is HashMap<CoordKey, CellValue>. It is copy-on-write:
cloning one is a reference-count bump, and measures an edit did not change are
shared with the previous snapshot. A changed measure is copied whole only
while a caller still holds the old snapshot.
The structure is fixed when the engine is built. Changing a formula or adding
a measure means building a new Engine. Dropping the handle stops the
thread.
session::input_cell(type, value) is the one rule for which model values are
engine cells. A value counts only when it matches its measure's declared type:
Number, Boolean, Text or DateTime. Text in a number measure, or an
error value, is no cell. Engine::new uses it to pick the seed cells, and the
GUI uses it to turn a cell edit into an Edit, so an edit and a rebuild
agree.
Users of the live engine:
| User | How |
|---|---|
TUI (improv-tui) | one engine per session; a numeric edit is Engine::set, any other value rebuilds the engine |
GUI (improv-gui) | one engine per session; edits go through input_cell and apply; rebuilt on structural changes |
improv stream | edits read from stdin, changed cells written to stdout |
server POST /measures/:id/eval | a short-lived engine per request, for what-if edits |
| pg_improv's logical worker | one engine per model in logical mode, fed the row changes of each batch |
The coordinate / value encoding for dataflow
Timely 0.13 needs dataflow data to be Clone + 'static, and data that crosses
an exchange channel to also be Send + Sync and serde
Serialize + Deserialize. Differential dataflow adds Ord + Debug, and keys
must be hashable. The model's Coordinate is a dynamic-arity BTreeMap and
Value holds an f64, which is neither Ord nor Hash. The engine encodes
at the dataflow boundary:
-
Key — a coordinate becomes a sorted
Vec<(u32, u32)>of(category_id, item_id)pairs (CoordKey). TheBTreeMapalready iterates in sorted order, so the encoding is deterministic andOrd + Hash.encode_coord/decode_coordconvert at the edge;project_keynarrows a key to a subset of categories (used for joins and group-bys). -
Value — the
CellValueenum:Variant Holds Num(u64)an f64asf64::to_bits(); decoded withf64::from_bitsBool(bool)a boolean Text(String)text Date(i64)a UTC timestamp, milliseconds since the Unix epoch Err(u8)an error, by kind, so errors propagate through operators CellValue::from_model_valueconverts a modelValue;Enumbecomes aNum. Arithmetic happens after decoding, insidemapandreduceclosures. -
Diff — the differential multiplicity
Rstaysisize.
This encoding is what cleared the project's Phase 1 viability gate.
Stores and front ends
Every front end opens a model through improv_store::Store::open. A path
opens a Mentat file; a postgres://…?model=<name> URL opens that model in
Postgres. Both backends have the same methods and the same conflict error, so
the GUI, TUI, CLI and server work on either without knowing which. See
Storage & Persistence.
pg_improv runs the same engine inside Postgres. A model's categories and
measures are bound to columns of ordinary tables, and each derived measure
is written to a result table (improv_<model>.<measure>) that any SQL
client can read. Three sync modes keep the results current: logical (the
default; a background worker follows the commit through logical decoding),
trigger (statement triggers recompute inside the writer's transaction), and
manual (results change when you call improv.recalc). See
Improv in Postgres.
Determinism
The core engine is deterministic and unit/property tested. The Time × Product
revenue model (with results 1000 / 1000 / 1200 / 1600) is the canonical fixture
checked by engine's tests, and each crate carries its own test module.
Formal verification
A few integer kernels of the engine are proven correct with
Verus, not just tested. They live in
crates/verified inside verus! { ... } blocks: a spec fn states what the
kernel means and the executable function ensures it. Under plain cargo the
specs are erased, and the engine calls these functions, so the proven code is
the code that runs. scripts/verify.sh (and a CI job) checks the proofs with
the pinned Verus release.
What is proven:
| Kernel | Used by | Proven |
|---|---|---|
gcd::gcd | GCD, LCM, the number-theory functions | The result is Euclid's gcd: it divides both arguments, every common divisor divides it, and gcd(a, 0) = a. |
gcd::lcm_below | LCM | The result is a positive common multiple, a / gcd(a, b) · b; it is None exactly when that reaches the cap (2⁵³), so the overflow check neither misses nor over-rejects. |
radix::encode / decode | DEC2BIN, BIN2DEC, … (radix 2, 8, 16) | decode(encode(v)) = v for every v in [−r¹⁰/2, r¹⁰/2); encode is None exactly outside that range; its digits are each below the radix, at most 10, and 10 for a negative v. decode rejects more than 10 digits or a digit not below the radix, and otherwise means exactly 10-digit two's complement. |
radix::to_digits | BASE, and the above | The digits (radix 2–36) are each below the radix, have no leading zero, and are worth exactly the input. |
bits::and / or / xor / shl / shr | BITAND, BITOR, BITXOR, BITLSHIFT, BITRSHIFT | For operands below 2⁴⁸: every result stays below 2⁴⁸; and is at most either operand, or at least; shl is exactly x · 2ⁿ (below 2¹⁰¹, no overflow) and shr exactly ⌊x / 2ⁿ⌋ for shifts up to 53. |
graph::build_order | the derived-measure build order (derived_build_order) | The depth-first post-order from the targets holds exactly the measures reachable from them, each once and after every measure it depends on; it fails exactly when a dependency cycle is reachable. So building a model's dataflow always terminates, and a cyclic model is always rejected. |
take::range | TAKE, DROP | The kept index range is in bounds (from ≤ to ≤ len) and holds m values for TAKE, len − m for DROP; TAKE and DROP of one count partition the list. |
keys::project | every join key and group-by (project_key) | Exactly the pairs whose category is kept, in their order; a sorted key projects to a sorted key. |
keys::union_keys | every dimensional join | A merge of two sorted keys: sorted with no category twice, contains every pair of both when they agree on shared categories, and nothing else. |
What is tested instead: everything with floating point. Verus does not reason
about f64 arithmetic, so the kernels take and return integers and the engine
does the float range checks and truncation before calling them. The numeric
functions are checked against LibreOffice and Gnumeric goldens
(crates/engine/tests/data), and invariants (parse ⇄ print, save ⇄ load,
key encoding) by property tests.
Storage & Persistence
improv_storage_mentat persists a Model to an embedded, SQLite-backed
Mentat store — a Datomic-style datom
database. Categories, items, measures, and input cells are stored as
first-class entities, so the model is queryable, not an opaque blob.
ModelStore::open(path) opens (or creates) a store; pass "" for an in-memory
database. Opening transacts the schema (a no-op after the first time).
save_model writes the model; load_model rebuilds it by querying.
Front ends do not use ModelStore directly. They open
improv_store::Store, which can also open a model kept in Postgres (see
The Postgres store).
The datom schema
The schema is defined as an EDN transaction in
improv_storage_mentat::schema::SCHEMA_EDN. It declares these attributes.
Category
| Attribute | Value type | Cardinality | Notes |
|---|---|---|---|
:category/id | long | one | unique/identity, indexed |
:category/name | string | one |
Item
| Attribute | Value type | Cardinality | Notes |
|---|---|---|---|
:item/id | long | one | unique/identity, indexed |
:item/name | string | one | |
:item/category | ref | one | reference to a category entity |
Measure
| Attribute | Value type | Cardinality | Notes |
|---|---|---|---|
:measure/id | long | one | unique/identity, indexed |
:measure/name | string | one | |
:measure/value-type | string | one | the declared value type |
:measure/categories | ref | many | the measure's tensor dimensions (a set) |
:measure/category-order | string | one | JSON array of category ids: the order of the set above. Coordinates and SQL/CSV columns depend on it. Absent in older stores, which load sorted by id. |
:measure/kind | string | one | "input" or "derived" |
:measure/description | string | one | optional |
:measure/formula | string | one | JSON-serialized Formula, on derived measures |
:measure/sql-source | string | one | JSON SqlSource (query, dimension columns, value column, refresh policy), on SQL-backed measures |
Cell (an input value)
| Attribute | Value type | Cardinality | Notes |
|---|---|---|---|
:cell/key | string | one | unique/identity, indexed — synthetic measure::coord key |
:cell/measure | ref | one | reference to the owning measure |
:cell/coord | string | one | JSON-serialized Coordinate |
:cell/value-number | double | one | present for numeric cells |
:cell/value-boolean | boolean | one | present for boolean cells |
:cell/value-text | string | one | present for text cells |
View (a saved pivot layout)
| Attribute | Value type | Cardinality | Notes |
|---|---|---|---|
:view/id | long | one | unique/identity, indexed |
:view/json | string | one | the whole view, as JSON |
Meta (one entity per store)
Maps with no natural per-entity shape are stored as JSON on a singleton.
| Attribute | Value type | Cardinality | Notes |
|---|---|---|---|
:meta/singleton | long | one | unique/identity, indexed; always the same value |
:meta/external-fns | string | one | JSON: external function definitions |
:meta/external-calls | string | one | JSON: CALL(...) measures and their arguments |
:meta/scenarios | string | one | JSON: scenarios |
How a model maps to datoms
-
Native attributes. Ids, names, kinds, and value types map straight to native datom value types (
long,string,boolean,double,ref). -
Formulas and coordinates are JSON. A
FormulaAST and aCoordinateare serialized with serde to JSON strings and stored in:measure/formulaand:cell/coord. This is why a derived measure's formula survives a round trip even though the datom layer has no notion of an expression tree. Views, the SQL source of a measure, and the meta maps are JSON too. -
Category order.
:measure/categoriesis a set, so the store loses its order.:measure/category-orderkeeps it. On load the categories are sorted by that list. A category the list does not name sorts after those it does. -
Typed cell values. A cell writes exactly one of the three typed value attributes, chosen by the value's type:
Value Attribute Number,Enum:cell/value-numberBoolean:cell/value-booleanText,DateTime(RFC 3339 text):cell/value-textAn
Errorvalue cannot be saved as an input; the save fails withIntegrity. -
Cell identity. Each cell is keyed by a synthetic string
"<measure-id>::<coord-json>"on:cell/key, which isunique/identity. Re-saving the same measure+coordinate updates the cell in place.
Save
save_model is one SQLite transaction. It calls
Store::begin_transaction once, makes several transact calls inside it, and
calls commit once at the end. Later steps can use lookup-refs (for example
:item/category, :measure/categories, :cell/measure) to entities that
earlier steps wrote but have not committed yet. If any step fails, the
transaction is dropped without a commit and nothing is written.
The steps run in this order:
| Step | What is transacted |
|---|---|
| 1 | categories |
| 2 | items |
| 3 | measures |
| 4 | cell retractions |
| 5 | cells |
| 6 | views |
| 7 | meta (only if the model has external functions, external calls, or scenarios) |
Each step is split into transact calls of at most
MAX_DATOMS_PER_TRANSACT (2000) datoms. Mentat aborts the process (a hard
assert!, not an error) on a transact carrying 5461 or more datoms for one
attribute queue. The chunks share the one transaction, so the save is still
all-or-nothing.
A single entity cannot be split. A measure carries one :measure/categories
datom per category, so a measure with more than 5460 categories is refused
up front with StoreError::Integrity, before anything is written.
Cells are diffed
Before writing cells, the save reads every stored cell and compares:
- a cell whose stored value is unchanged is skipped (no datoms);
- a cell whose value changed is re-asserted;
- a value left under another type's attribute (the cell held text and now holds a number, say) is retracted;
- a stored cell the model no longer has is retracted whole.
After a save, the store's cells are exactly model.inputs.
What is not retracted
Only cells are diffed. Categories, items, measures and views that the model no
longer has are not retracted; they stay in the store and come back on the
next load. Stale :measure/categories refs are not retracted either: re-save a
measure with a changed category set and the store keeps the union. A loaded
model can therefore grow past the 5460-category limit without any single save
having been that wide. The source marks this as a known bug (see the comments
in save_model).
Optimistic concurrency
load_model records the store's high-water transaction, read live from
SQLite by TX_HIGH_WATER_SQL. It is the newest transaction in the log that
changed anything other than :db/txInstant, so the schema transact every
open performs does not count as a write.
save_model re-reads the high-water inside its transaction. If another writer
has committed since this handle loaded (or last saved), the save returns
StoreError::Conflict and writes nothing. A handle that never loaded saves
unconditionally. loaded_tx and set_loaded_tx carry the token between
handles, for callers that open the store fresh for each save.
To recover from a conflict, read the model again. reload_model does that;
it is the same as load_model. The GUI's File ▸ Revert to Saved and the
TUI's R key do the same thing: they open the store, load the model with a
fresh token, and rebuild the engine. The conflicting edit is lost; the other
writer's changes are picked up.
Load
load_model runs Datalog queries and rebuilds the Model:
- categories, then items (each relinked to its category);
- measures: one query for the required fields, then per measure one query each for the formula (derived measures only), description, categories, category order, and SQL source;
- cells: one query per typed value attribute (three in all), each
returning
(measure id, coord, value)rows. The value is decoded by the owning measure's declared type. If an old store holds a cell under more than one attribute, the attribute matching the declared type wins; - views and the meta singleton.
load_partial(measure_ids) loads the same structure, views and meta, but only
the cells of measure_ids and their dependency closure (every measure reached
through a derived formula or an external call's arguments). The filter is in
the query. The handle remembers that closure, and its next save retracts
only the closure's missing cells, so a partial model saves safely: cells of
measures it never loaded stay as they are. A full load lifts the limit again.
The Postgres store
improv_store::Store is the one store type the GUI, TUI, CLI and server use.
Store::open(target) looks at the target:
| Target | Backend |
|---|---|
starts with postgres:// or postgresql:// | improv_storage_pg::PgModelStore |
anything else (a path; "" for in-memory) | improv_storage_mentat::ModelStore |
Both backends have the same methods: load_model, load_partial,
save_model, reload_model, tx_high_water, loaded_tx, set_loaded_tx.
A conflict from either backend becomes improv_store::StoreError::Conflict.
A Postgres target names one model: postgres://me@db/sales?model=plan.
split_model_url removes the model parameter and passes the rest to the
driver. ?model= is required; without it open fails. Opening a model name
that does not exist yet creates it.
The catalog
The model is stored normalized in the improv schema. The DDL is
CATALOG_SQL in crates/storage_pg/src/lib.rs:
| Table | Holds |
|---|---|
improv.model | one row per model: name (unique), sync_mode (logical, trigger, manual), slot_name |
improv.category | categories, keyed by (model_id, id) |
improv.item | items, with category_id |
improv.measure | name, value_type, kind, formula, description, categories bigint[] |
improv.binding | a measure bound to a fact table: rel, value_col, dim_cols (category name → column), optional agg (sum, avg, min, max, count) |
improv.cell | unbound input cells: coord jsonb, value jsonb |
improv.view | saved views, layout jsonb |
improv.meta | one blob jsonb per model: external functions, external calls, scenarios, SQL sources |
improv.model_version | one tx counter per model: the conflict token |
CATALOG_SQL also creates the unique index item_name_uniq on
(model_id, category_id, name) and the function improv.mint_items, which
assigns ids to item names it has not seen. The pg_improv extension uses the
same function.
open creates the catalog, under an advisory lock, when
improv.mint_items does not exist. When the pg_improv extension is installed
the function exists, so the client runs no DDL and the extension owns the
tables. The extension's catalog is the same plus improv.category_binding,
which records the column that supplies a bound category.
Formulas are written as JSON of the Formula AST. On load, a formula that is
not JSON is parsed as formula text (Target = expr), which is what the
extension's improv.define writes. Cell values are JSON scalars; dates are
RFC 3339 strings.
Bound and unbound cells
A measure with a binding row lives in its fact table. Load runs
SELECT dims…, value FROM rel (with GROUP BY when the binding has an
agg). Dimension values map to items by name; names with no item are minted
by improv.mint_items. A row with a NULL value is no cell; a row with a NULL
dimension is ignored. Two rows on one coordinate of an unaggregated binding
are an Integrity error. Cells of unbound measures come from improv.cell.
Load reads in one REPEATABLE READ, read-only transaction. Item minting runs
after it closes, read-committed, so it sees items other clients minted. The
handle keeps a snapshot of what it loaded.
Save
save_model is one transaction. It locks the model's model_version row and
returns Conflict if tx moved since this handle loaded. Then it writes the
diff against the snapshot:
- categories, items, measures and views are upserted; only rows the snapshot held but the model dropped are deleted, so rows another client added survive;
- bound cells that were added, changed or removed are written to the fact
table with a guarded
UPDATE … WHERE <dims> AND value IS NOT DISTINCT FROM <loaded value>. A removed cell sets the value column to NULL and keeps the row. An added cell with no row isINSERTed. If a guard matches no row, or several, SQL changed that cell since the load, and the save fails withConflict. The save never runs DDL and never deletes a fact-table row; - an aggregated measure is read-only: a save that changes one of its cells
fails with
Integrity; - unbound cells that changed are upserted into
improv.cell, and removed ones are deleted; - the meta blob is replaced, and
model_version.txis incremented.
A handle with no snapshot (it never loaded) writes the whole model unchecked
and deletes rows the model lacks. As with the Mentat store, a partial model
from load_partial saves safely through the handle that loaded it, since the
diff only touches what it loaded.
Store::save_token carries both the version and the snapshot to a later
handle, for callers that reopen the store per save.
Transport
This build has no TLS. open refuses:
sslmode=require, which cannot be honoured (use an SSH tunnel to a loopback port);- any host that is not
localhost, a loopback address, or a Unix socket, unless the URL setssslmode=disableexplicitly, since the password would cross the network in cleartext.
A connect error that is not from the database is reported without the connection string, so a password in the URL is not echoed.
For the extension itself (binding tables, result tables, sync modes) see Improv in Postgres (pg_improv).